This is the full developer documentation for Riptides
# Controlling Agent Access
Access Control is where you set guardrails on your AI agents: which **models** each agent may call on a given provider, which **tools** it may use on a given connector, and whether those rules apply when the agent runs autonomously or when a specific person is driving it. By default everything is allowed; you add **restrictions** only for the providers and connectors you want to narrow, and Riptides enforces those inline before the request reaches the provider.
Open it from **Agentic → Access Control** in the sidebar.
## How access is decided
[Section titled “How access is decided”](#how-access-is-decided)
Three ideas drive everything on this screen.
**Default allow, restrict where you add a rule.** An agent with no policy, or an empty policy (no rules), has **full access**: it can use any model and any tool. Traffic to a provider or connector stays allowed unless the policy contains an explicit rule for that service. When you add a rule for a provider or connector, that service becomes restricted: only the models or tools you list there are permitted, and everything else on that service is blocked. Providers and connectors you never add a rule for remain unrestricted. So this is not a global denylist. It is always-allow, except where you place a restriction.
**A policy targets one agent, optionally scoped to one person.** For a single agent (workload identity) you can have:
* an **Autonomous Operation** policy: the rules that apply when the agent runs with no human driving it; and
* one policy **per user**: rules that apply only when that specific person is driving the agent.
**Which policy applies depends on who is driving the agent, and there is no fallback between them:**
| Who is driving | Policy used |
| ---------------------------------------------- | ---------------------------------------------------------------------- |
| No one (autonomous) | Autonomous Operation policy, if it exists |
| A user who has their own policy for this agent | That user’s policy |
| A user with **no** user policy for this agent | Full access (pass-through), even if Autonomous Operation is restricted |
So a restricted Autonomous Operation policy does **not** constrain human-driven sessions unless you also create a user policy for that person. This lets you, for example, lock the agent down when it runs unattended while giving a senior engineer a broader (or separate) set of restrictions when they drive it, but anyone without a user policy remains unrestricted.
## The workloads list
[Section titled “The workloads list”](#the-workloads-list)
The dashboard lists each agent (workload identity) that has policies, with:
* **Workload Identity**: the agent, such as `claude` or `codex`.
* **LLMs** and **Connectors**: how many providers and connectors its policies restrict.
* **Autonomous**: whether the agent’s autonomous operation is **Restricted** or **Not restricted** (full access when running on its own).
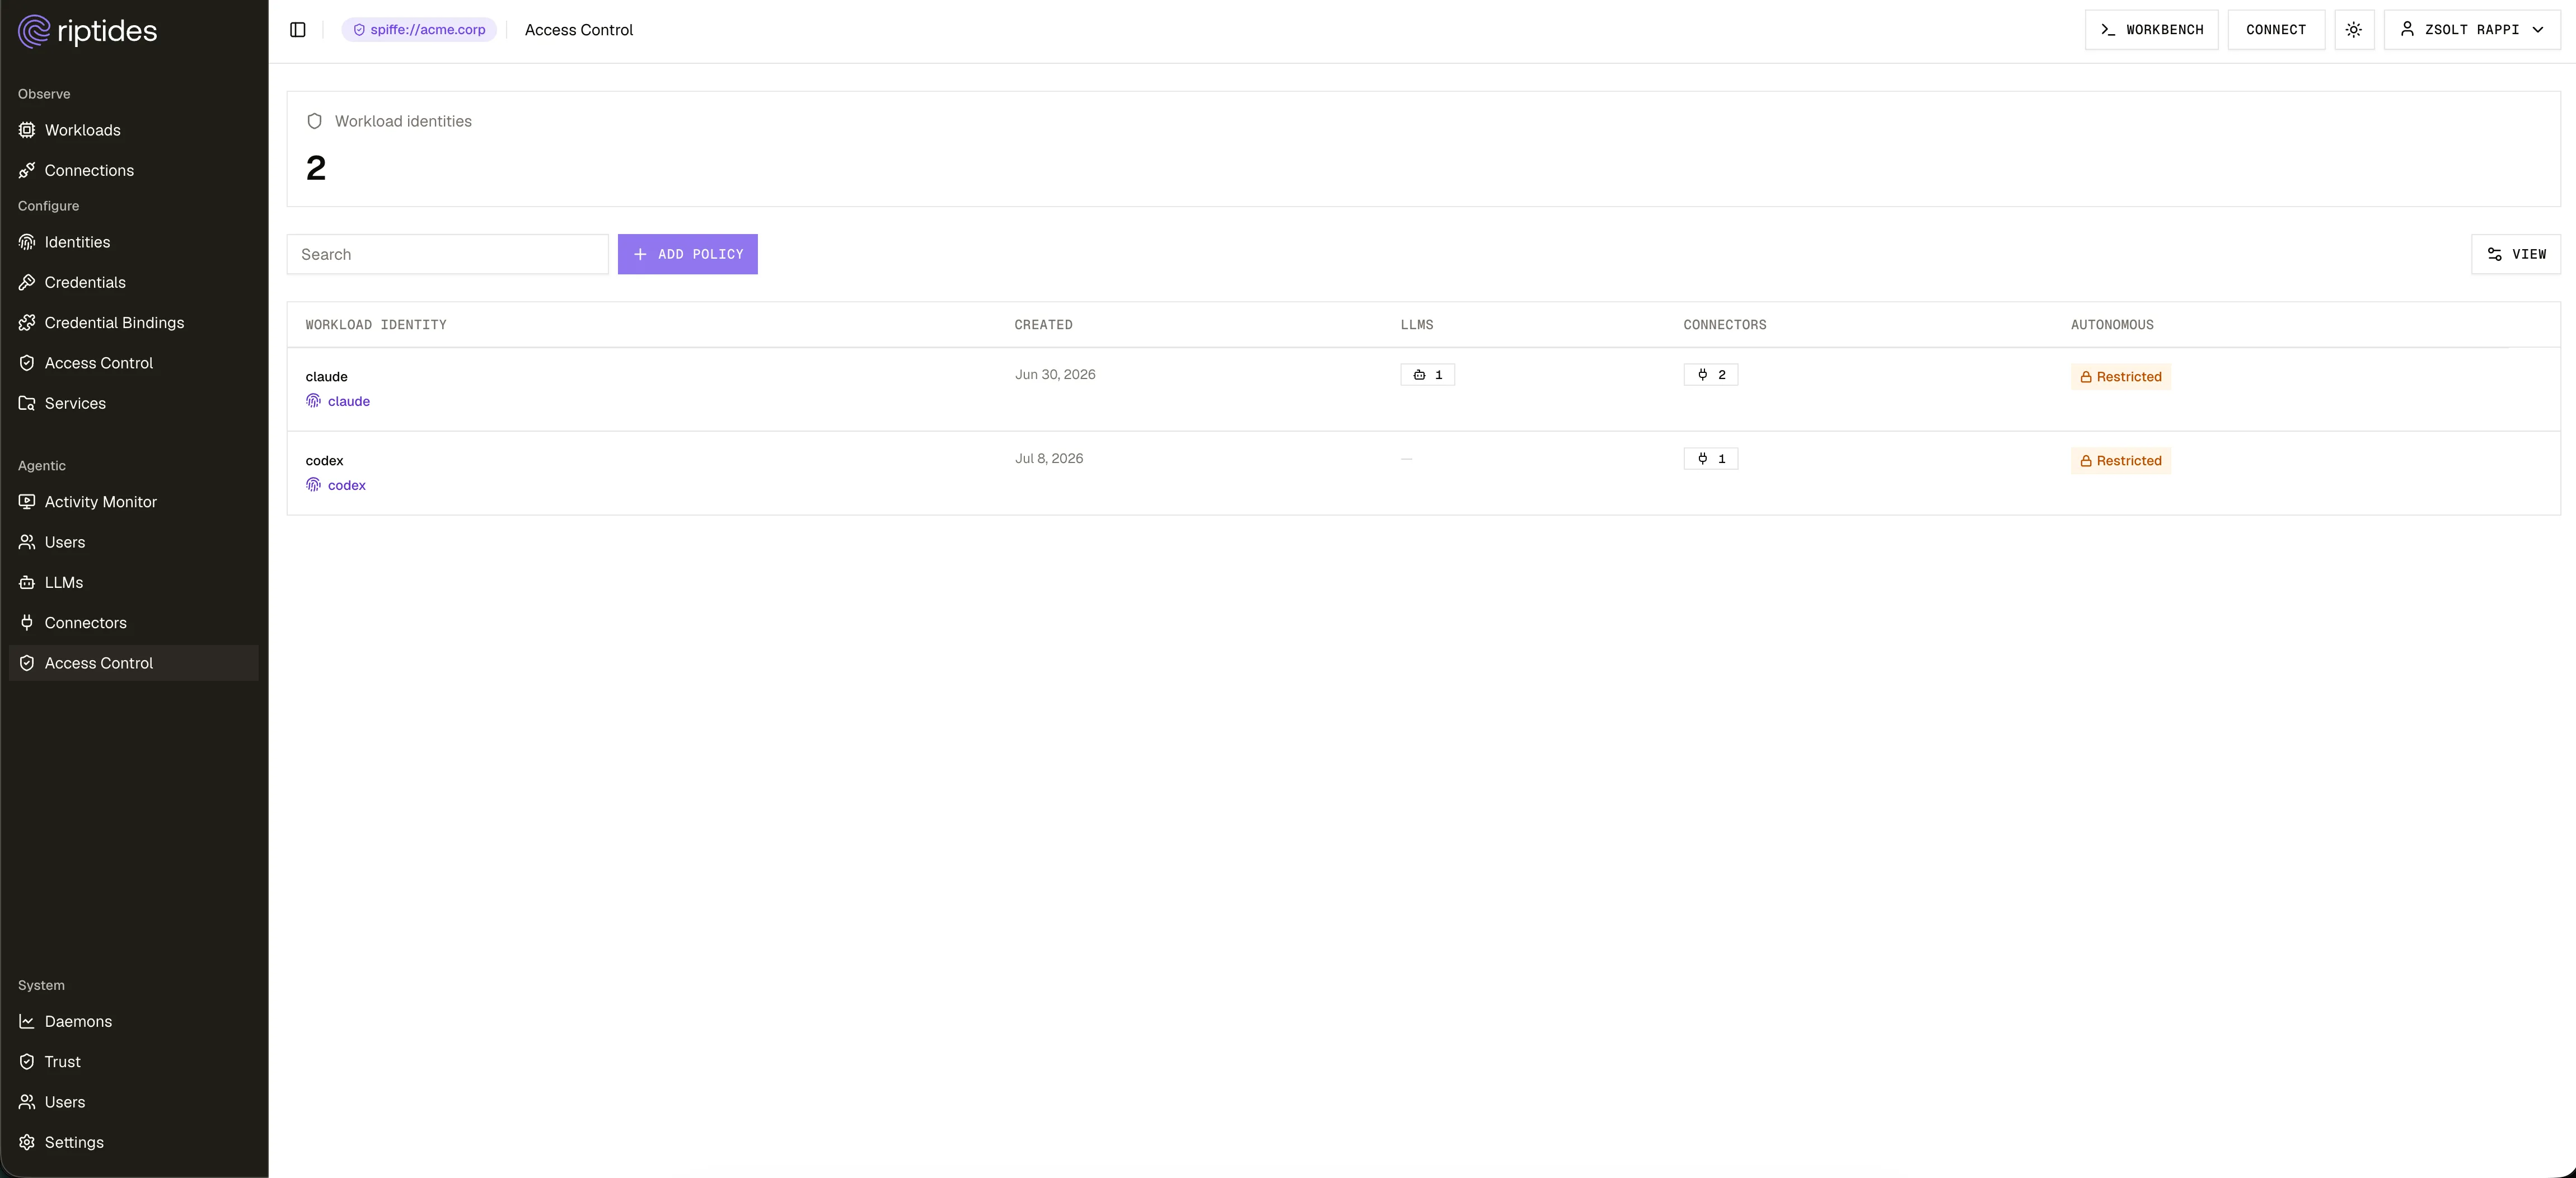
Agents are [workload identities](../../concepts/workload-identity); an agent must exist as a workload identity before you can write policy for it.
## Create a policy for an agent
[Section titled “Create a policy for an agent”](#create-a-policy-for-an-agent)
1. Choose **Add policy**.
2. Select the **workload identity** (the agent) you want to govern.
3. Confirm. This creates an empty policy (full access), which you then narrow in the editor.
Clicking a workload row opens the **policy editor** for that agent.
## Choose what the rules apply to
[Section titled “Choose what the rules apply to”](#choose-what-the-rules-apply-to)
The editor first asks *who* the rules apply to:
* **Autonomous Operation**: a fixed entry at the top. Select it to restrict the agent itself.
* **A specific user**: select **Restrict user** and pick a person from your [Users](../users). Their policy then governs the agent only when they are driving it.
The footer shows how many of your users already have a restricted policy. To remove a user’s restriction, delete their policy from this list.
## Restrict models and tools
[Section titled “Restrict models and tools”](#restrict-models-and-tools)
Once you have selected Autonomous Operation or a user, the editor shows two tabs, each with a count of how many entries are restricted:
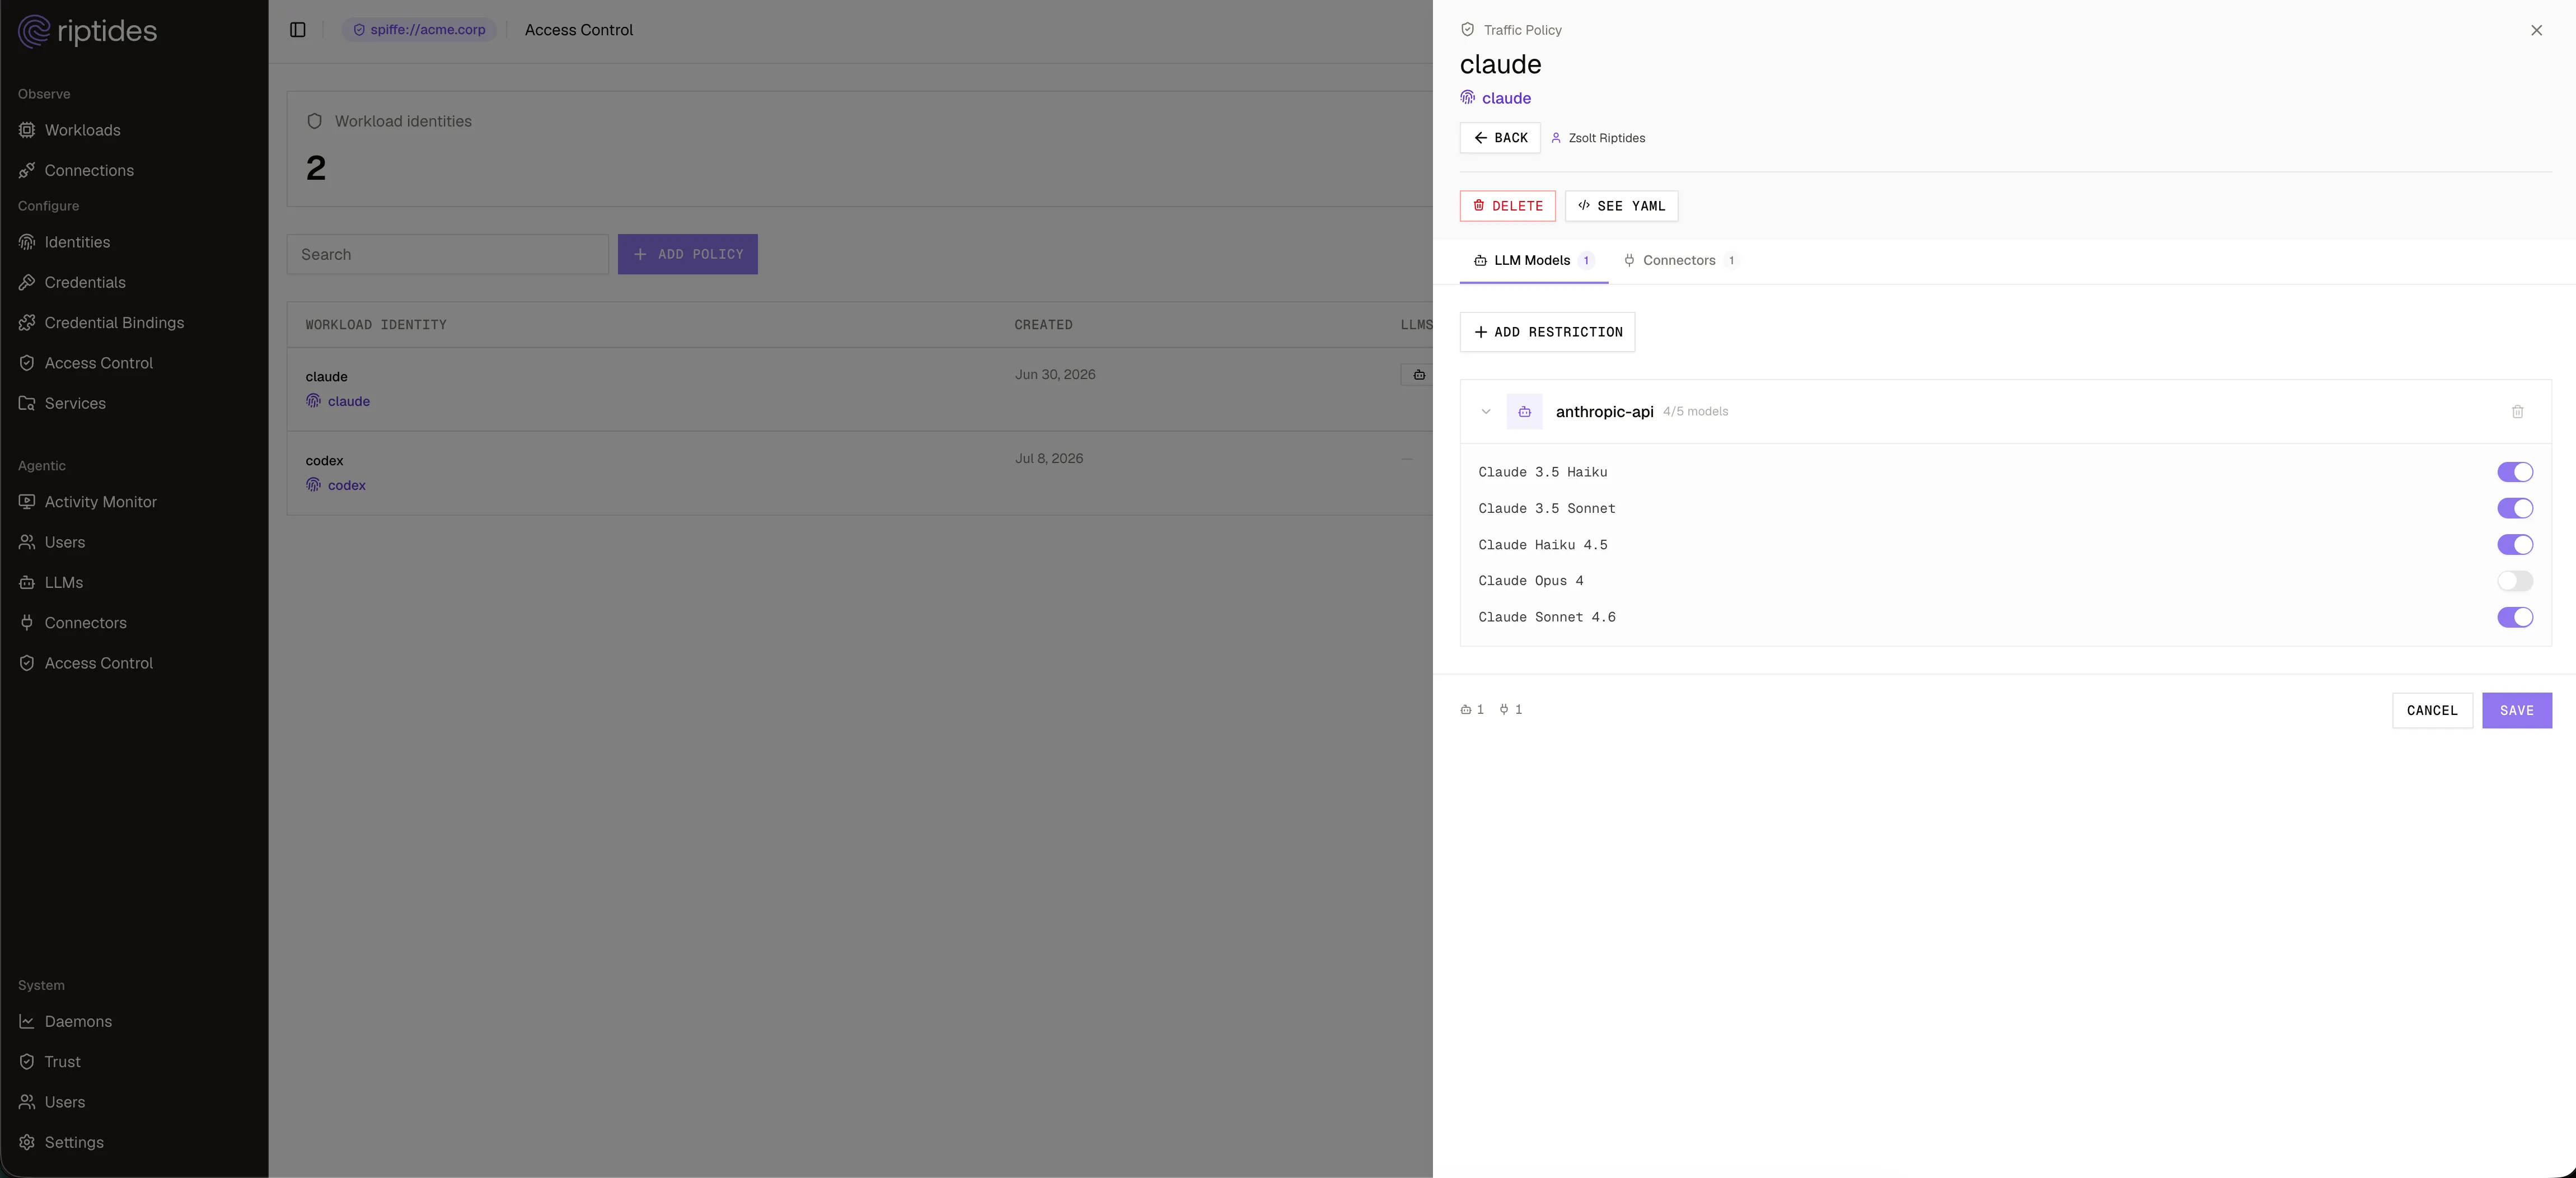
### LLM Models
[Section titled “LLM Models”](#llm-models)
Lists the LLM providers the policy restricts. Expand a provider to see its models, each with a toggle:
* Turn individual models **off** to keep only the ones you leave on for that provider.
* Leaving every model of a provider on allows the models known for that provider at save time (the list is stored explicitly).
* Removing a provider from the policy lifts the restriction, so that provider is allowed again in full. To deny models on a provider, keep the restriction and turn those models off (or leave none on).
Use **Add restriction** to add a provider to the policy (choosing from the providers on your [LLMs](../llms) screen).
### Connectors
[Section titled “Connectors”](#connectors)
Lists the MCP servers the policy restricts. Expand a connector to see its tools, each with a toggle, and use **Add restriction** to add a connector (from your [Connectors](../connectors) screen). The behavior mirrors LLM Models: once a connector has a restriction, only the tools you leave on are allowed for that connector (disallowed tools are blocked and hidden from the agent). Connectors you never restrict remain fully allowed.
When you are done, choose **Save**. The footer summarizes the counts and confirms the save.
## Restrict autonomous operation
[Section titled “Restrict autonomous operation”](#restrict-autonomous-operation)
To limit what an agent can do when it runs on its own, edit its **Autonomous Operation** policy and **Add restriction** only for the providers and connectors you want to narrow when no one is driving it, then leave on only the models and tools you allow unattended. Once those restrictions are in place, the **Autonomous** column on the dashboard shows the agent as **Restricted**. Leaving the Autonomous Operation policy empty, or omitting a provider or connector from it, leaves that traffic fully allowed for autonomous runs. Remember: this policy applies only when there is no human driver; it does not cover users who lack their own policy.
## Restrict to specific users
[Section titled “Restrict to specific users”](#restrict-to-specific-users)
To govern a person when they drive the agent, add a **user** policy (via **Restrict user**) and set its restrictions. That policy takes effect only for that user. It does **not** inherit or fall back to Autonomous Operation: other users without their own policy keep full access, and autonomous runs use only the Autonomous Operation policy. A user is matched by the identity assigned on the [Users](../users) screen.
## What a block looks like
[Section titled “What a block looks like”](#what-a-block-looks-like)
When an agent tries to use a model or tool that a restriction for that service does not permit, Riptides blocks it before the request leaves the host, and the block is recorded. In the [Activity Monitor](../activity-monitor) the blocked model or tool is flagged on its session, and the **Blocked events** count goes up. Open Access Control for that workload (and the Autonomous Operation or user entry that matches who was driving) to adjust the restriction if the block was not intended.
## Manage policies as code
[Section titled “Manage policies as code”](#manage-policies-as-code)
Policies are standard Riptides resources (`TrafficPolicy`), so you can also manage them with the CLI instead of the console. This is useful for GitOps or bulk changes. A policy names the agent (`workloadID`), an optional user (`actorID`), and its LLM and connector restrictions:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: TrafficPolicy
metadata:
name: claude-autonomous
namespace: riptides-system
spec:
workloadID: claude
# actorID omitted: this is the Autonomous Operation policy.
# A user-scoped policy sets actorID to that user's identity.
llmRules:
- llmRef:
name: anthropic-api
models:
- claude-haiku-4-5-20251001
connectorRules:
- serverRef:
name: mcp-linear
tools:
- search_issues
- list_teams
```
Apply it with:
```bash
riptides-cli ctl apply -f claude-autonomous.yaml
```
An empty `spec` (no rules) means full access. Each listed rule restricts only that provider or connector to the models or tools named in it; any service without a rule stays fully allowed. There is one policy per agent-and-user pair (omit `actorID` for Autonomous Operation).
## Next steps
[Section titled “Next steps”](#next-steps)
* [Monitor AI activity](../activity-monitor): confirm your policy by watching sessions and blocked events.
* [LLMs](../llms) and [Connectors](../connectors): keep the models and tools your policies reference up to date.
Current limitations
Access Control is written and tested for **Claude Code** and **Codex**. It can also work with other LLM-based applications, but policy recognition and enforcement may be incomplete for them, for example models or tools that are not identified the same way, or calls that are not filtered as they are for those agents. The same coverage limits apply to the [Activity Monitor](../activity-monitor).
# Monitoring AI Activity
The Activity Monitor shows what your AI agents are doing. Every agent run is captured as a **session**: the models it used, the tools it called, the services behind those tools, the person who drove it, and anything a policy blocked. You can browse sessions at a glance, then open one to see it as a graph or as a full conversation.
Open it from **Agentic → Activity Monitor** in the sidebar.
The point is **attribution**. Agents act semi-autonomously and reach real systems through tools, so when something happens you need to trace it back: which agent, driven by which person, reached which resource through which tool, and in what context. The Activity Monitor gives you that lineage. It is not about watching employees use an LLM, it is about holding autonomous agents accountable for what they do.
Note
AI activity is recorded and retained within your Riptides environment, which is where the Activity Monitor reads it from.
## The sessions dashboard
[Section titled “The sessions dashboard”](#the-sessions-dashboard)
The dashboard lists every AI session in the selected time window. Use the time-range control (top right) to switch between the last **1 hour**, **6 hours**, **24 hours** (the default), or **7 days**, and the refresh button to reload. Queries are capped at the last seven days.
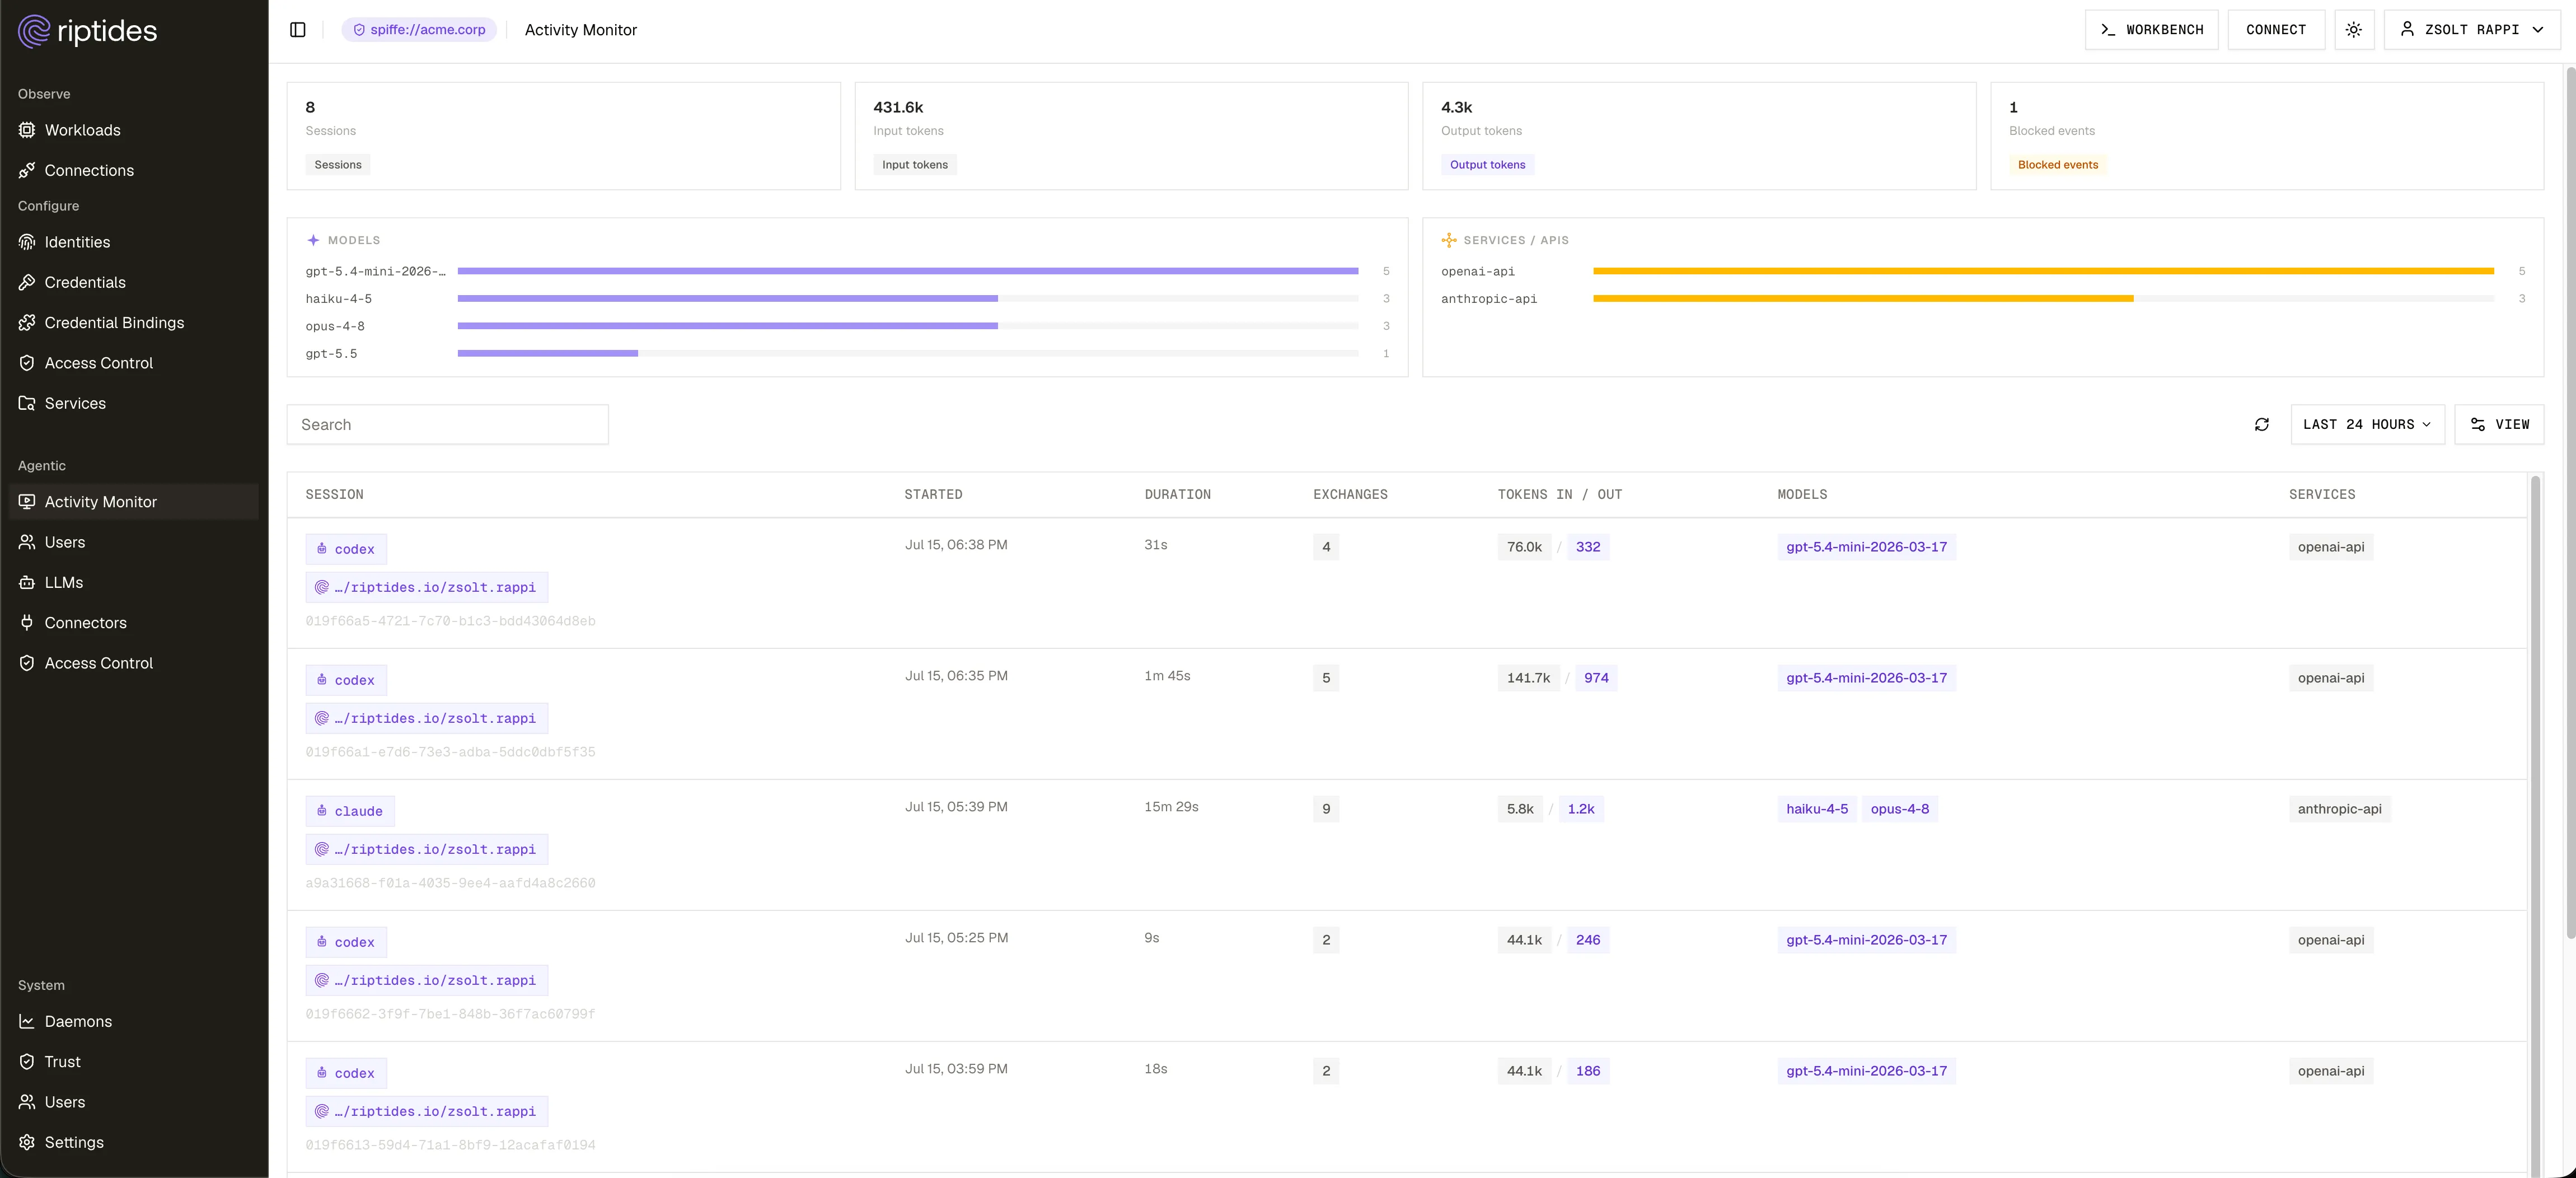
At the top, four cards summarize the window:
* **Sessions**: how many agent runs occurred.
* **Input tokens** and **Output tokens**: total token usage across all sessions.
* **Blocked events**: how many models or tools were blocked by policy.
Below the cards, two usage panels rank the most-used **Models** and **Services / APIs** in the window.
The table lists the sessions themselves. Each row shows:
* **Session**: the agent’s workload identity (for example `claude` or `codex`), the person who drove it, and the session id. Sessions that contained blocked activity are flagged.
* **Started** and **Duration**: when the run began and how long it lasted.
* **Exchanges**: how many request/response turns the agent had with an LLM.
* **Tokens in / out**: token usage for the session.
* **Models**: the models the agent used.
* **Services**: the MCP services it reached.
Search by the person driving the session, and click any row to open it.
## Opening a session
[Section titled “Opening a session”](#opening-a-session)
A session opens in a side panel with a summary strip (exchanges, input and output tokens, duration, and start time), plus a thinking indicator when the agent used reasoning and a blocked indicator when policy stepped in.
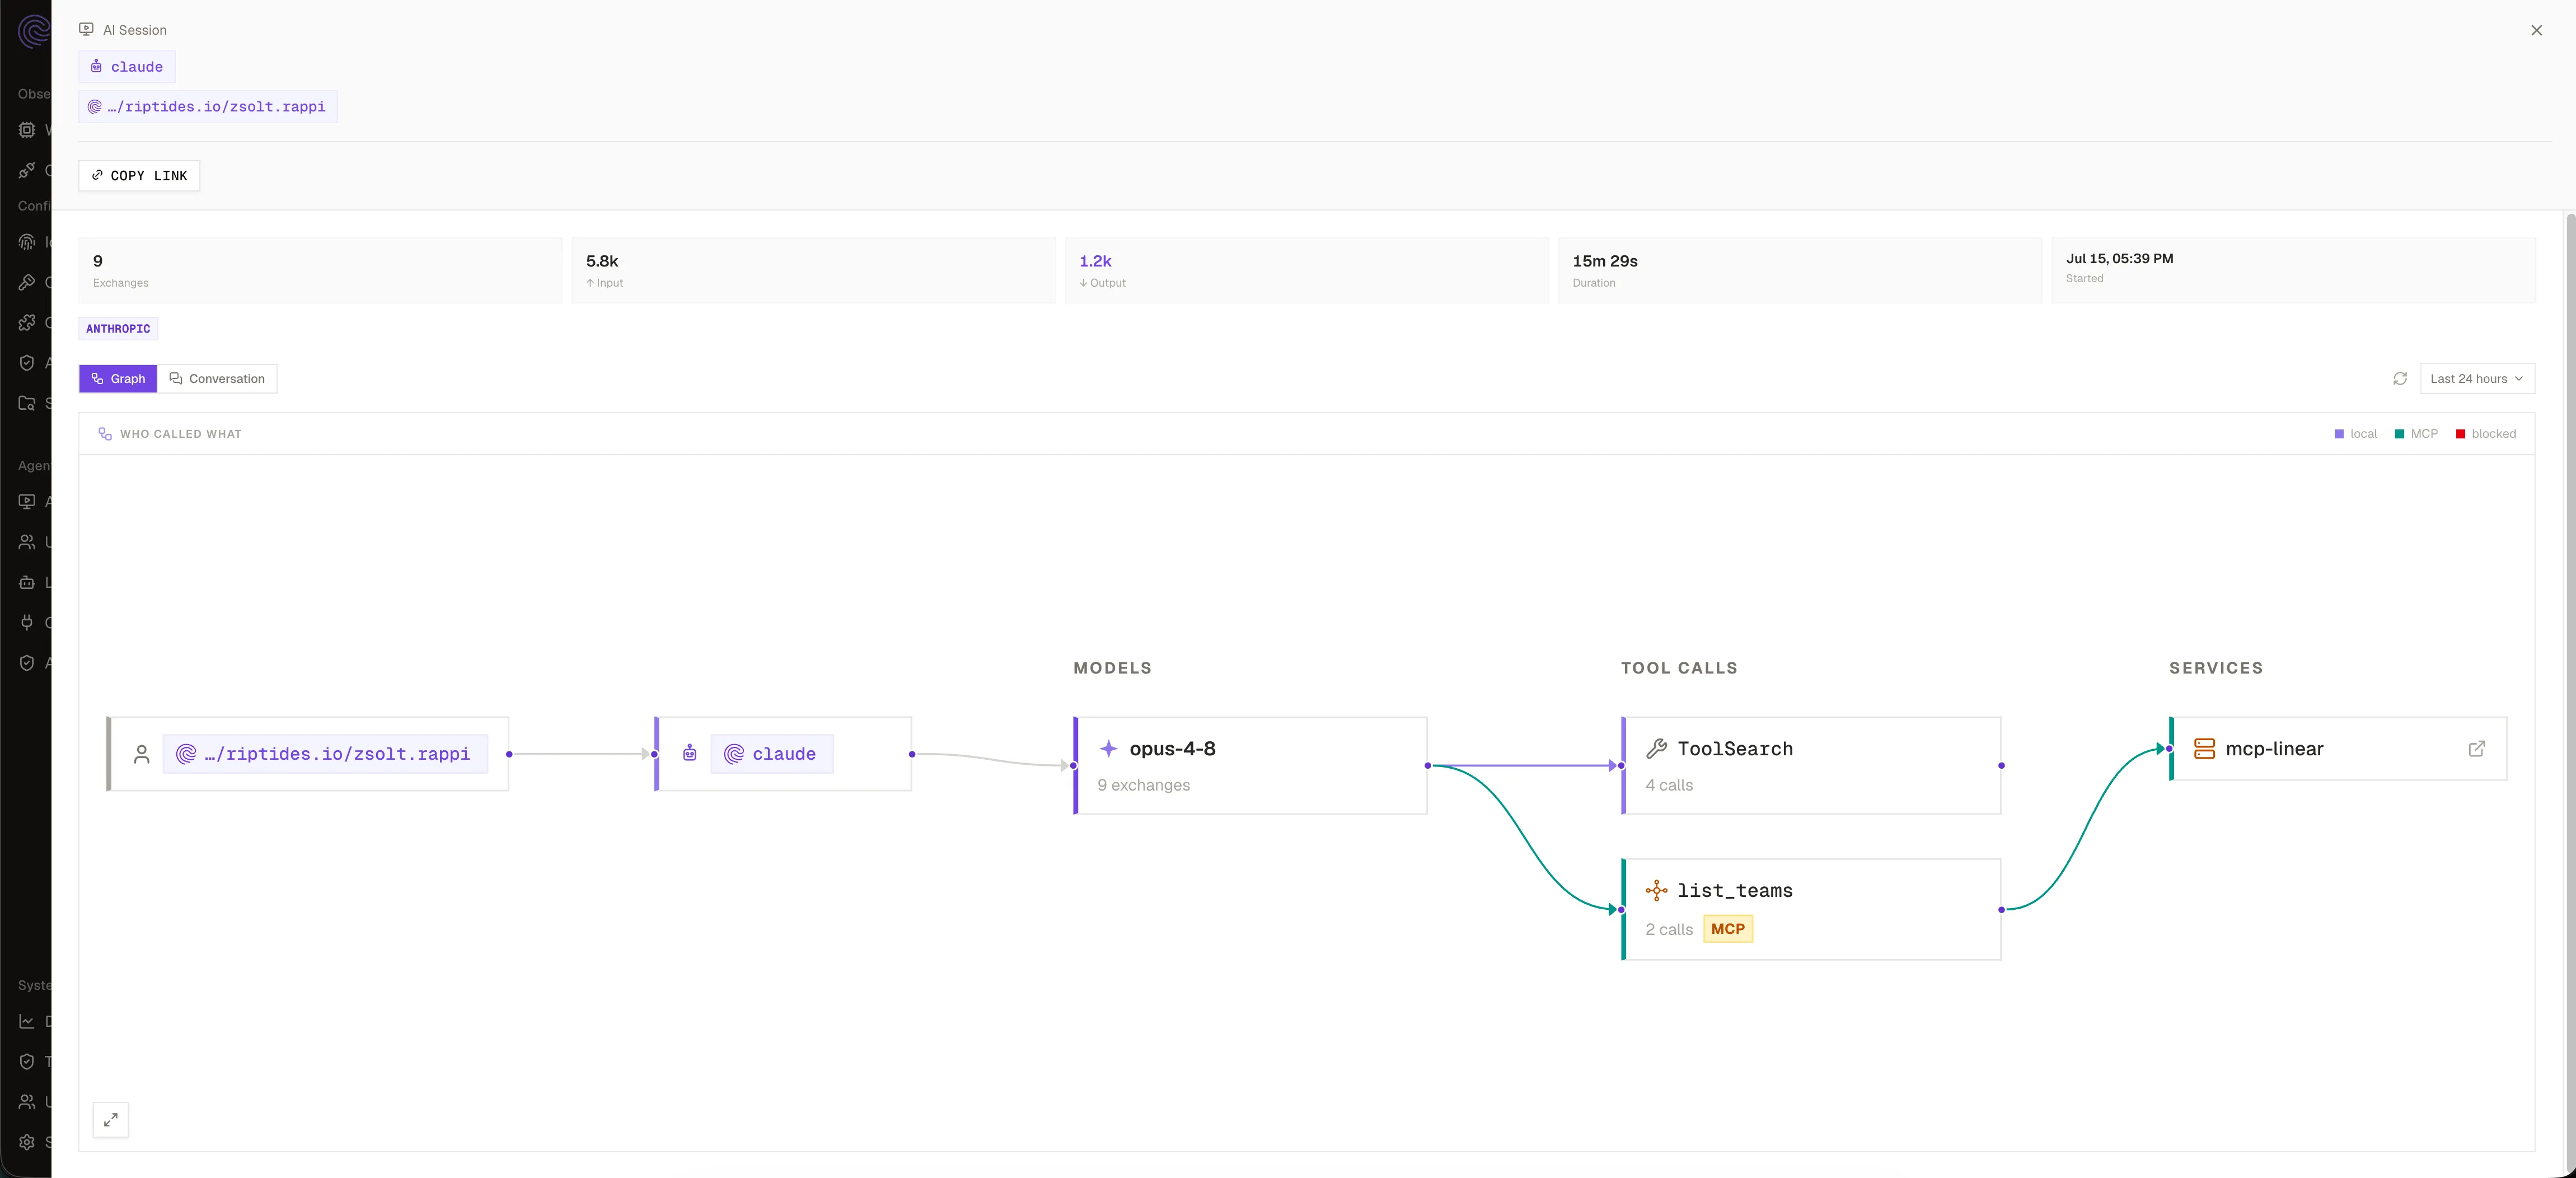
You can view the session two ways, using the toggle at the top of the panel:
* **Graph** (the default): a visual map of what the agent talked to.
* **Conversation**: the full turn-by-turn transcript.
## The session graph
[Section titled “The session graph”](#the-session-graph)
The graph reads left to right, in five columns:
* **Who**: the person who drove the agent.
* **Workload**: the agent identity that made the calls (for example `claude`).
* **Models**: each model the agent used. A spawned sub-agent gets its own node, badged with the sub-agent it belongs to.
* **Tool calls**: each distinct tool the agent invoked. MCP tools are badged **MCP**; built-in tools show as local tools.
* **Services**: the registered service behind an MCP tool call (the same entity you see in Service Inventory). Only MCP tool calls have a service.
### Focusing on a path
[Section titled “Focusing on a path”](#focusing-on-a-path)
Click any node to focus it. The graph highlights that node’s full lineage, everything upstream and downstream of it, and dims the rest, so you can isolate, say, one model and just the tools it called.
Use **Reset zoom** to fit the whole graph again.
### Node details
[Section titled “Node details”](#node-details)
Clicking a **model** or a **tool** node opens a detail drawer on the right:
* **Tool drawer**: the tool name, whether it is an MCP or local tool (and which server), the total number of calls, and how many were blocked. Below that is every call, newest first: when it happened, which model made it, and, for each call, its **input** (arguments) and **output** (result). Blocked calls are marked as blocked.
* **Model drawer**: the model name, the sub-agent it belongs to (if any), the number of exchanges, and how many were blocked, followed by one row per exchange.
## Trace a block to its policy
[Section titled “Trace a block to its policy”](#trace-a-block-to-its-policy)
When a model or tool is blocked, the detail drawer marks that call as blocked. Note the session’s workload identity and who was driving it, then open [Access Control](../access-control) for that agent and select the matching Autonomous Operation or user policy. From there you can adjust the allowlist if the block was not what you intended.
## The conversation view
[Section titled “The conversation view”](#the-conversation-view)
Switch to **Conversation** to read the session as a transcript. Prompts appear as chat bubbles, the person’s messages on one side and the model’s responses on the other, with reasoning (“thinking”) shown separately and tool calls as expandable rows that reveal their arguments and results. Blocked tool calls are marked.
By default the transcript focuses on the interesting parts and collapses routine turns; toggles let you show **all exchanges**, include **system** prompts, and fold background sub-agent activity into groups. Use the search box to find a specific message.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Control agent access](../access-control): turn what you saw into a policy that allows only the models and tools you intend.
* [Manage LLMs](../llms) and [Connectors](../connectors): review the providers and MCP servers agents can reach.
Current limitations
The Activity Monitor is written and tested for **Claude Code** and **Codex**. It can also work with other LLM-based applications, but you may see gaps: incomplete sessions, missing exchanges, or tool and model details that do not reconstruct cleanly. The same coverage limits apply to [Access Control](../access-control).
# Connectors
The **Connectors** screen lists the MCP servers registered in your system: the tool integrations your agents can use. MCP (Model Context Protocol) is how an agent calls out to real systems: creating an issue in Linear, opening a pull request, sending a Slack message. Each connector exposes a set of **tools**, and those tools are what you allow or restrict in an [access policy](../access-control).
Open it from **Agentic → Connectors** in the sidebar.
## Built-in connectors
[Section titled “Built-in connectors”](#built-in-connectors)
Riptides ships with definitions for many common MCP servers, so their tools are ready to reference in policy without any setup. The built-in set includes:
* **Linear** (`mcp.linear.app`): `create_issue`, `update_issue`, `search_issues`, `list_teams`, and more
* **GitHub Copilot**, **Slack**, **Notion**, **Atlassian**, **Stripe**, **HubSpot**, **Sentry**, **PagerDuty**, **Figma**, **Supabase**, **Cloudflare**, **Zapier**, and others
Each connector is matched by its MCP endpoint and carries the list of tools it exposes.
## What you see
[Section titled “What you see”](#what-you-see)
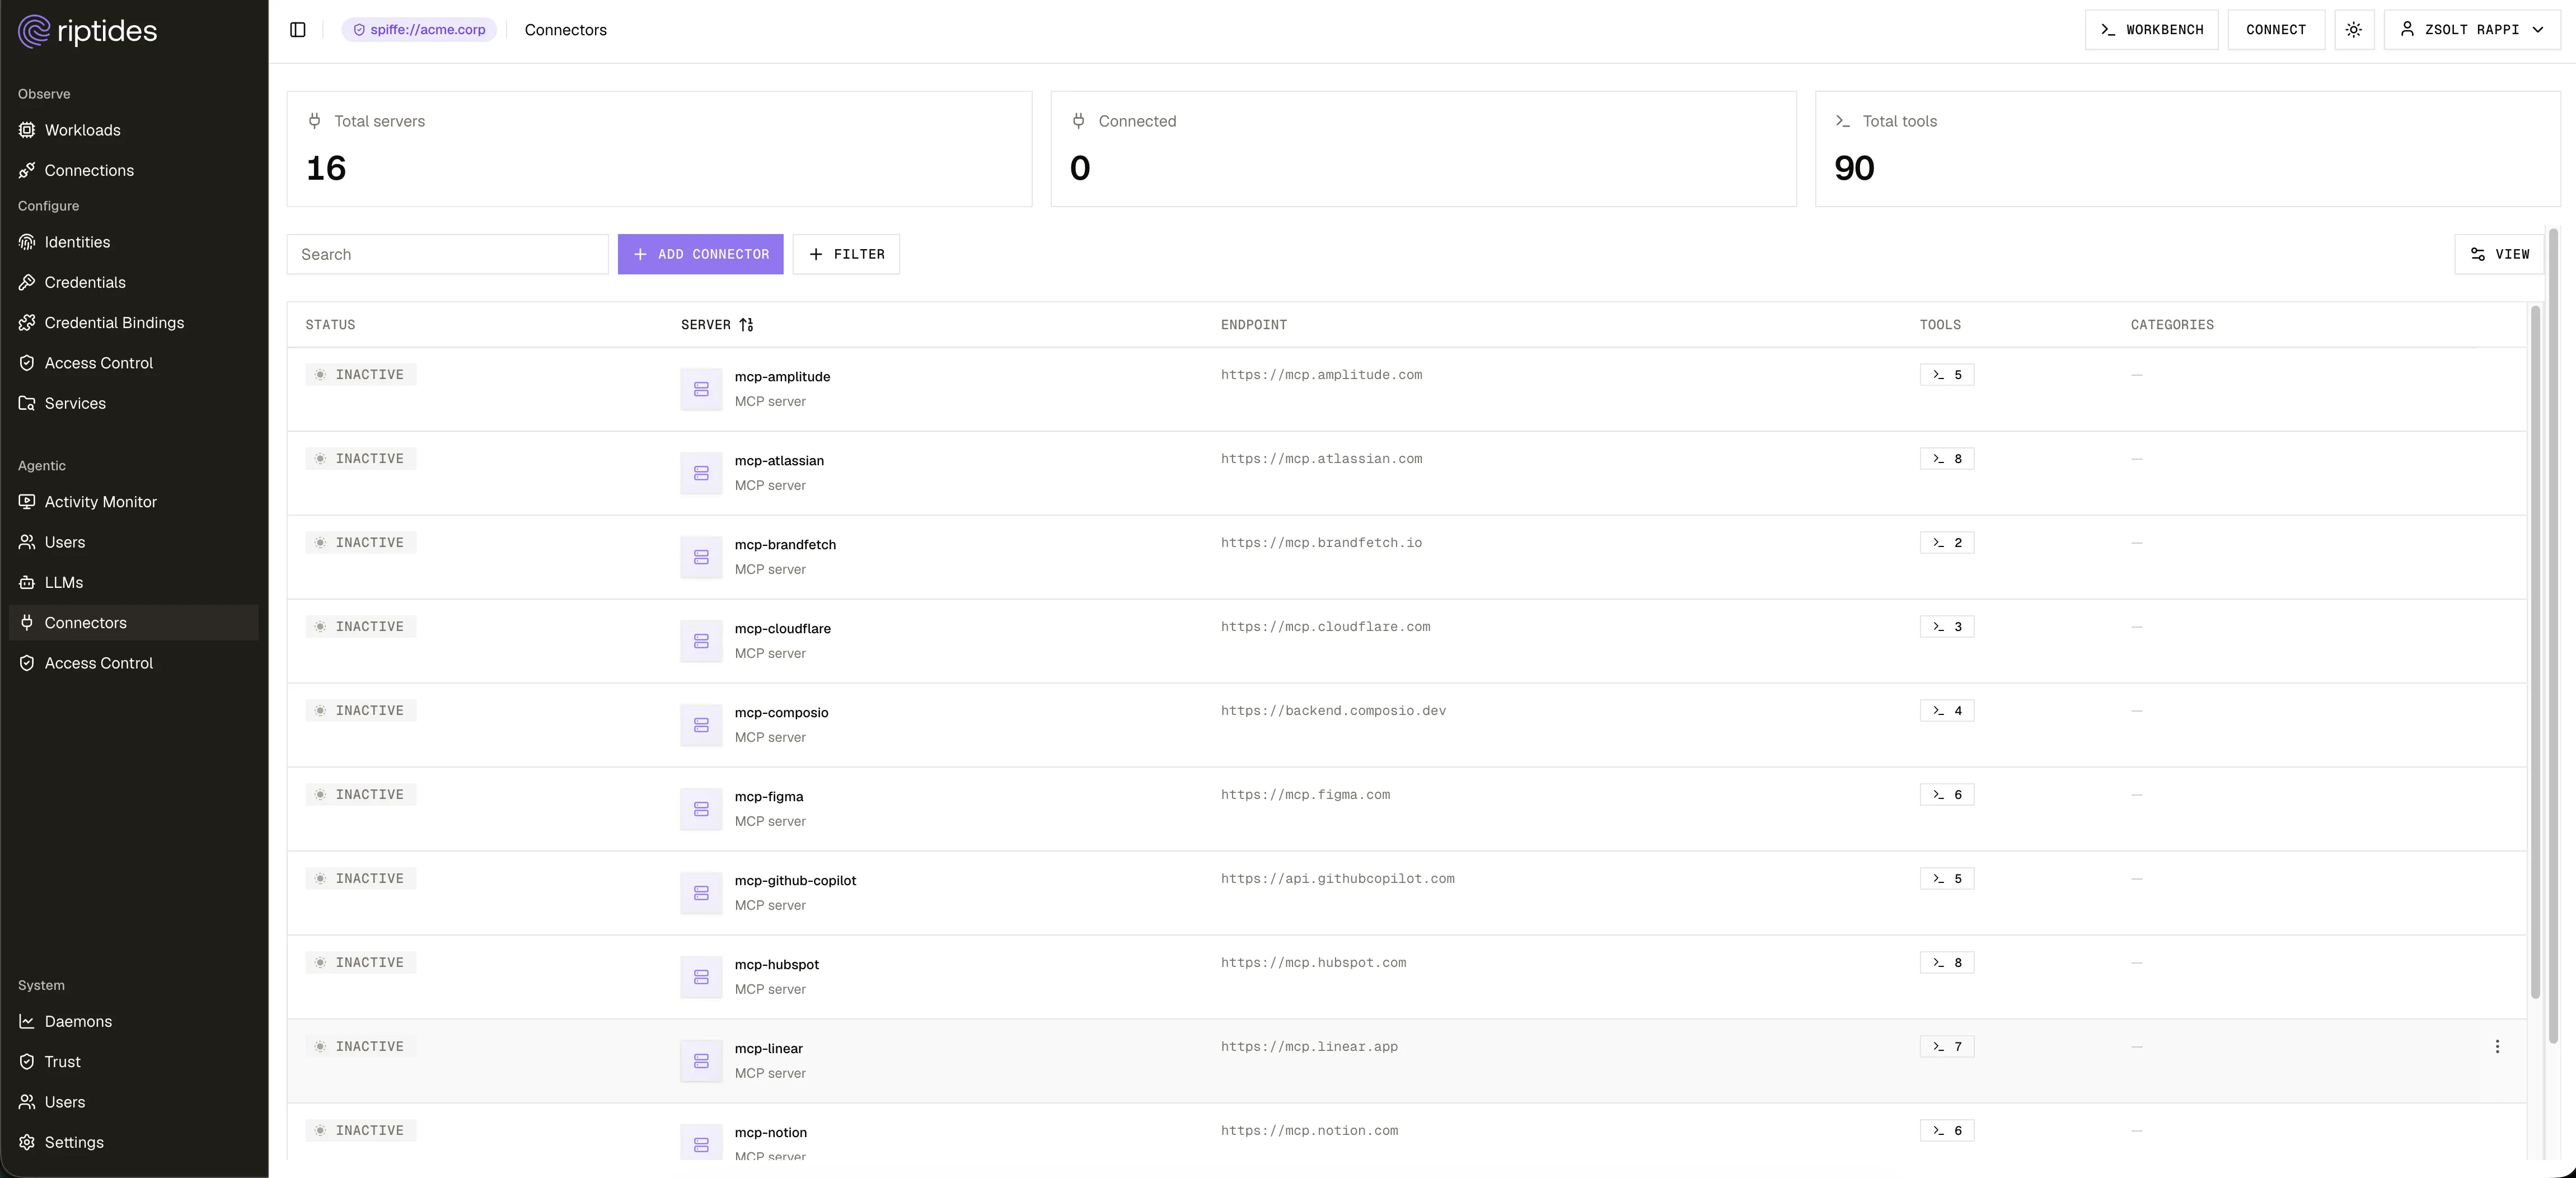
Three cards summarize the inventory: **Total servers**, **Connected** (active), and **Total tools**.
The table lists each connector with:
* **Status**: whether the server is active.
* **Server**: its display name and description.
* **Endpoint**: the MCP host it matches.
* **Tools**: how many tools it exposes.
* **Categories**: tags used to group connectors.
Search by name, and filter by status or category.
## Add a connector
[Section titled “Add a connector”](#add-a-connector)
Use **Add connector** to register an MCP server that is not built in. You give it a name, its endpoint, the tools it exposes, and optional categories. The transport (such as SSE or streamable HTTP) is shown for each connector based on its endpoint.
## Edit or remove a connector
[Section titled “Edit or remove a connector”](#edit-or-remove-a-connector)
Each row’s **⋯** menu lets you **Edit** a connector or **Remove** it. Removing a connector also removes it as a target from any policy that referenced it.
Click a connector to open its detail panel, which shows its transport, endpoint, categories, and the full list of tools it exposes, along with edit and remove actions and a YAML view.
## How connectors are used in policy
[Section titled “How connectors are used in policy”](#how-connectors-are-used-in-policy)
The tools listed here are the choices you get when restricting an agent in [Access Control](../access-control). Adding a connector rule for an MCP server restricts that server to the tools you list; tools of that server you do not list are blocked and hidden from the agent. Connectors without a rule stay fully allowed. Blocked tool calls appear in the [Activity Monitor](../activity-monitor).
## Next steps
[Section titled “Next steps”](#next-steps)
* [LLMs](../llms): the model providers agents can reach.
* [Control agent access](../access-control): restrict which tools an agent may call.
# LLMs
The **LLMs** screen lists the model providers your agents can reach: the AI services Riptides recognizes, and the models each one offers. These are the providers you allow or restrict in an [access policy](../access-control), and the ones the [Activity Monitor](../activity-monitor) attributes model usage to.
Open it from **Agentic → LLMs** in the sidebar.
## Built-in providers
[Section titled “Built-in providers”](#built-in-providers)
Riptides ships with the major LLM providers already defined, so you can start writing policy without registering anything. The built-in set includes:
* **Anthropic** (`api.anthropic.com`): Claude Opus 4.8, Claude Sonnet 5, and Claude Haiku 4.5 models
* **OpenAI** (`api.openai.com`): GPT-5, o4-mini, and GPT-4.1 models
* **Mistral**, **DeepSeek**, **Cohere**, **Groq**, **Fireworks**, **Together**, **Perplexity**, **xAI (Grok)**, **OpenRouter**, and more
Each provider is matched by its API endpoint (for example `api.anthropic.com:443`) and carries the list of models it offers.
## What you see
[Section titled “What you see”](#what-you-see)
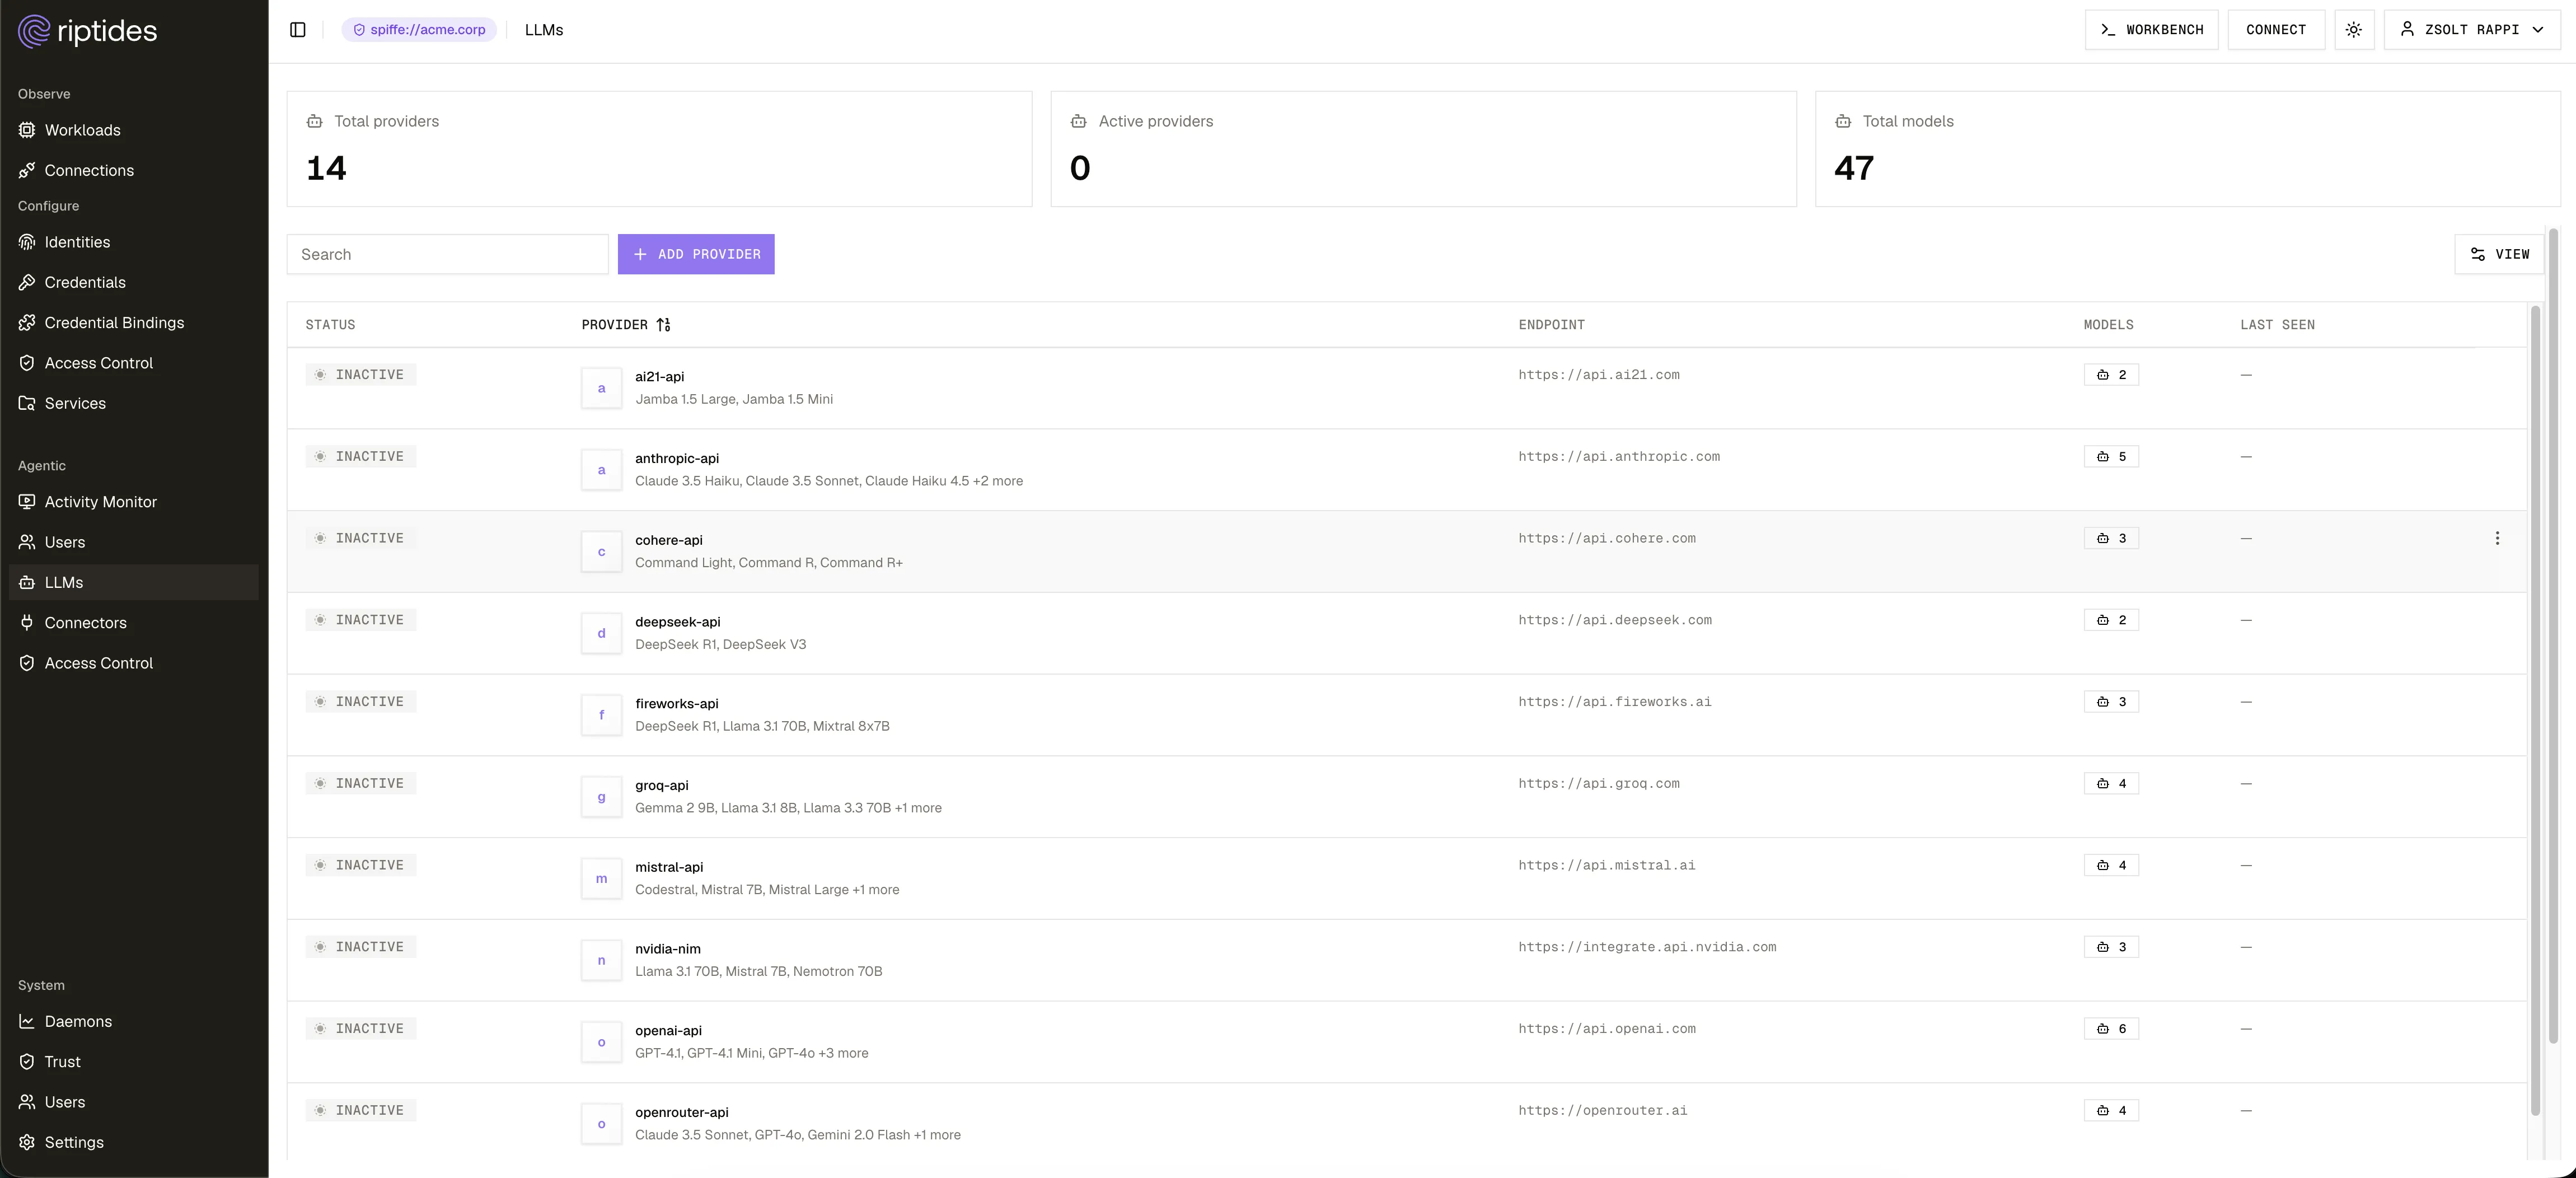
Three cards summarize the inventory: **Total providers**, **Active providers**, and **Total models**.
The table lists each provider with:
* **Status**: whether the provider is active.
* **Provider**: its name and a summary of its models.
* **Endpoint**: the API host it matches.
* **Models**: how many models it offers.
* **Last seen**: when traffic to it was last observed.
Search by provider name.
## Add a provider
[Section titled “Add a provider”](#add-a-provider)
Use **Add provider** to register an LLM service that is not built in, for example a self-hosted or regional endpoint (such as an Azure-hosted OpenAI deployment). You give it a name, the endpoint it should match, and the models it offers.
## Edit or remove a provider
[Section titled “Edit or remove a provider”](#edit-or-remove-a-provider)
Each row’s **⋯** menu lets you **Edit** a provider (its endpoint and model list) or **Remove** it. Removing a provider also removes it as a target from any policy that referenced it.
Click a provider to open its detail panel, which shows its status, endpoint, and the full list of registered models, along with edit and remove actions and a YAML view.
## How LLMs are used in policy
[Section titled “How LLMs are used in policy”](#how-llms-are-used-in-policy)
The models listed here are exactly the choices you get when restricting an agent in [Access Control](../access-control). Adding an LLM rule for a provider restricts that provider to the models you list; models of that provider you do not list are blocked, and the block shows up in the [Activity Monitor](../activity-monitor). Providers without a rule stay fully allowed. Keeping this inventory accurate, especially the model list on each provider, keeps the policy editor’s choices correct.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Connectors](../connectors): the MCP servers and tools agents can use.
* [Control agent access](../access-control): restrict which models an agent may call.
# Agentic AI Overview
Riptides secures and observes the AI agents running across your fleet. It shows you every model an agent talks to, every tool it invokes, and the person driving it, and it lets you set guardrails on which models and tools each agent is allowed to use, all with no changes to the agent or its configuration.
AI agents are a new kind of workload: they act semi-autonomously, reach out to external LLM providers, and increasingly call real systems through tools (creating issues, querying databases, sending messages). That makes two questions urgent. What are my agents actually doing, and how do I keep them inside the lines? The Agentic AI features answer both.
## What you can do
[Section titled “What you can do”](#what-you-can-do)
The **Agentic** section of the console groups everything AI-related:
* **[Activity Monitor](../activity-monitor)**: see every AI session as a graph: who ran the agent, which models it used, which tools it called, and anything that policy blocked.
* **[LLMs](../llms)**: the model providers your agents can reach (Anthropic, OpenAI, Mistral, and others), and the models each one offers.
* **[Connectors](../connectors)**: the MCP servers registered in your system (Linear, GitHub, Slack, and more) and the tools they expose.
* **[Users](../users)**: the people who drive agents, so a policy can be scoped to a specific person.
* **[Access Control](../access-control)**: the policies that decide which models and tools each agent may use, and who is allowed to drive it.
## Key concepts
[Section titled “Key concepts”](#key-concepts)
* **Agent**: in agentic AI terms, an application that uses a large language model to pursue goals and take actions, typically with some autonomy, often by calling tools or external systems, not only by answering a single prompt. In Riptides, each agent is represented as a [workload identity](../../concepts/workload-identity) whose AI traffic is observed and governed. (See **Current limitations** at the end of this page for what is written and tested today.)
* **Session**: one agent run for a given workload and person. A session groups the back-and-forth **exchanges** the agent has with an LLM, including the tool calls it makes along the way.
* **Exchange**: a single request/response turn with an LLM: the input, the model’s response, any tool calls it emitted, and token usage.
* **LLM**: a model provider Riptides recognizes as an AI service (for example `anthropic-api`). Each provider exposes a set of **models**.
* **Connector**: a registered MCP (Model Context Protocol) server, such as a Linear or GitHub integration. Each connector exposes a set of **tools** the agent can call.
* **Tool call**: an agent’s invocation of a tool. This can be a **local** (built-in) tool the agent runs itself, such as reading a file or running a command, or a tool exposed by an MCP **connector** (for example `create_issue`) that is routed through the MCP server behind it. Both kinds show up in the Activity Monitor; only connector tools have a service behind them.
* **User (actor)**: a person from the Users directory (from an identity provider or added manually). A policy can be scoped to a specific user so its rules apply only when that person is driving the agent.
* **Access policy**: restrictions on models and tools for one agent, optionally scoped to one user (or to autonomous runs with no user). Default is allow; only providers and connectors you add a rule for are restricted.
## How it works
[Section titled “How it works”](#how-it-works)
Riptides runs on each host and gives every workload a cryptographic identity. When an AI agent calls an LLM or an MCP server, Riptides recognizes the call as AI traffic, applies the matching access policy when one governs that agent and driver (blocking models or tools that policy does not allow for that service), and records the interaction so it appears in the Activity Monitor. This happens transparently: the agent makes ordinary API calls, and Riptides observes and enforces in the middle, with no SDK, proxy configuration, or code changes in the agent.
Because enforcement and observation are built on the same identity and connection security as the rest of Riptides, an agent is governed the moment it has an identity, and there is nothing to install into the agent itself. Policies are scoped: Autonomous Operation covers unattended runs, and each user policy covers only that person. A human without a user policy is not limited by Autonomous Operation. For each policy, traffic is allowed by default and only the providers and connectors you restrict are narrowed. For the underlying platform, see [Platform Architecture](../../concepts/architecture) and [Connection Security](../../concepts/connections).
## Next steps
[Section titled “Next steps”](#next-steps)
Prerequisite
An agent only appears here once it exists as a workload identity with traffic inspection turned on. Create one for the agent’s process (with **TLS intercept** on) on the [Identities](../../console/identities) screen.
* [Monitor AI activity](../activity-monitor): read a session and trace what an agent did.
* [Control agent access](../access-control): create a policy to restrict models, tools, and users.
* [Manage LLMs](../llms) and [Connectors](../connectors): review the providers and MCP servers agents can reach.
Current limitations
The Activity Monitor and Access Control are written and tested for **Claude Code** and **Codex**. They can also work with other LLM-based applications, but you may see gaps, for example incomplete sessions in the Activity Monitor, or policies that do not cover every model or tool call the way they do for those agents.
# Users
The **Users** screen lists the people who drive agents in Riptides. These are the humans you scope a policy to when you want a rule to apply only to a specific person. In an [access policy](../access-control), a user is the **actor**: the human on whose behalf an agent is acting.
Open it from **Agentic → Users** in the sidebar.
## Where users come from
[Section titled “Where users come from”](#where-users-come-from)
Users can come from an identity provider you connect to Riptides (for example GitHub, Google, Microsoft Entra, or a generic OIDC provider). When someone signs in, they appear here with the details their provider supplies. They can also be added manually. To set up identity-provider sign-in, see [OIDC and Identity Provider Setup](../../guides/oidc-setup).
Each user carries a **SPIFFE ID**, a stable identity Riptides assigns them. That identity is the link that lets a policy target one specific person: when an agent runs on someone’s behalf, Riptides attributes the activity to their identity, and a user-scoped policy matches on it.
## What you see
[Section titled “What you see”](#what-you-see)
Four cards summarize the directory: **Total users**, **Active (30d)**, **With SPIFFE ID**, and **With groups**.
The table lists each user with:
* **User**: name and email.
* **Provider**: the identity provider they signed in through (used as a filter), when applicable.
* **SPIFFE ID**: the identity assigned to them, or a dash if none.
* **Last login**: when they last signed in.
Search by name or email, and filter by provider.
## How users are used in policy
[Section titled “How users are used in policy”](#how-users-are-used-in-policy)
A policy can either govern an agent **regardless of who is driving it** or apply **only when a specific user is driving it**. The second case is exactly where this screen matters: when you restrict a workload to specific users in [Access Control](../access-control), you pick those people from this list. The [Activity Monitor](../activity-monitor) also shows the user behind each session, so you can see who ran which agent.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Control agent access](../access-control): restrict an agent to specific users.
* [Monitor AI activity](../activity-monitor): see which user drove each session.
# AI Agent Governance
An AI agent is a workload like any other: a process with a [workload identity](../workload-identity), secured the same way as a service or a CI job. What’s different is what it does with that identity. A service calls a fixed set of destinations in a predictable order; an agent decides at runtime what to call based on an LLM’s output, so the same agent can take a different path through your infrastructure on every run. Identity and network policy alone answer “is this workload allowed to reach this destination,” but they don’t answer the questions that actually matter for an agent: which model did it use, which tool did it call, and who was driving it when it did.
Riptides extends the same kernel-level enforcement it uses for mTLS and credential injection to answer those questions, without adding an SDK, a proxy, or any change to the agent’s code or configuration.
## The Building Blocks
[Section titled “The Building Blocks”](#the-building-blocks)
* **Agent**: not a new resource type. An agent is a [WorkloadIdentity](../../reference/workloadidentity) like any other, with TLS interception turned on so the kernel can inspect its HTTP traffic to recognize LLM and MCP calls.
* **Actor**: the human on whose behalf the agent is acting. Riptides resolves this from the credentials the agent itself presents to the LLM provider, so every action carries two identities: the agent’s workload identity and the actor’s. This composite identity is what lets a policy apply only when a specific person is driving, and what lets an audit trail answer “who” as well as “what.”
* **Session** and **exchange**: a session is one agent run; an exchange is one request/response turn within it, including any tool calls the agent made along the way. Sessions and exchanges are how agent activity is organized for observability.
* **Tool call**: an agent invoking a tool, which is either **local** (a built-in action the agent runs itself, such as reading a file or running a command) or routed through an MCP **connector**. Both are observed the same way
* **LLMs** and **connectors**: the vocabulary a policy is written against. An LLM is a model provider (Anthropic, OpenAI, and others) and the models it offers; a connector is an MCP server (Linear, GitHub, Slack, and others) and the tools it exposes.
* **Access policy**: the rule set that governs one agent, applied either to its autonomous runs or to a specific actor driving it.
## How It Works
[Section titled “How It Works”](#how-it-works)
Because an agent’s traffic is ordinary HTTPS, Riptides recognizes it the same way it recognizes any traffic it intercepts: by inspecting the connection at the kernel, not by requiring the agent to route through a separate proxy or gateway. Known LLM and MCP endpoints are classified as AI traffic; the driving actor is resolved from the agent’s own provider credentials; and the applicable access policy, if any, is evaluated before the request leaves the host. A call that policy doesn’t allow is blocked at that point, not after it reaches the provider. Every exchange, including anything blocked, is recorded for the Activity Monitor.
## Default Allow, Restrict by Exception
[Section titled “Default Allow, Restrict by Exception”](#default-allow-restrict-by-exception)
An agent with no policy, or an empty one, has full access. Adding a rule for a specific provider or connector narrows only that one: the models or tools you leave on for it are permitted, everything else on that same provider or connector is blocked, and every other provider or connector the policy doesn’t mention stays fully allowed. This means adopting governance is incremental: you can restrict one high-risk connector today without having to enumerate everything else an agent is allowed to touch.
Policy also distinguishes *who* is driving the agent. An autonomous-operation policy governs unattended runs; a per-user policy governs one specific person driving the agent. There’s no fallback between them: a human with no policy of their own gets full access even if the agent’s autonomous policy is locked down. This lets you, for example, run an agent unattended under a strict allowlist while giving a trusted engineer broader access when they’re the one behind the wheel.
## Why Not a Gateway or Prompt Guardrails
[Section titled “Why Not a Gateway or Prompt Guardrails”](#why-not-a-gateway-or-prompt-guardrails)
### AI and MCP Gateways
[Section titled “AI and MCP Gateways”](#ai-and-mcp-gateways)
A gateway, whether it fronts LLM calls or MCP tool calls, only governs what’s actually routed through it. An agent that makes a direct connection, or reaches anything outside the gateway’s configured path, bypasses it entirely, so coverage depends on every agent being correctly wired to the gateway rather than on anything the platform itself guarantees. Local tool calls make this worse than a bypass risk: reading a file or running a command never goes over the network at all, so no gateway, however well every agent is configured, could ever see it. A gateway is also a piece of infrastructure you now have to scale and keep available: it sits in the request path of every governed call, so its capacity has to grow with your agent traffic instead of with your actual node count.
Riptides enforces where the agent already runs, at the kernel, so there’s nothing centralized to add capacity to, and local tool calls are covered the same way connector calls are. Because every connection is inspected there regardless of destination, you get a complete audit trail of every LLM call, MCP call, and local tool call an agent made, not just the ones that happened to be routed through a gateway.
### Prompt Guardrails
[Section titled “Prompt Guardrails”](#prompt-guardrails)
Prompt guardrails try to stop an agent from *being told* to do something unsafe, but they operate on the prompt, not the connection. A credential sitting in the agent’s memory, or a tool call to an unapproved endpoint, doesn’t have to go through a prompt to happen, so it’s outside what a guardrail can see or stop.
Because Riptides enforces at the node, every outbound connection the agent makes is covered, regardless of which framework, library, or tool call initiated it, and regardless of what the agent’s own reasoning decided to do.
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Agentic AI Overview](../../agentic/overview): the console features built on this model.
* [Monitor AI activity](../../agentic/activity-monitor) and [control agent access](../../agentic/access-control): the day-to-day workflows.
* [Guardrails for an AI Agent](../../examples/agentic-guardrails): a worked example end to end.
# Platform Architecture
Riptides is an identity-first workload security platform that enforces authentication, authorization, and credential management at the kernel level. The platform consists of three components: a centralized control plane, a per-node daemon, and a Linux kernel module. Together, they provide transparent mutual TLS, workload identity, and credential injection without application changes.
## Components
[Section titled “Components”](#components)
### Control Plane
[Section titled “Control Plane”](#control-plane)
The control plane is the central management layer. It defines and distributes identity policies, issues certificates, and acts as the trust anchor for the entire platform.
The control plane includes:
* **API server** — A Kubernetes-style API server that exposes Custom Resource Definitions (CRDs) for all Riptides resources: workload identities, services, credential sources, credential bindings, verifiers, and federation configuration. Operators interact with it using [`riptides-cli ctl`](../../deployment/cli).
* **Controllers** — Reconcile declared policy into concrete artifacts (certificates, access rules, credential bindings) that the enforcement layer consumes.
* **OIDC provider** — Handles user authentication for the control plane UI and API. External identity providers (GitHub, Google, etc.) authenticate human users via OIDC, and Riptides manages sessions and access control.
* **gRPC server** — Serves policy, certificate, and credential updates to daemons. Daemons maintain a persistent gRPC connection and receive updates in real time.
* **Tunnel server** — Provides a persistent, daemon-initiated channel the control plane uses to retrieve telemetry from daemons in a pull model.
* **Front proxy** — TLS-terminates inbound API and gRPC connections and routes them to the appropriate backend.
The control plane can be deployed as a managed service, a dedicated instance, or on-premises.
### Daemon
[Section titled “Daemon”](#daemon)
The daemon runs on every node that hosts workloads. In Kubernetes environments it runs as a DaemonSet; on bare-metal or VM hosts it runs as a standalone binary.
The daemon is responsible for:
* **Node attestation** — On startup, the daemon authenticates to the control plane using a configured Verifier (JoinToken, AWS Instance Identity Document, GCP Instance Identity Token, and others). This establishes the node’s identity.
* **Metadata collection** — Gathers host and workload metadata from the environment: Kubernetes pod labels, namespaces, and container names; AWS instance identity; OS information; network interfaces. This metadata drives workload attestation.
* **Policy synchronization** — Receives identity, service, and credential policies from the control plane and loads them into the kernel module.
* **Certificate operations** — Acts as a local certificate authority or forwards certificate signing requests to the control plane. Signs CSRs generated by the kernel module for workload SVIDs.
* **Kernel communication** — Communicates with the kernel module through the `/dev/riptides` character device using Protocol Buffer messages.
### Kernel Module
[Section titled “Kernel Module”](#kernel-module)
The kernel module is a Linux kernel module (not eBPF) that enforces security policy at the socket level. It intercepts TCP connections transparently and applies identity-based authentication and authorization without any application changes.
Key capabilities:
* **TLS/mTLS termination** — Performs full TLS 1.3, quantum-ready handshakes in kernel space. When kernel TLS (kTLS) is available, symmetric cryptographic operations are offloaded to kTLS for performance, with an in-kernel TLS implementation as a fallback.
* **Private key protection** — Workload private keys are generated and stored in kernel memory. They are never accessible from user space, eliminating an entire class of key-theft attacks.
* **Policy enforcement** — Evaluates access control rules at connection time. Connections that violate policy are dropped before any application code executes.
* **Credential injection** — Intercepts outbound HTTP requests and rewrites headers on the wire (for example, adding `Authorization` headers or AWS SigV4 signatures) before packets leave the machine. The application never handles the credential directly.
* **Transparent operation** — Applications connect using ordinary plaintext TCP sockets. The kernel module intercepts at the socket level and upgrades connections to TLS or mTLS as policy dictates.
## Trust Domains and SPIFFE
[Section titled “Trust Domains and SPIFFE”](#trust-domains-and-spiffe)
Riptides uses the SPIFFE (Secure Production Identity Framework for Everyone) standard for workload identity.
Every deployment operates within a **trust domain** (for example, `example.com`). Within a trust domain, each workload receives a **SPIFFE ID** of the form:
```plaintext
spiffe:///
```
Workloads prove their identity using **SVIDs** (SPIFFE Verifiable Identity Documents), which are X.509 certificates or JWT tokens containing the workload’s SPIFFE ID.
## Data Flow
[Section titled “Data Flow”](#data-flow)
The following describes how policy moves from declaration to enforcement:
1. **Declare** — An operator creates or updates identity, service, and credential policies on the control plane using CRDs.
2. **Distribute** — The control plane reconciles the policies and pushes the resulting configuration (certificates, access rules, credential bindings) to daemons over gRPC.
3. **Load** — Each daemon writes the configuration to the kernel module through the `/dev/riptides` character device.
4. **Enforce** — The kernel module applies the configuration immediately. New and existing connections are evaluated against the loaded policies. TLS handshakes use the provisioned certificates, and credential injection rules take effect on matching outbound requests.
This push-based architecture means policy changes propagate to all nodes without requiring workload restarts or redeployments.
# Connection Security
Riptides secures workload connections at the kernel level. Every TCP connection is evaluated against identity-based policies, and TLS is applied transparently without application changes. This document covers TLS modes, transparent mTLS, TLS handling strategies, and access control policies.
## TLS Modes
[Section titled “TLS Modes”](#tls-modes)
Each connection between a workload and a service operates in one of three TLS modes, configured on the WorkloadIdentity’s ingress or egress rules:
### MUTUAL
[Section titled “MUTUAL”](#mutual)
Both sides of the connection present X.509 SVIDs and verify each other’s identity. This is the strongest mode and the recommended default for internal service-to-service communication.
Riptides supports TLS 1.2 and TLS 1.3. TLS 1.2 is provided for compatibility with external services; for internal communication between Riptides-managed processes using `connection.tls.mode: MUTUAL`, the mTLS tunnel is always negotiated with TLS 1.3. With TLS 1.3, Riptides also offers PQC mTLS for internal service-to-service communication.
The kernel module performs the full mTLS handshake transparently. The application sends and receives plaintext; the kernel handles certificate exchange, verification, and encryption.
### SIMPLE
[Section titled “SIMPLE”](#simple)
Only the server side presents a certificate. The client verifies the server’s identity but does not present its own. Use this for connections to external services that require server authentication but do not support client certificates.
### PERMISSIVE
[Section titled “PERMISSIVE”](#permissive)
Accepts both plaintext and TLS connections on the same port. This mode is useful during migration: workloads that have been enrolled in Riptides will connect over mTLS, while workloads that have not yet been enrolled can still connect over plaintext.
Permissive mode is intended as a transitional step, not a permanent configuration. Once all connecting workloads are enrolled, switch to MUTUAL.
## Transparent mTLS
[Section titled “Transparent mTLS”](#transparent-mtls)
Riptides provides transparent mTLS: applications make ordinary plaintext TCP connections, and the kernel module automatically upgrades them to mutual TLS.
This works because the kernel module intercepts connections at the socket level. When a workload opens a connection to a destination that matches an egress rule with `connection.tls.mode: MUTUAL`, the kernel module:
1. Intercepts the TCP handshake.
2. Performs a TLS handshake with the remote side, presenting the workload’s X509 SVID.
3. Verifies the remote side’s SVID against the loaded trust bundle.
4. Encrypts all subsequent traffic using the negotiated session keys.
The application sees a normal TCP connection. It does not need TLS libraries, certificate files, or any awareness that encryption is happening.
On the receiving side, the kernel module on the destination node terminates the mTLS connection, verifies the caller’s SVID, evaluates ingress policies, and delivers plaintext to the application.
## TLS Handling Strategies
[Section titled “TLS Handling Strategies”](#tls-handling-strategies)
The kernel module handles connections differently depending on whether the application is already using TLS:
### TLS Intercept
[Section titled “TLS Intercept”](#tls-intercept)
When `connection.tls.intercept` is enabled, the kernel module terminates the application’s TLS connection locally, inspects and modifies the HTTP payload, then establishes a new TLS connection to the destination. The daemon evaluates the connection context and, if a credential injection is required, sets a reference in the evaluation context. The kernel checks for this reference and injects the credential before forwarding the request.
### TLS Pass-Through
[Section titled “TLS Pass-Through”](#tls-pass-through)
When a connection is already encrypted and no credential injection or policy evaluation at the HTTP layer is needed, the kernel module can wrap the existing encrypted connection in an additional Riptides mTLS layer for identity and policy enforcement. The original TLS payload is not re-encrypted; it passes through intact inside the outer mTLS tunnel.
The kernel module can inspect TLS handshake metadata (such as the ClientHello and ALPN extensions) to make routing and policy decisions without decrypting the payload.
## Ingress and Egress Policies
[Section titled “Ingress and Egress Policies”](#ingress-and-egress-policies)
Connection policies are defined on WorkloadIdentity resources and control both inbound and outbound connections.
### Egress
[Section titled “Egress”](#egress)
Egress rules specify which services a workload is allowed to connect to and under what conditions:
```yaml
spec:
egress:
- selectors:
- tier: backend
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- "spiffe://example.com/orders-service"
- "spiffe://example.com/inventory-service"
```
* **egress\[].selectors** - Matches destination services by label. See [Services](../services).
* **egress\[].connection.tls.mode** - The TLS mode for the connection (MUTUAL, SIMPLE, or PERMISSIVE).
* **egress\[].allowedSPIFFEIDs** - Restricts which SPIFFE IDs the remote service must present. If specified, the connection is only established if the remote side’s SVID matches one of the listed identities.
### Ingress
[Section titled “Ingress”](#ingress)
Ingress rules specify which workloads are allowed to connect to this workload:
```yaml
spec:
ingress:
- port: 8000
allowedSPIFFEIDs:
- "spiffe://example.com/frontend"
- "spiffe://example.com/monitoring"
```
* **ingress\[].port** - The port on which this rule applies.
* **ingress\[].allowedSPIFFEIDs** - Only workloads presenting one of the listed SPIFFE IDs are allowed to connect. Connections from any other identity are rejected at the TLS handshake.
If no `allowedSPIFFEIDs` are specified, any workload within the trust domain that satisfies the TLS mode requirement can connect.
#### Restricting unauthenticated access by HTTP path
[Section titled “Restricting unauthenticated access by HTTP path”](#restricting-unauthenticated-access-by-http-path)
On a `PERMISSIVE` port, an ingress rule can additionally limit which HTTP request paths an **unauthenticated** caller (a plaintext client presenting no SPIFFE identity) may reach, using `httpRequestPath`:
```yaml
spec:
ingress:
- port: 8080
connection:
protocol: HTTP1
tls:
mode: PERMISSIVE
httpRequestPath:
- /healthz
- /readyz
```
The port still accepts the plaintext connection, but the kernel module inspects each request and forwards only the listed paths. Any other request - or anything that is not a recognizable HTTP/1 request - is reset, the same outcome a `MUTUAL` port gives an unauthenticated caller. Clients presenting a valid mTLS identity are not restricted and reach every path.
This is the typical pattern for health and readiness probes. A probe such as `GET /healthz` from a kubelet carries no workload identity, so a `MUTUAL` port would reject it; allowlisting just the probe paths lets it through while every other path on the port still requires identity. `httpRequestPath` requires `connection.protocol: HTTP1` and matches paths exactly, ignoring the query string.
## Connection Flow Example
[Section titled “Connection Flow Example”](#connection-flow-example)
Consider a frontend workload connecting to an internal orders service:
1. The frontend application opens a plaintext TCP connection to `orders-service.internal.example.com:8080`.
2. The kernel module intercepts the connection and negotiates with the remote side to establish whether the peer is also a Riptides-managed workload.
3. The kernel module initiates an mTLS handshake, presenting the frontend’s SVID (`spiffe://example.com/frontend`) and verifying the peer’s SPIFFE SAN.
4. The kernel module on the orders service node terminates the mTLS connection and checks the ingress policy. The frontend’s SPIFFE ID is in the `allowedSPIFFEIDs` list.
5. The connection is established. Both sides exchange plaintext with their local kernel modules, while the network carries encrypted, mutually authenticated traffic.
# Credentials
Not all services support SPIFFE-based mutual TLS. External APIs, cloud provider services, and legacy systems typically require bearer tokens, API keys, or signed requests. Riptides bridges this gap with a credential pipeline that binds secrets to attested workload identities and delivers them without exposing credentials to application code.
## How Credentials Work
[Section titled “How Credentials Work”](#how-credentials-work)
Credential management in Riptides is built around two ideas:
* **Where a credential comes from.** You describe the integration with an external credential provider - how to authenticate to it and how to retrieve or generate a credential. Each provider type handles its own specifics.
* **Which workloads receive it, and how.** You connect a credential to one or more workloads and choose how it should be delivered to each.
Keeping these separate means a single credential definition can be reused across many workloads with different delivery mechanisms, and provider configuration is managed independently from workload policy.
## JWT-SVID Credential Federation
[Section titled “JWT-SVID Credential Federation”](#jwt-svid-credential-federation)
Riptides issues JWT-SVIDs for attested workloads - signed JWTs containing the workload’s SPIFFE ID and other claims. Cloud providers support workload identity federation, allowing Riptides to exchange a workload’s JWT-SVID for temporary cloud credentials without any long-lived keys:
1. The control plane presents the workload’s JWT-SVID to the cloud provider’s STS endpoint.
2. The cloud provider validates the JWT-SVID and issues temporary, scoped credentials.
3. The control plane pushes those credentials to the daemon, which loads them into the kernel for injection.
This is the mechanism behind the AWS, GCP, and Azure provider types.
For step-by-step setup, see the [Secretless AWS Access](../guides/secretless-aws) and [Secretless GCP Access](../guides/secretless-gcp) guides.
## Provider Types
[Section titled “Provider Types”](#provider-types)
| Type | Description |
| ----------------- | ------------------------------------------------------------------------------------------------------------------- |
| **AWS** | Exchanges the workload’s JWT-SVID with AWS STS via `AssumeRoleWithWebIdentity` to obtain temporary IAM credentials. |
| **GCP** | Exchanges a workload identity token for GCP access credentials via Workload Identity Federation. |
| **Azure** | Exchanges a workload identity token for Azure access credentials via federated identity credentials. |
| **Vault/OpenBao** | Authenticates to HashiCorp Vault or OpenBao and retrieves a secret or dynamic credential. |
| **Static** | Stores a static, pre-provisioned secret such as a long-lived API key or token. |
| **JWT** | Issues a signed JWT with custom claims, useful for authenticating to APIs that accept JWT bearer tokens. |
| **OAuth2** | Performs an OAuth2 client credentials or authorization code flow to obtain an access token. |
| **OCI** | Retrieves credentials for OCI-compliant container registries. |
## Delivery Mechanisms
[Section titled “Delivery Mechanisms”](#delivery-mechanisms)
Once a credential is obtained, Riptides delivers it to the workload through one of two mechanisms:
### Injection (On-the-Wire Header Rewriting)
[Section titled “Injection (On-the-Wire Header Rewriting)”](#injection-on-the-wire-header-rewriting)
The kernel module intercepts outbound HTTP requests and adds or rewrites headers before the packets leave the machine. The application makes a plain HTTP request; by the time it reaches the destination, the kernel has injected the required credentials.
Examples of injected credentials:
* **Bearer tokens** - The kernel adds an `Authorization: Bearer ` header to outgoing requests.
* **AWS SigV4** - The kernel computes the AWS Signature Version 4 signing process and adds the `Authorization`, `X-Amz-Date`, `X-Amz-Security-Token`, and other required headers.
* **Custom headers** - Arbitrary header injection for APIs that expect credentials in non-standard headers.
This is the recommended delivery mechanism. The credential exists only in kernel memory and is written directly into the network buffer. It is never exposed to user-space processes, environment variables, or the filesystem.
### Sysfs (Secure File-Based Delivery)
[Section titled “Sysfs (Secure File-Based Delivery)”](#sysfs-secure-file-based-delivery)
For applications that read credentials from the filesystem (such as SDK-based credential providers or legacy applications), Riptides exposes credential files through the kernel module’s sysfs interface:
```plaintext
/sys/module/riptides/credentials//token
```
The kernel module owns these files and controls access. Credentials are refreshed automatically as they rotate. Applications that watch the filesystem or re-read on each use will always get a current credential.
## Credential Lifecycle
[Section titled “Credential Lifecycle”](#credential-lifecycle)
Credentials managed by Riptides are short-lived and automatically refreshed:
1. **Initial fetch** - When a credential is bound to a workload, the control plane obtains it from the configured provider and pushes it to the daemon.
2. **Delivery** - The daemon loads the credential into the kernel module for injection, or exposes it via sysfs.
3. **Rotation** - Before the credential expires, the control plane fetches a new one and pushes it to the daemon, which updates the kernel module. For injection, the kernel immediately uses the new credential on subsequent requests. For sysfs, the file contents are updated atomically.
4. **Revocation** - When a binding is removed or the workload no longer matches its identity selectors, the credential is deleted from the kernel module. Injection stops, and sysfs files are removed.
The entire lifecycle is automatic. Operators define where credentials come from and which workloads receive them; the platform handles retrieval, delivery, rotation, and cleanup.
## Example
[Section titled “Example”](#example)
An application that needs to access an AWS S3 bucket:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: s3-access
namespace: riptides-system
spec:
aws:
roleArn: "arn:aws:iam:::role/"
awsRegion: "us-east-1"
---
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: frontend-s3
namespace: riptides-system
spec:
workloadID: frontend/workload
credentialSource: s3-access
propagation:
injection:
selectors:
- app: frontend
service: s3
```
With this configuration:
1. The control plane issues an OIDC token for the frontend workload.
2. AWS STS exchanges the token for temporary credentials scoped to the specified IAM role.
3. The kernel module signs outbound S3 requests with SigV4 headers.
4. The frontend application calls S3 using plain HTTP. It never sees or handles AWS credentials.
# Trust Domain Federation
Trust domain federation enables workloads in separate Riptides deployments to authenticate to each other across trust boundaries. Each Riptides deployment operates its own trust domain with its own CA. Federation is the mechanism by which two trust domains can validate each other’s SVIDs without merging into a single deployment.
## Trust Bundles
[Section titled “Trust Bundles”](#trust-bundles)
A trust bundle contains the signing CA certificates for a trust domain. The control plane distributes the local trust bundle to all daemons. When a workload receives a connection from a remote workload, the kernel module validates the remote SVID against the trust bundle for that domain.
To accept connections from a foreign trust domain, that domain’s trust bundle must be loaded into the local control plane and distributed to daemons.
## Cross-Domain Federation
[Section titled “Cross-Domain Federation”](#cross-domain-federation)
Multiple Riptides deployments, each operating their own trust domain, can federate by exchanging trust bundles. This enables:
* **Multi-cluster communication** - Workloads in different Kubernetes clusters (each with its own trust domain) can authenticate to each other via mTLS using their respective SPIFFE IDs.
* **Multi-cloud communication** - Workloads running in different cloud providers, managed by separate control planes, can establish trusted connections.
* **Partner and third-party access** - Organizations can share trust bundles with partners, allowing cross-organization workload authentication without sharing credentials.
### How It Works
[Section titled “How It Works”](#how-it-works)
1. Each control plane publishes its trust bundle (the signing CA certificates for its trust domain).
2. Administrators configure each control plane to trust the other domain’s bundle.
3. The control planes distribute the foreign trust bundles to their daemons.
4. The kernel module loads all trust bundles and can verify SVIDs from any trusted domain.
When a workload in `example.com` connects to a workload in `partner.com`, the kernel modules on both sides verify the remote SVID against the appropriate trust bundle. Ingress and egress policies can reference SPIFFE IDs from foreign trust domains in their `allowedSPIFFEIDs` lists.
### Example
[Section titled “Example”](#example)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: TrustBundle
metadata:
name: partner-trust
namespace: riptides-system
spec:
trustDomain: "partner.com"
bundle: |
-----BEGIN CERTIFICATE-----
-----END CERTIFICATE-----
```
With this trust bundle loaded, workloads in the local trust domain can verify and accept connections from workloads presenting SVIDs issued by `partner.com`.
# Kernel Module
Riptides uses a Linux kernel module to enforce security policies transparently at the socket level. The kernel module handles TLS/mTLS termination, credential injection, and policy enforcement - all without requiring any changes to application code.
## Why a Kernel Module?
[Section titled “Why a Kernel Module?”](#why-a-kernel-module)
Riptides chose a kernel module over eBPF for several technical reasons. eBPF programs are sandboxed and limited in what they can do - they cannot generate cryptographic keys, perform full TLS handshakes, inject credentials into HTTP streams, or create sysfs filesystem entries. These are all core capabilities that Riptides requires:
| Capability | eBPF | Kernel Module |
| ---------------------------------------- | ------- | ------------- |
| Generate private keys | No | Yes |
| Full TLS handshakes | No | Yes |
| Credential injection (header rewriting) | No | Yes |
| Sysfs filesystem for credential delivery | No | Yes |
| Policy enforcement at socket level | Limited | Yes |
| Private keys isolated from userspace | No | Yes |
The kernel module approach means private keys are generated and stored exclusively in kernel memory - they are never accessible from userspace, even by the application they belong to.
## TLS in Kernel Space
[Section titled “TLS in Kernel Space”](#tls-in-kernel-space)
Riptides runs a compact TLS library in kernel space that provides:
* TLS 1.3, with TLS 1.2 supported for interoperability with legacy peers
* Modern AEAD cipher suites: AES-256-GCM, AES-128-GCM, and ChaCha20-Poly1305
* X.509 certificate handling and SPIFFE identity verification
* Small memory footprint suitable for kernel context
The in-kernel TLS implementation handles the initial handshake (key exchange, certificate verification) and can process the ongoing encrypted stream when kTLS offload is not available.
For transparent mTLS between Riptides-managed workloads, the internal connection is always established with TLS 1.3.
## Quantum Safety
[Section titled “Quantum Safety”](#quantum-safety)
Riptides protects the confidentiality of mesh traffic against quantum attack today, including the *harvest-now, decrypt-later* threat where an adversary records encrypted traffic now to decrypt once a quantum computer exists. Both layers that establish and protect the data stream - the key exchange and the symmetric cipher - are quantum-resistant. Authentication (certificate signatures) remains classical for now.
### Key exchange - post-quantum hybrid
[Section titled “Key exchange - post-quantum hybrid”](#key-exchange---post-quantum-hybrid)
Session keys are established with a **post-quantum hybrid key exchange**. The `X25519MLKEM768` group combines **ML-KEM-768** (FIPS 203, the standardized successor to Kyber) with classical **X25519**: the shared secret is derived from both an ML-KEM encapsulation and an X25519 Diffie-Hellman exchange. The result is at least as strong as X25519 and adds post-quantum protection, so recorded handshakes cannot be broken by a future quantum computer.
ML-KEM runs entirely in kernel space as part of the in-kernel TLS 1.3 handshake, using a kernel-native FIPS 203 implementation (the SHA-3/SHAKE primitives it depends on are built into the module). Because the handshake always runs in the module - kTLS only offloads the symmetric layer afterward - the post-quantum key exchange applies whether or not kTLS is in use.
The exchange degrades gracefully. For transparent mTLS between Riptides workloads, both ends support the hybrid group and negotiate it directly. For other destinations - including TLS intercept toward external servers - the classical groups remain on offer, so a peer that does not support the hybrid falls back to X25519 automatically: post-quantum wherever the peer allows it, with no loss of connectivity where it does not.
### Symmetric layer - quantum-resistant
[Section titled “Symmetric layer - quantum-resistant”](#symmetric-layer---quantum-resistant)
Bulk traffic is protected by 256-bit AEAD cipher suites - **AES-256-GCM** and **ChaCha20-Poly1305**, which the module offers ahead of their 128-bit counterparts, so a mesh connection negotiates one of them. Symmetric ciphers of this strength are considered quantum-resistant: the best known quantum attack (Grover’s algorithm) only halves the effective key length, leaving AES-256 and ChaCha20 at roughly 128 bits of post-quantum security. AES-128-GCM stays on offer for peers that require it - relevant only for TLS intercept toward external servers, where the remote end picks the suite.
### Authentication - classical today
[Section titled “Authentication - classical today”](#authentication---classical-today)
Workload identities are still authenticated with classical signatures - ECDSA (P-256/P-384) or RSA - over SPIFFE X.509 certificates. ML-KEM protects the key exchange (confidentiality), not authentication, so this remains a classical primitive. It is a lower-urgency gap than key exchange: forging a signature requires an active attack at connection time rather than passive recording, so it is not exposed to harvest-now-decrypt-later. Post-quantum signatures (such as ML-DSA / FIPS 204) are a future step.
Note
The negotiated key-exchange group is visible per connection in `/proc/riptides/connections` as `kex_group` - `X25519MLKEM768` indicates the post-quantum hybrid handshake, `X25519` indicates a classical fallback.
## kTLS Integration
[Section titled “kTLS Integration”](#ktls-integration)
When the kernel’s built-in TLS support ([kTLS](https://docs.kernel.org/networking/tls-offload.html)) is available, Riptides offloads symmetric encryption to it for better performance. The flow is:
1. The in-kernel TLS implementation performs the handshake (asymmetric crypto, certificate exchange)
2. Once the session is established, symmetric keys are handed to kTLS
3. kTLS handles bulk data encryption/decryption in the kernel’s networking stack
If kTLS is not available or not applicable for a particular connection, the in-kernel TLS implementation handles the entire TLS session as a fallback.
## Transparent Operation
[Section titled “Transparent Operation”](#transparent-operation)
Applications connect to network services using standard TCP sockets - no TLS libraries, no certificate management code, no authentication logic. The kernel module intercepts connections at the socket level and:
1. **Outbound connections**: Initiates a TLS/mTLS handshake with the destination and optionally injects credentials into the HTTP stream based on the evaluation context set by the daemon
2. **Inbound connections**: Terminates TLS, verifies the client certificate against allowedSPIFFEIDs, and forwards plaintext to the application
From the application’s perspective, it sends and receives plaintext. From the network’s perspective, all traffic is encrypted and authenticated.
## TLS Termination Modes
[Section titled “TLS Termination Modes”](#tls-termination-modes)
The module supports several TLS handling strategies depending on the connection and policy:
* **Transparent mTLS**: Plaintext connections are automatically upgraded to mTLS. Both endpoints present SPIFFE certificates.
* **TLS intercept**: The module terminates an existing TLS connection and re-establishes it, allowing credential injection into the HTTP stream between the two TLS sessions. Because the module presents a Riptides-issued certificate to the application, any userspace library or SDK that performs its own TLS verification must be configured to trust the Riptides CA. See [Trusting the Riptides CA](#trusting-the-riptides-ca-for-tls-intercept) below.
* **TLS pass-through**: For connections that are already encrypted, the module can wrap them in an additional Riptides mTLS layer for identity verification without modifying the original payload. The original TLS is not double-encrypted - the Riptides layer provides identity and policy enforcement only.
## Trusting the Riptides CA for TLS Intercept
[Section titled “Trusting the Riptides CA for TLS Intercept”](#trusting-the-riptides-ca-for-tls-intercept)
When `tls.intercept: true` is configured on an egress rule, the kernel module terminates the application’s outbound TLS connection and re-originates a new one to the destination. The application sees a Riptides-issued certificate instead of the destination’s original certificate.
Any userspace library or SDK that performs its own certificate verification will reject this certificate unless configured to trust the Riptides CA. The CA bundle is available at:
```plaintext
/sys/module/riptides/certs/ca-certificates.crt
```
Configure your application’s TLS trust store to include this file. Common environment variables:
| SDK / Library | Environment Variable |
| ----------------- | -------------------------------------------------------------------- |
| AWS SDK | `AWS_CA_BUNDLE=/sys/module/riptides/certs/ca-certificates.crt` |
| Python `requests` | `REQUESTS_CA_BUNDLE=/sys/module/riptides/certs/ca-certificates.crt` |
| Node.js | `NODE_EXTRA_CA_CERTS=/sys/module/riptides/certs/ca-certificates.crt` |
| Go (net/http) | `SSL_CERT_FILE=/sys/module/riptides/certs/ca-certificates.crt` |
| Generic OpenSSL | `SSL_CERT_FILE=/sys/module/riptides/certs/ca-certificates.crt` |
| cURL | `CURL_CA_BUNDLE=/sys/module/riptides/certs/ca-certificates.crt` |
Alternatively, you can append the Riptides CA to your system’s existing CA bundle if you prefer a single trust store.
## Credential Injection
[Section titled “Credential Injection”](#credential-injection)
One of the kernel module’s unique capabilities is on-the-wire credential injection. When a CredentialBinding is configured with injection propagation, the module:
1. Intercepts outbound HTTP requests at the socket level
2. Adds or rewrites HTTP headers (e.g., `Authorization: Bearer `, AWS SigV4 signature headers)
3. Forwards the modified request to the destination
The application makes a plain HTTP request without any authentication headers. The daemon evaluates the connection context and determines which credentials to inject; the kernel checks the evaluation context and adds them transparently. This means credentials are never exposed in application memory.
## Sysfs Based Secure Credential Delivery
[Section titled “Sysfs Based Secure Credential Delivery”](#sysfs-based-secure-credential-delivery)
For applications that need to read credentials from the filesystem (e.g., GCP Application Default Credentials), the kernel module provides credentials via sysfs:
```plaintext
/sys/module/riptides/credentials///token.jwt
```
Applications can read credential files from this path. The kernel module owns these files, controls access, and manages credential rotation automatically. Reading the file always returns a current, valid credential.
## Daemon Communication
[Section titled “Daemon Communication”](#daemon-communication)
The kernel module communicates with the userspace daemon via the `/dev/riptides` character device. The daemon uses Protocol Buffers over this interface to:
* Push identity configurations (certificates, private keys, SPIFFE IDs)
* Push service definitions (addresses, ports, labels)
* Push credential bindings and policies
* Receive health and status information
The daemon acts as the bridge between the control plane (which manages policy centrally) and the kernel module (which enforces policy locally).
## Diagnostics
[Section titled “Diagnostics”](#diagnostics)
The module exposes diagnostic information through procfs and sysfs:
| Endpoint | Description |
| ----------------------------------- | ----------------------------------- |
| `/sys/module/riptides/health` | Module health status |
| `/proc/riptides/certificates` | Loaded certificates (JSON) |
| `/proc/riptides/connections` | Active connections (JSON) |
| `/proc/riptides/trust_anchors` | Trust anchor certificates (JSON) |
| `/sys/module/riptides/certs/` | CA bundle, SPIFFE and intercept CAs |
| `/sys/module/riptides/credentials/` | Credential files |
`/proc/riptides/connections` lists **live** sockets only, so a connection that has already closed will not appear - sample it while traffic is flowing.
Each entry carries an `alpn` field, which is what tells the TLS handling modes apart - `tls_version`, `mtls_version` and the SPIFFE ids look the same either way:
| `alpn` | Meaning |
| ---------------------- | ----------------------------------------------------- |
| `riptides` | the module terminated TLS on this connection |
| `riptides/passthrough` | it authenticated both ends and left the payload alone |
| *(empty)* | no Riptides handshake ran on this connection |
```json
{"dst": "127.0.0.1:6379", "tls_version": "TLS1.2", "mtls_version": "TLS1.3",
"spiffe_id": "spiffe://example.console.riptides.io/cache/client",
"peer_spiffe_id": "spiffe://example.console.riptides.io/cache/redis",
"alpn": "riptides/passthrough"}
```
### Asking the kernel about a connection
[Section titled “Asking the kernel about a connection”](#asking-the-kernel-about-a-connection)
The connections file above answers this for an operator looking at a node. An application can ask the same question about one of its *own* sockets with `getsockopt`, which is what you want in a test asserting that a connection really was protected, or when the application needs to behave differently depending on the answer:
```c
#define SOL_RIPTIDES 7891
#define RIPTIDES_TLS_INFO 1
typedef struct {
bool riptides_enabled;
char mtls_type[16];
char spiffe_id[256];
char peer_spiffe_id[256];
char alpn[256];
} riptides_tls_info;
```
The `alpn` field is what identifies the mode: `riptides` means the module terminated TLS on this connection, and `riptides/passthrough` means it authenticated both ends and left the payload alone.
```python
import ctypes, socket, ssl
SOL_RIPTIDES, RIPTIDES_TLS_INFO = 7891, 1
class RiptidesTlsInfo(ctypes.Structure):
_fields_ = [("riptides_enabled", ctypes.c_bool),
("mtls_type", ctypes.c_char * 16),
("spiffe_id", ctypes.c_char * 256),
("peer_spiffe_id", ctypes.c_char * 256),
("alpn", ctypes.c_char * 256)]
raw = sock.getsockopt(SOL_RIPTIDES, RIPTIDES_TLS_INFO,
ctypes.sizeof(RiptidesTlsInfo))
info = RiptidesTlsInfo.from_buffer_copy(raw)
print(info.alpn, info.spiffe_id, info.peer_spiffe_id)
```
The call fails with `EOPNOTSUPP` when the socket is not a Riptides socket, or when its handshake has not completed yet - which is itself the answer to “is this connection protected?”.
### When evaluation or the handshake fails
[Section titled “When evaluation or the handshake fails”](#when-evaluation-or-the-handshake-fails)
If the daemon cannot answer within the module’s `command_timeout`, or an mTLS handshake fails - a missing trust anchor, for instance - the module’s behaviour depends on one parameter:
```bash
cat /sys/module/riptides/parameters/eval_fail_closed # N by default
```
**By default the module fails open:** the connection proceeds *unprotected* rather than breaking. That keeps a control-plane problem from becoming an application outage, but it means losing protection is invisible from the application’s point of view - it still succeeds, and its logs still look healthy. The signals are `dmesg`, and `/proc/riptides/connections` showing connections with no `spiffe_id`.
Set `eval_fail_closed=Y` to reset such connections instead, and monitor for it either way.
You can also enable/disable the module at runtime without unloading it, and toggle debug logging via the kernel’s dynamic debug facility.
## Platform Support
[Section titled “Platform Support”](#platform-support)
The kernel module runs on Linux and supports:
* **Architectures**: x86\_64, ARM64
* **Environments**: Bare metal, VMs, Kubernetes nodes, WSL2 on Windows hosts
* **Installation**: Pre-built `.deb`/`.rpm` packages via the Riptides package repository
* **IPv4 and IPv6** TCP sockets
On Windows hosts the module loads inside the WSL2 VM, against Microsoft’s WSL2 kernel. That kernel is versioned separately from the distribution and is replaced by `wsl --update`, so the driver is matched to it per kernel version - see [WSL2 on Windows](/deployment/daemon-bare-metal/#wsl2-on-windows).
# mTLS Without Service Definitions
No `Service` resource or egress rule is required for internal mTLS between two Riptides-managed workloads, provided both peers share the same trust domain (CA) and the peers successfully identify each other as Riptides-managed. When those conditions are met, Riptides automatically establishes a full mutual TLS session with zero service-definition overhead.
## How It Works
[Section titled “How It Works”](#how-it-works)
Ordinarily, policy evaluation at connection time checks both whether the connecting workload has a valid identity (selector match) and whether a service rule authorizes the specific destination. Implicit mTLS splits this check into three stages:
1. **Identity resolution.** The daemon evaluates the connecting workload’s `WorkloadIdentity` selectors. If a match is found, the workload receives a valid SPIFFE identity, regardless of whether a service rule exists for this connection.
2. **Peer confirmation.** The peer must be Riptides-managed and share the same trust domain (CA).
3. **Certificate cross-check.** The SPIFFE SAN in the peer’s X.509 certificate must match the identity the peer announced during connection setup. A mismatch causes the connection to be rejected immediately.
If either peer is not Riptides-managed or does not share the same trust domain (CA), the implicit mTLS conditions are not met and the connection falls back to plain TCP (observed but not intercepted). In those cases an explicit `Service` resource with egress rules is required.
## Minimal Configuration
[Section titled “Minimal Configuration”](#minimal-configuration)
No `Service` resource and no egress rules are required. Define a `WorkloadIdentity` for each workload:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: service-a
namespace: riptides-system
spec:
workloadID: myapp/service-a
selectors:
- process:name: service-a
scope:
daemonGroup:
id: daemongroup/production/workers
```
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: service-b
namespace: riptides-system
spec:
workloadID: myapp/service-b
selectors:
- process:name: service-b
scope:
daemonGroup:
id: daemongroup/production/workers
```
Once both `WorkloadIdentity` resources are applied, any connection between `service-a` and `service-b` is automatically secured with mTLS. No `Service` resource, no egress selectors, no `allowedSPIFFEIDs` lists needed.
## Security Characteristics
[Section titled “Security Characteristics”](#security-characteristics)
* **STRICT mTLS always.** Both sides must present a valid X.509 SVID issued by the shared trust domain. There is no plaintext fallback once implicit mTLS is active.
* **Top-level `allowedSPIFFEIDs` are enforced.** If the `WorkloadIdentity` defines top-level `allowedSPIFFEIDs` (outbound on the client side, inbound on the server side), those restrictions apply even for implicit mTLS connections. Per-egress and per-ingress `allowedSPIFFEIDs` defined inside a `Service` do not apply - no service rule exists to select them.
* **Identity confirmed via two channels.** The identity the peer announces during connection setup and the SPIFFE SAN in the TLS certificate must agree. A peer that announces one identity but presents a certificate for a different workload is rejected before any application data is exchanged.
* **Only top-level workload identity is evaluated.** When no service rule exists, only the selector match that establishes the workload’s identity is considered. Egress label selectors, credential rules, and service-level `allowedSPIFFEIDs` defined inside a `Service` are not in scope - those apply only to explicitly configured connections.
## When to Use Explicit Service Definitions Instead
[Section titled “When to Use Explicit Service Definitions Instead”](#when-to-use-explicit-service-definitions-instead)
Implicit mTLS is the right default for trusted internal mesh traffic where any enrolled peer is acceptable. Use an explicit [`Service`](../services) resource with egress rules when you need:
* **Per-destination caller restrictions** - `allowedSPIFFEIDs` on an egress or ingress rule limits connections to specific identities for a particular destination. Top-level `allowedSPIFFEIDs` on a `WorkloadIdentity` are enforced for implicit mTLS connections too, but they apply globally, not per-destination.
* **Credential injection** - HTTP headers, AWS SigV4 signing, JWT credentials, or other credentials are attached per destination.
* **External services** - Connections to endpoints that are not Riptides-managed (cloud APIs, third-party services, legacy systems).
* **Per-destination TLS mode** - PERMISSIVE or SIMPLE mode on a specific destination, for example during a migration.
## Comparison
[Section titled “Comparison”](#comparison)
| | Implicit mTLS | Explicit Service + Egress |
| ------------------------- | ---------------------------------------- | ----------------------------------------------------------- |
| **Required config** | WorkloadIdentity only | WorkloadIdentity + Service + egress rules |
| **TLS mode** | Always STRICT | Configurable (MUTUAL / PERMISSIVE / SIMPLE) |
| **Caller restrictions** | Top-level `allowedSPIFFEIDs` only | Top-level + per-egress/ingress `allowedSPIFFEIDs` |
| **Credential injection** | Not supported | Supported |
| **External destinations** | Not applicable | Supported |
| **Best for** | Internal mesh between enrolled workloads | Fine-grained access control, credentials, external services |
# Node Attestation
Node attestation establishes trust between a daemon and the control plane. When a daemon starts, it must prove its identity using a **Verifier** configured on the control plane. Only after successful node attestation does the daemon receive policies and certificates.
This is distinct from [workload attestation](../workload-attestation), which happens afterward, at connection time, to identify individual processes on an already-attested node.
## How It Works
[Section titled “How It Works”](#how-it-works)
Each Verifier type implements a **proof mechanism** appropriate to the node’s environment: a signed cloud instance document, a JWT from a trusted issuer, proof of possession of a certificate, or a pre-shared token. The daemon (acting as a **Claimer**) produces a proof and sends it to the control plane; the control plane (acting as a **Verifier**) validates it and, on success, extracts a set of **metadata labels** from the proof.
Some mechanisms are proof-of-possession based: after the initial proof is validated, the control plane issues a random nonce **challenge**, and the daemon must sign it with the private key associated with the proof to complete attestation. This prevents a stolen certificate or token from being replayed without also having the corresponding private key.
Metadata labels are namespaced by verifier type, e.g. `awsiid:account:id` or `githubactions:repository:owner`. They serve two purposes:
* **Scoping with `requiredMetadata`.** A Verifier can restrict which daemons it accepts by requiring specific metadata values, for example only EC2 instances in one AWS account, or only GitHub Actions runs from one repository. `requiredMetadata` is a list of key-value groups; a daemon matches if its metadata satisfies **all** keys within **any one** group (AND within a group, OR across groups):
```yaml
requiredMetadata:
- awsiid:account:id: "111111111111"
awsiid:region: "us-east-1"
- awsiid:account:id: "222222222222"
awsiid:region: "eu-west-1"
```
This accepts daemons from account `111111111111` in `us-east-1`, **or** account `222222222222` in `eu-west-1`.
* **Generating workload IDs with `workloadIDTemplate`.** A Go template string that renders the daemon’s `workloadID` from its attestation metadata, so IDs don’t have to be assigned manually.
`requiredMetadata` is enforced (and rejected at admission time if missing) for the cloud verifiers (AWSIID, GCPIIT, AzureIMDS) and for GitHubActions, since without it any workload in the provider’s namespace (any AWS account, any GCP project, any GitHub org) could attest successfully.
## Verifier Types
[Section titled “Verifier Types”](#verifier-types)
| Verifier | Environment | Proof mechanism | Proof of possession challenge |
| ----------------- | --------------- | ----------------------------------------------------------------------------------- | ----------------------------- |
| **JoinToken** | Any | A pre-shared token created on the control plane. | Yes |
| **AWSIID** | AWS | The signed EC2 Instance Identity Document. | No |
| **GCPIIT** | GCP | A signed GCP Instance Identity Token (JWT). | No |
| **AzureIMDS** | Azure | A signed Azure IMDS managed-identity token (JWT). | No |
| **GitHubActions** | GitHub Actions | A signed OIDC token issued by GitHub’s Actions token endpoint. | No |
| **K8sSAT** | Kubernetes | A projected Kubernetes Service Account Token, validated against the cluster’s JWKS. | No |
| **JWT** | Any | A JWT from any trusted issuer. | No |
| **X509CertPOP** | Any with PKI | An X.509 certificate issued by a trusted CA. | Yes |
| **SSHCertPOP** | Any with SSH CA | An SSH certificate issued by a trusted CA. | Yes |
Verifiers are defined as CRDs on the control plane. Multiple verifiers can coexist, allowing daemons in different environments to attest using the mechanism native to their platform. Full field-level configuration for each type is in the [Verifier reference](../../reference/verifier).
## Metadata by Provider
[Section titled “Metadata by Provider”](#metadata-by-provider)
The tables below list every metadata label each verifier can produce. Values marked “self-reported, unverified” are not part of the cryptographically signed proof and should not be relied on for security-sensitive scoping.
### JoinToken
[Section titled “JoinToken”](#jointoken)
| Key | Description |
| ---------------------------- | ---------------------------------------------------------------------------------------------------------- |
| `jointoken:workload:id` | The `workloadID` configured on the matched JoinToken resource, if set. |
| `jointoken:created-by:email` | The email in the JoinToken’s `riptides.io/created-by` annotation, if the token was created through the UI. |
JoinToken carries no environmental metadata of its own; it only proves possession of the shared secret. Scoping is done by giving each token its own `workloadID`, not via `requiredMetadata`.
### AWSIID
[Section titled “AWSIID”](#awsiid)
Extracted from the EC2 Instance Identity Document:
| Key | Description |
| -------------------------- | ------------------------------------- |
| `awsiid:architecture` | Instance CPU architecture. |
| `awsiid:billing_products` | Billing product codes (multi-valued). |
| `awsiid:startup_time` | The document’s `pendingTime`. |
| `awsiid:private_ip` | Instance private IP address. |
| `awsiid:region` | AWS region. |
| `awsiid:availability:zone` | Availability zone. |
| `awsiid:image:id` | AMI ID. |
| `awsiid:account:id` | AWS account ID. |
| `awsiid:instance:id` | EC2 instance ID. |
| `awsiid:instance:type` | EC2 instance type. |
| `awsiid:ramdisk:id` | Ramdisk ID, if present. |
| `awsiid:kernel:id` | Kernel ID, if present. |
### GCPIIT
[Section titled “GCPIIT”](#gcpiit)
Extracted from the GCP Instance Identity Token claims:
| Key | Description |
| ---------------------------- | ---------------------------------------------------------------- |
| `gcpiit:email` | Service account email. |
| `gcpiit:instance:created_at` | Instance creation timestamp. |
| `gcpiit:instance:name` | Compute Engine instance name. |
| `gcpiit:instance:id` | Compute Engine instance ID. |
| `gcpiit:project:id` | GCP project ID. |
| `gcpiit:project:number` | GCP project number. |
| `gcpiit:zone` | Compute Engine zone. |
| `gcpiit:region` | Derived from the zone (e.g. `us-central1` from `us-central1-a`). |
| `gcpiit:token:issuer` | Token `iss` claim. |
| `gcpiit:token:audience` | Token `aud` claim. |
| `gcpiit:token:subject` | Token `sub` claim. |
### AzureIMDS
[Section titled “AzureIMDS”](#azureimds)
Extracted from the Azure IMDS managed-identity token claims and the `xms_mirid` resource ID:
| Key | Description |
| ------------------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `azureimds:tenant:id` | Azure AD tenant ID (`tid` claim). |
| `azureimds:identity:object_id` | Managed identity object ID (`oid` claim). |
| `azureimds:identity:client_id` | Managed identity client ID (`appid` on v1 tokens, `azp` on v2). |
| `azureimds:token:subject` | Token `sub` claim. |
| `azureimds:token:issuer` | Token `iss` claim. |
| `azureimds:subscription:id` | Azure subscription ID, parsed from `xms_mirid`. |
| `azureimds:resource_group` | Resource group name, parsed from `xms_mirid`. |
| `azureimds:instance:name` | VM name, parsed from `xms_mirid` (system-assigned identity on a VM). |
| `azureimds:instance:scale_set` | VMSS name, parsed from `xms_mirid` (system-assigned identity on a scale set). |
| `azureimds:identity:name` | User-assigned identity name, parsed from `xms_mirid` (e.g. AKS nodes, which share the kubelet identity). |
| `azureimds:instance:vm_id` | **Self-reported, unverified.** The node’s VM ID from the unsigned IMDS instance-metadata endpoint. Used as the only per-node discriminator on AKS, where every node shares the same managed identity and JWT claims. Never overrides a JWT-derived label. |
### GitHubActions
[Section titled “GitHubActions”](#githubactions)
Extracted from the GitHub Actions OIDC token claims:
| Key | Description |
| ------------------------------------ | ------------------------------------------------- |
| `githubactions:repository:full_name` | `org/repo`. |
| `githubactions:repository:owner` | GitHub org or user. |
| `githubactions:workflow` | Workflow name. |
| `githubactions:run:id` | Workflow run ID. |
| `githubactions:actor` | User that triggered the run. |
| `githubactions:ref` | Git ref (e.g. `refs/heads/main`). |
| `githubactions:environment` | Deployment environment, if the job targets one. |
| `githubactions:event:name` | Triggering event (e.g. `push`, `pull_request`). |
| `githubactions:runner:environment` | `github-hosted` or `self-hosted`. |
| `githubactions:sha` | Commit SHA. |
| `githubactions:job:workflow_ref` | Reusable workflow ref, if the job comes from one. |
| `githubactions:token:issuer` | Token `iss` claim. |
| `githubactions:token:subject` | Token `sub` claim. |
| `githubactions:token:id` | Token `jti` claim. |
### K8sSAT
[Section titled “K8sSAT”](#k8ssat)
Extracted from the Kubernetes Service Account Token claims:
| Key | Description |
| ----------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `k8ssat:namespace` | Pod namespace. |
| `k8ssat:node:name` | Node name. |
| `k8ssat:node:uid` | Node UID. |
| `k8ssat:pod:name` | Pod name. |
| `k8ssat:pod:uid` | Pod UID. |
| `k8ssat:sa:name` | Service account name. |
| `k8ssat:sa:uid` | Service account UID. |
| `k8ssat:token:audience` | Token `aud` claim. |
| `k8ssat:token:issuer` | Token `iss` claim. |
| `k8ssat:token:id` | Token `jti` claim. |
| `k8ssat:token:subject` | Token `sub` claim. |
| `k8ssat:cluster:id` | The `clusterID` configured on the matching Verifier. Added by the control plane rather than derived from the token, so every daemon attesting through a given K8sSAT verifier carries the same cluster identifier. |
#### Getting the cluster’s JWKS
[Section titled “Getting the cluster’s JWKS”](#getting-the-clusters-jwks)
The K8sSAT verifier validates the token’s signature against the issuing cluster’s JWKS, configured via `jwksSource` as either an inline JWKS document or a `remote.url` the control plane fetches it from. Every Kubernetes API server with a service account issuer configured, which is the default on managed offerings, publishes an OIDC discovery document at `/.well-known/openid-configuration` containing a `jwks_uri` field; that URI is what you point `jwksSource.remote.url` at (or fetch once and paste into `jwksSource.inline`, for a cluster the control plane can’t reach directly).
* **EKS**: The cluster has a public OIDC issuer URL (`aws eks describe-cluster --name --query "cluster.identity.oidc.issuer"`); its JWKS is publicly reachable without cluster credentials. See the [EKS OIDC provider docs](https://docs.aws.amazon.com/eks/latest/userguide/enable-iam-roles-for-service-accounts.html).
* **GKE**: Run `kubectl get --raw /.well-known/openid-configuration` against the cluster and read the `jwks_uri` field from the response. See the [GKE workload identity docs](https://cloud.google.com/kubernetes-engine/docs/how-to/workload-identity).
* **AKS**: Requires the OIDC issuer feature enabled on the cluster (`az aks update --enable-oidc-issuer`); the issuer URL is then available via `az aks show --query "oidcIssuerProfile.issuerUrl"`. See the [AKS OIDC issuer docs](https://learn.microsoft.com/en-us/azure/aks/use-oidc-issuer).
For a self-managed or on-premises cluster, the same `/.well-known/openid-configuration` lookup works as long as `--service-account-issuer` is configured on the API server.
### JWT
[Section titled “JWT”](#jwt)
The generic JWT verifier maps token claims to metadata using its `metadataMap` field. Without any additional mapping, it produces:
| Key | Description |
| -------------- | ------------------ |
| `jwt:audience` | Token `aud` claim. |
| `jwt:issuer` | Token `iss` claim. |
| `jwt:id` | Token `jti` claim. |
| `jwt:subject` | Token `sub` claim. |
Add entries to `metadataMap` to expose custom claims under additional `jwt:` keys.
### X509CertPOP
[Section titled “X509CertPOP”](#x509certpop)
Extracted from the presented X.509 certificate:
| Key | Description |
| -------------------------------------- | ----------------------------------------------- |
| `x509certpop:subject:commonName` | Certificate subject CN. |
| `x509certpop:subject:organization` | Certificate subject O (multi-valued). |
| `x509certpop:subject:organizationUnit` | Certificate subject OU (multi-valued). |
| `x509certpop:subject:country` | Certificate subject C (multi-valued). |
| `x509certpop:serial` | Certificate serial number (hex). |
| `x509certpop:issuer` | Certificate issuer DN. |
| `x509certpop:dns` | Certificate SAN DNS names (multi-valued). |
| `x509certpop:email` | Certificate SAN email addresses (multi-valued). |
| `x509certpop:uri` | Certificate SAN URIs (multi-valued). |
| `x509certpop:ip` | Certificate SAN IP addresses (multi-valued). |
### SSHCertPOP
[Section titled “SSHCertPOP”](#sshcertpop)
Extracted from the presented SSH certificate:
| Key | Description |
| ---------------------- | --------------------------------------------------- |
| `sshcertpop:hash` | SHA-256 hash of the certificate. |
| `sshcertpop:principal` | Valid principals on the certificate (multi-valued). |
## Example: JoinToken Verifier
[Section titled “Example: JoinToken Verifier”](#example-jointoken-verifier)
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: dev-jointoken
namespace: riptides-system
spec:
joinToken: {}
---
apiVersion: auth.riptides.io/v1alpha1
kind: JoinToken
metadata:
name: daemon-token-001
namespace: riptides-system
spec:
token: ""
```
## Example: AWS Instance Identity Document
[Section titled “Example: AWS Instance Identity Document”](#example-aws-instance-identity-document)
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: aws-verifier
namespace: riptides-system
spec:
AWSIID: {}
requiredMetadata:
- awsiid:account:id: ""
awsiid:region: "us-east-1"
```
This verifier accepts daemons running on EC2 instances in the specified account and region. The daemon automatically retrieves the instance identity document from the EC2 metadata service and presents it during attestation.
# Services
A Service in Riptides represents a network endpoint that workloads connect to. Services define the destinations in your infrastructure: both internal services secured by Riptides and external APIs that workloads need to reach.
## What Services Represent
[Section titled “What Services Represent”](#what-services-represent)
Services are the “other side” of a workload connection. When you define connection policies on a WorkloadIdentity (egress rules), you reference services to specify which destinations a workload is allowed to reach. Services decouple connection policy from network addresses: you define intent (this workload connects to the payment API) rather than infrastructure details (this workload connects to 10.0.3.42:443).
## Internal vs External Services
[Section titled “Internal vs External Services”](#internal-vs-external-services)
### Internal Services
[Section titled “Internal Services”](#internal-services)
Internal services represent endpoints within your infrastructure that are also managed by Riptides. Connections between workloads and internal services can be secured with mutual TLS, with both sides presenting SPIFFE identities. Access control policies can restrict connections based on the SPIFFE IDs of the connecting workload.
An internal service might represent a database, a message broker, or another microservice running in the same or a different cluster.
### External Services
[Section titled “External Services”](#external-services)
External services represent endpoints outside your infrastructure or outside Riptides management. These include cloud provider APIs (such as AWS S3 or GCP Cloud Storage), third-party SaaS APIs, or legacy systems that do not participate in the SPIFFE trust domain.
For external services, Riptides can inject credentials into outbound connections, apply TLS policies, and enforce which workloads are allowed to connect.
## Service Definition
[Section titled “Service Definition”](#service-definition)
A Service resource specifies the endpoint address, port, protocol, and metadata used for policy matching:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: payment-api
namespace: riptides-system
spec:
addresses:
- address: payment-api.internal.example.com
port: 443
labels:
team: payments
tier: backend
```
### Addresses
[Section titled “Addresses”](#addresses)
The `addresses` field specifies how the service is reached. Each entry is an object with:
* **`address`**: A DNS hostname (`api.example.com`), IP address (`10.0.3.42`), FQDN, or wildcard FQDN (`*.example.com`).
* **`port`**: The port number the service listens on.
* **`aliases`**: Alternative hostnames that should be treated as the same service.
A service can have multiple address entries, for example when it is reachable on different ports or through different DNS names.
### Wildcard Addresses
[Section titled “Wildcard Addresses”](#wildcard-addresses)
A wildcard address like `*.s3.amazonaws.com` isn’t a single resolvable hostname, so the kernel can’t enforce access to it just by DNS lookup. For a wildcard address to be enforceable, the Service must also specify the actual network range it covers, using one of:
* **`networkPrefixes`**: Explicit CIDR ranges (e.g. `10.0.0.0/16`) that the wildcard resolves to.
* **`networkNames`**: Symbolic, provider-backed names (`aws`, `azure`, `google`, `google-cloud`, `github`, optionally narrowed to a specific service like `aws:s3`) that the daemon resolves to that provider’s published IP ranges at runtime, so the enforced range stays current as the provider adds or retires addresses. See the [Service reference](../../reference/service#known-network-names) for the full list.
A small set of well-known provider wildcards, such as `*.amazonaws.com` and `*.googleapis.com`, are recognized automatically and don’t require `networkPrefixes` or `networkNames` to be set. Any other wildcard address without one of these fields is rejected at admission time, since Riptides would otherwise have no way to know which network range the wildcard is meant to cover.
## Labels and Policy Matching
[Section titled “Labels and Policy Matching”](#labels-and-policy-matching)
Services use labels for categorization and policy matching. WorkloadIdentity egress rules reference services by label selectors rather than by name, enabling flexible grouping.
For example, a WorkloadIdentity might allow egress to all services labeled `tier: backend`:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: frontend
namespace: riptides-system
spec:
workloadID: myapp/frontend
selectors:
- k8s:label:app: frontend
egress:
- selectors:
- tier: backend
connection:
tls:
mode: MUTUAL
```
This approach means you can add new backend services without updating every workload policy that needs access to them. Apply the `tier: backend` label to the new service, and existing policies automatically include it.
## Examples
[Section titled “Examples”](#examples)
### External Cloud API
[Section titled “External Cloud API”](#external-cloud-api)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: aws-s3
namespace: riptides-system
spec:
addresses:
- address: s3.us-east-1.amazonaws.com
port: 443
external: true
labels:
provider: aws
type: storage
```
### Internal Database
[Section titled “Internal Database”](#internal-database)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: orders-db
namespace: riptides-system
spec:
addresses:
- address: orders-db.internal.example.com
port: 5432
labels:
tier: backend
type: database
```
### Wildcard Address
[Section titled “Wildcard Address”](#wildcard-address)
`*.s3.amazonaws.com` is not one of the automatically recognized provider wildcards, so this Service must supply the network range it covers explicitly:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: aws-s3-buckets
namespace: riptides-system
spec:
addresses:
- address: "*.s3.amazonaws.com"
port: 443
networkNames:
- aws:s3
external: true
labels:
provider: aws
type: storage
```
# Workload Attestation
Workload attestation is the process of proving a process’s identity to the kernel module before it can use a workload identity. It’s the same concept as [SPIFFE workload attestation](https://spiffe.io/): rather than trusting a workload because of where it runs (an IP, a hostname, a network zone), attestation looks at what the workload actually *is* and derives its identity from that.
It happens after [node attestation](../node-attestation) has already established trust between the daemon and the control plane: node attestation identifies the machine, workload attestation identifies the individual processes running on it.
## How It Works
[Section titled “How It Works”](#how-it-works)
Workload attestation happens at connection time, entirely on the node, with no round-trip to the control plane. When a process opens a new network connection, the daemon collects metadata about the process and its environment, then evaluates it against the selectors defined in WorkloadIdentity resources. A process receives an identity if it satisfies the selectors for that WorkloadIdentity.
This evaluation is not a one-time check. Every new connection triggers selector evaluation, so a process that previously matched but has since changed (for example, a different binary was exec’d into the same PID) will not pass attestation.
Selectors follow the same matching rules as a Verifier’s `requiredMetadata` (see [Node Attestation](../node-attestation)): a WorkloadIdentity’s `selectors` field is a list of key-value groups, and a process matches if it satisfies **all** keys within **any one** group (AND within a group, OR across groups). A key within a group can also list multiple values; the process matches that key if it has any one of them:
```yaml
selectors:
- process:name: nginx
k8s:pod:namespace: [production, staging]
- process:name: nginx
docker:label:env: production
```
This matches an `nginx` process in either the `production` or `staging` Kubernetes namespace, or an `nginx` process running in a Docker container labeled `env: production` outside Kubernetes entirely.
## Examples
[Section titled “Examples”](#examples)
### Kubernetes web frontend
[Section titled “Kubernetes web frontend”](#kubernetes-web-frontend)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: nginx-web
namespace: riptides-system
spec:
workloadID: my-app/web/nginx
selectors:
- process:name: nginx
k8s:pod:namespace: my-app
k8s:label:app: nginx
connection:
tls:
mode: PERMISSIVE
```
This issues an identity to any process named `nginx`, running in a pod labeled `app: nginx` within the `my-app` Kubernetes namespace.
### AWS EC2 instance without Kubernetes
[Section titled “AWS EC2 instance without Kubernetes”](#aws-ec2-instance-without-kubernetes)
A batch worker running directly on an EC2 instance, with no Kubernetes or Docker involved:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: batch-worker
namespace: riptides-system
spec:
workloadID: myapp/batch-worker
selectors:
- process:name: batch-worker
ec2:placement:region: us-east-1
connection:
tls:
mode: MUTUAL
```
`ec2:placement:region` alone would match every process on every instance in that region, so it’s combined with the process-scoped `process:name` selector to scope the identity to just the intended workload rather than the whole host.
### Same service, Kubernetes or plain Docker
[Section titled “Same service, Kubernetes or plain Docker”](#same-service-kubernetes-or-plain-docker)
A service that’s mid-migration from plain Docker hosts to Kubernetes, or that simply runs on both, can keep a single WorkloadIdentity by giving it one selector group per environment:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: nginx-web
namespace: riptides-system
spec:
workloadID: my-app/web/nginx
selectors:
- process:name: nginx
k8s:pod:namespace: [production, staging]
- process:name: nginx
docker:label:env: production
connection:
tls:
mode: PERMISSIVE
```
This issues the same `spiffe://example.com/my-app/web/nginx` identity to an `nginx` process whether it’s running in the `production`/`staging` Kubernetes namespaces or in a plain Docker container labeled `env: production`, so the identity, TLS policy, and any egress/credential bindings built on top of it don’t need to be duplicated per environment.
## Metadata Collectors
[Section titled “Metadata Collectors”](#metadata-collectors)
The daemon runs a set of collectors that gather metadata about a process and its host. Each collector namespaces its output under a prefix (`process:`, `k8s:`, `docker:`, `ec2:`, `gcp:`, `azure:`, `linuxos:`, `node:`, `sysfsdmi:`), which is what you reference in a selector key.
Collectors fall into two categories:
* **Process-scoped**: produce different metadata per process on the same host: `process` (from `/proc`), `kubernetes` (pod/container context, via the kubelet API), and `docker` (container context, via the Docker socket). These require resolving the PID to a pod or container, and are unavailable (and silently skipped) for processes that aren’t running in a pod or container.
* **Host-scoped**: produce the same metadata for every process on a given host: `ec2`, `gcp`, `azure`, `linuxos`, `node`, `sysfsdmi`. Each cloud collector auto-detects whether the host is actually running there (e.g. `azure` checks `/sys/class/dmi/id/sys_vendor`) and produces no labels otherwise.
Because host-scoped collectors don’t distinguish between processes, a selector built only from host-scoped keys (e.g. just `ec2:placement:region`) matches every process on that host. Combine a host-scoped selector with a process-scoped one (e.g. `process:name`) to scope a WorkloadIdentity to a specific workload rather than the whole node.
The `kubernetes` and `docker` collectors are enabled by default but no-op safely when their dependency is absent (no kubelet reachable, no Docker socket); they don’t fail attestation for non-containerized processes.
## Metadata by Collector
[Section titled “Metadata by Collector”](#metadata-by-collector)
### process
[Section titled “process”](#process)
Collected from `/proc/` for the connecting process.
| Key | Description |
| --------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------ |
| `process:pid` | Process ID. |
| `process:name` | Executable name. |
| `process:cmdline` | Full command line. |
| `process:uid` / `process:uid:effective` | Effective UID. |
| `process:uid:real` | Real UID. |
| `process:gid` / `process:gid:effective` | Effective GID. |
| `process:gid:real` | Real GID. |
| `process:gid:additional` | Supplementary group IDs (multi-valued). |
| `process:binary:path` | Path to the executable (`/proc//exe`). |
| `process:binary:hash` | SHA-256 digest of the executable, cached by mount-namespace + device/inode. |
| `process:network:binding` | `ip:port` for each socket the process holds in `LISTEN` state (multi-valued). |
| `process:env:` | Environment variable, keyed by uppercased name. Only collected if the daemon’s `extractEnvs` option is enabled (default: off). |
On the *degraded* attestation path (when the process has already exited or its PID was reused by the time the daemon re-derives its identity for evaluation), only `process:pid`, `process:name`, `process:binary:path`, `process:uid*`, and `process:gid*` (not `:additional`) are available, reconstructed from the connection-time snapshot rather than a live `/proc` read. `process:cmdline`, `process:binary:hash`, `process:gid:additional`, `process:env:*`, and all `k8s:*`/`docker:*` labels are unavailable on this path.
### kubernetes (`k8s`)
[Section titled “kubernetes (k8s)”](#kubernetes-k8s)
Collected by resolving the process’s cgroup to a pod/container ID, then querying the kubelet (or API server) for that pod’s spec and status.
| Key | Description |
| ------------------------------------------------- | ----------------------------------------------------------- |
| `k8s:pod:name` | Pod name. |
| `k8s:pod:namespace` | Pod namespace. |
| `k8s:pod:serviceaccount` | Pod’s service account name. |
| `k8s:pod:owner:kind` | Owning controller kind (e.g. `replicaset`), lowercased. |
| `k8s:pod:owner:kind-with-version` | Owning controller’s `apiVersion/kind`, lowercased. |
| `k8s:pod:owner:name` | Owning controller’s name. |
| `k8s:node:name` | Name of the node the pod is scheduled on. |
| `k8s:container:name` | Name of the container within the pod. |
| `k8s:container:image:id` | Image ID of that container. |
| `k8s:label:` | Value of pod label ``. |
| `k8s:annotation:` | Value of pod annotation ``. |
| `k8s:pod:image:name` / `k8s:pod:image:id` | Image name/ID for each container in the pod (multi-valued). |
| `k8s:pod:image:count` | Number of containers in the pod. |
| `k8s:pod:init-image:name` / `:id` / `:count` | Same, for init containers. |
| `k8s:pod:ephemeral-image:name` / `:id` / `:count` | Same, for ephemeral containers. |
### docker
[Section titled “docker”](#docker)
Collected by resolving the process’s cgroup to a container ID, then inspecting that container via the Docker API.
| Key | Description |
| ------------------------- | --------------------------------------------------------- |
| `docker:id` | Container ID. |
| `docker:name` | Container name. |
| `docker:cmdline` | Container entrypoint plus arguments. |
| `docker:label:` | Container label. |
| `docker:env:` | Container environment variable, keyed by uppercased name. |
| `docker:image:name` | Image name/tag the container was created from. |
| `docker:image:hash` | Image ID/digest. |
| `docker:network:mode` | Container network mode. |
| `docker:network:hostname` | Container hostname. |
| `docker:port-binding` | Each published port binding (multi-valued). |
### ec2
[Section titled “ec2”](#ec2)
Host-level metadata from the EC2 Instance Metadata Service (IMDS). Distinct from the `awsiid:*` metadata produced during [node attestation](../node-attestation): this collector reads IMDS directly rather than parsing the signed identity document, and runs on every workload evaluation, not just once at daemon startup.
| Key | Description |
| -------------------------------------------------------------------------- | --------------------------------------------------- |
| `ec2:security-groups` | Security groups attached to the instance. |
| `ec2:instance:id` / `:type` | Instance ID and type. |
| `ec2:ami:id` | AMI ID. |
| `ec2:kernel:id` | Kernel ID, if set. |
| `ec2:network:hostname` / `:local-hostname` / `:public-hostname` | Hostnames. |
| `ec2:network:local-ipv4` / `:public-ipv4` / `:local-ipv6` / `:public-ipv6` | IP addresses. |
| `ec2:network:mac` | Primary network interface MAC address. |
| `ec2:placement:availability-zone` / `:availability-zone-id` | AZ. |
| `ec2:placement:region` | Region. |
| `ec2:placement:group-name` / `:host-id` / `:partition-number` | Placement group details. |
| `ec2:services:domain` / `:partition` | AWS partition/domain (e.g. `aws`, `amazonaws.com`). |
### gcp
[Section titled “gcp”](#gcp)
Host-level metadata from the GCP metadata server.
| Key | Description |
| --------------------------------------------------------------------------------------- | ---------------------------------------------------- |
| `gcp:instance:id` / `:name` | Instance ID and name. |
| `gcp:instance:cpu-platform` | CPU platform. |
| `gcp:instance:attribute:` | Instance metadata attribute (excludes `ssh-keys`). |
| `gcp:instance:tag` | Network tag (multi-valued). |
| `gcp:instance:image:project` / `:name` | Source image. |
| `gcp:instance:machine:project` / `:type` | Machine type. |
| `gcp:instance:placement:project` / `:zone` / `:region` | Zone and region. |
| `gcp:instance:scheduling:automatic-restart` / `:onHostMaintenance` / `:preemptible` | Scheduling options. |
| `gcp:instance:network:mac` | NIC MAC address (multi-valued). |
| `gcp:instance:network:private-ipv4` / `:public-ipv4` / `:private-ipv6` / `:public-ipv6` | IP addresses (multi-valued). |
| `gcp:instance:serviceaccount::email` | Attached service account email. |
| `gcp:instance:serviceaccount::alias` / `:scope` | Service account aliases/OAuth scopes (multi-valued). |
| `gcp:project:id` / `:id:numeric` | Project ID and numeric ID. |
| `gcp:project:attribute:` | Project-level metadata attribute. |
### azure
[Section titled “azure”](#azure)
Host-level metadata from the Azure Instance Metadata Service. Distinct from the `azureimds:*` metadata produced during [node attestation](../node-attestation): this collector reads the IMDS instance endpoint directly rather than the signed managed-identity token.
| Key | Description |
| -------------------------------------------------------------------------------- | ----------------------------------------------------------------------------------- |
| `azure:name` | VM name. |
| `azure:ostype` | `Linux` or `Windows`. |
| `azure:priority` | VM priority (e.g. `Spot`, `Regular`). |
| `azure:provider` / `:sku` | Compute provider and SKU. |
| `azure:resourcegroup:name` | Resource group. |
| `azure:subscription:id` | Subscription ID. |
| `azure:placement:location` / `:zone` / `:groupid` | Region, zone, placement group. |
| `azure:vm:size` / `:id` / `:publisher` / `:offer` / `:version` | VM image/size details. |
| `azure:vm:scaleset:name` | VMSS name, if the VM is part of one. |
| `azure:tag:` | Azure resource tag. |
| `azure:network:mac` | NIC MAC address (multi-valued). |
| `azure:network:private-ipv4` / `:public-ipv4` / `:private-ipv6` / `:public-ipv6` | IP addresses (multi-valued, includes load balancer frontend IPs for `public-ipv4`). |
### linuxos
[Section titled “linuxos”](#linuxos)
Host OS metadata from local system files (e.g. `/etc/os-release`).
| Key | Description |
| ------------------------ | ---------------------------------------- |
| `linuxos:name` | Linux distribution name (e.g. `ubuntu`). |
| `linuxos:version` | Distribution version. |
| `linuxos:kernel:release` | Kernel name-release string. |
| `linuxos:kernel:version` | Kernel version string. |
### node
[Section titled “node”](#node)
General host metadata (distribution, virtualization, network interfaces) collected locally, independent of the OS-specific `linuxos` collector.
| Key | Description |
| --------------------------------------------------------------- | ----------------------------------------------------------------------------------- |
| `node:hostname` | Hostname (`MDX_NODE_HOSTNAME` env var, else `/etc/hostname`, else system hostname). |
| `node:uuid` | Host ID. |
| `node:os:type` / `:version` | OS type and platform version. |
| `node:platform:name` / `:family` / `:version` | Platform details (e.g. `ubuntu` / `debian` / `22.04`). |
| `node:virtualization:type` / `:role` | Virtualization technology and role (host/guest). |
| `node:kernel:version` / `:arch` | Kernel version and architecture. |
| `node:network:interface:count` | Number of network interfaces. |
| `node:network:interface:name` | Interface name (multi-valued). |
| `node:network:interface::mac_address` / `:mtu` / `:index` | Per-interface details. |
| `node:network:interface::ip` | Every IP address on that interface (multi-valued). |
### sysfsdmi
[Section titled “sysfsdmi”](#sysfsdmi)
Hardware/firmware metadata from `/sys/class/dmi/id`.
| Key | Description |
| --------------------------------------------------------------------------- | --------------------------------- |
| `sysfsdmi:bios:date` / `:release` / `:vendor` / `:version` | BIOS details. |
| `sysfsdmi:chassis:type` / `:vendor` / `:version` / `:serial` / `:asset-tag` | Chassis details. |
| `sysfsdmi:product:name` / `:family` / `:version` / `:serial` / `:sku` | Product (hardware model) details. |
# Workload Identity
A workload identity is the core primitive in Riptides. It binds a cryptographic identity (a SPIFFE ID backed by an X.509 certificate or JWT token) to a specific workload running on a node. The kernel module uses this binding to authenticate workloads on every connection, transparently and without application changes.
A WorkloadIdentity resource brings together everything that identity needs: how it’s matched to a running process, which node or fleet it’s scoped to, which peers it may talk to, and how its connections are secured. This page covers each of those in turn; for the exhaustive field-by-field spec, see the [WorkloadIdentity reference](../../reference/workloadidentity).
## SPIFFE IDs
[Section titled “SPIFFE IDs”](#spiffe-ids)
Every workload identity maps to a SPIFFE ID, a URI-formatted identifier within a trust domain:
```plaintext
spiffe://example.com/frontend
spiffe://example.com/payment-service
```
SPIFFE IDs are not tied to network addresses or hostnames. They represent the workload itself, regardless of where it runs. This matters in practice because IP addresses and hostnames get reassigned constantly: a redeploy, an autoscaling event, or a rescheduled pod can hand yesterday’s address to a completely different workload today. Policy written against an address is only as accurate as the last time someone confirmed it still points at the intended workload; policy written against a SPIFFE ID keeps meaning the same thing regardless of how many times the infrastructure underneath it changes.
## SVIDs
[Section titled “SVIDs”](#svids)
Workloads prove their identity using SVIDs (SPIFFE Verifiable Identity Documents). Riptides supports two SVID types:
* **X.509 SVIDs**: Certificates used for mutual TLS. The SPIFFE ID is encoded in the certificate’s Subject Alternative Name (SAN) URI field. These are the primary identity credential for service-to-service communication.
* **JWT SVIDs**: Signed tokens used for federation with external systems. The SPIFFE ID appears in the `sub` claim. These are typically used when exchanging workload identity for cloud provider credentials via OIDC.
Both types are issued automatically by the platform and rotated before expiration without workload restarts. The two exist side by side because they answer to different kinds of peers: a TLS-speaking service expects a certificate at the handshake, while a cloud IAM API or OIDC-federated system expects a signed bearer token it can exchange for credentials. Having both tied to the same underlying identity means a workload can authenticate over mTLS to internal services and separately present its identity to an external system, without maintaining two unrelated credentials for what is really one identity.
## How Workloads Are Identified
[Section titled “How Workloads Are Identified”](#how-workloads-are-identified)
Workload identification is performed by the daemon. When a process opens a new network connection, the daemon evaluates the connecting process against **selectors** defined in the WorkloadIdentity resource, using metadata collected from the process and its environment (Kubernetes pod labels, process names, cloud instance metadata, and more). A process must satisfy all selectors in at least one selector group to receive that identity.
Because processes restart, get rescheduled onto different nodes, and scale up and down continuously, this match is not a one-time assignment made when the WorkloadIdentity is created; it is re-evaluated on every new connection. The WorkloadIdentity is declared once, and the daemon assigns it to whichever process currently fits the description, wherever that process happens to be running right now.
See [Workload Attestation](../workload-attestation) for the complete selector matching rules and the full list of metadata keys available from every collector.
### Quick example
[Section titled “Quick example”](#quick-example)
A Next.js frontend running in Kubernetes might be identified by combining two selectors:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: frontend
namespace: riptides-system
spec:
workloadID: frontend
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: frontend
process:cmdline: node server.js
```
Only a process whose command line matches `node server.js`, running inside a pod with the label `app=frontend`, will receive the `spiffe://example.com/frontend` identity.
## Identity Lifecycle
[Section titled “Identity Lifecycle”](#identity-lifecycle)
Certificates are short-lived by default, and their entire lifecycle, issuance, rotation, and revocation, happens without the application ever handling a private key, a certificate file, or a restart. The kernel module itself drives this: it keeps a cache of keys and certificates and, on every new connection, decides on the spot whether what it’s holding is still good or needs to be requested fresh, going to the daemon and control plane only when it actually needs something from them. That removes the two places certificate lifecycle management usually breaks down in practice: an app team hand-rolling its own refresh logic, or a certificate quietly expiring because nobody wired up rotation for a workload that predates its current owner.
### Issuance
[Section titled “Issuance”](#issuance)
When a new connection needs an identity the kernel module doesn’t already have cached, it generates a private key in kernel memory and sends a certificate signing request (CSR) to the daemon, which forwards it to the control plane. The resulting X.509 SVID is loaded back into the kernel module and cached for reuse.
### Rotation
[Section titled “Rotation”](#rotation)
On each new connection, the kernel module checks the cached certificate’s remaining lifetime and, if it’s due to expire soon, requests a fresh one the same way, in the background. Existing connections keep using their already-negotiated session and are unaffected; no workload restart is required.
### Revocation
[Section titled “Revocation”](#revocation)
There’s no separate revoke step to run. The cache is finite, so entries for workloads that no longer match a WorkloadIdentity’s selectors, or that simply haven’t been needed in a while, age out on their own. Once a cached identity is gone, the next connection for it starts over at issuance rather than presenting something stale.
## Scope
[Section titled “Scope”](#scope)
Every WorkloadIdentity is scoped to exactly one of the following:
* **Daemon scope**: The identity applies to workloads on a single, named node. This is the default when a daemon operates independently.
* **DaemonGroup scope**: The identity applies to every daemon in a group, so a service that runs many replicas across a fleet needs only one WorkloadIdentity definition rather than one per node.
```yaml
spec:
scope:
daemon:
id: riptides/daemon/my-first-node
# or
spec:
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
```
Scope decides which daemon or daemons the control plane distributes this policy to at all, before selector matching ever runs locally on a given node. `DaemonGroup` scope is what lets one definition follow a horizontally-scaled service across however many nodes it’s currently running on, without being redeclared each time a node joins or leaves the fleet; `Daemon` scope is the right fit when a workload is genuinely pinned to one specific machine.
## Access Control
[Section titled “Access Control”](#access-control)
`allowedSPIFFEIDs` restricts which peers a workload is allowed to talk to. It has two directions:
* **`inbound`**: SPIFFE IDs allowed to connect *to* this workload.
* **`outbound`**: SPIFFE IDs this workload is allowed to connect *to*.
```yaml
spec:
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/myapp/frontend
outbound:
- spiffe://example.com/myapp/orders-db
```
If `allowedSPIFFEIDs` is omitted entirely, any workload in the trust domain that satisfies the connection’s TLS mode requirement can connect, in either direction. TLS mode alone only proves a peer holds a valid, cryptographically verifiable identity somewhere in the trust domain; it says nothing about whether that specific peer should be talking to this workload. `allowedSPIFFEIDs` is where that second check happens, keeping “is this identity valid” separate from “is this exact identity allowed here” so you can tighten access per workload, per destination, or per port without changing how identity itself is proven. See [Connection Security](../connections) for how TLS mode (`MUTUAL`, `SIMPLE`, `PERMISSIVE`) and `allowedSPIFFEIDs` interact at the handshake, and for restricting unauthenticated access to specific HTTP paths with `httpRequestPath`.
The top-level `allowedSPIFFEIDs` is a default. `egress[].allowedSPIFFEIDs` and `ingress[].allowedSPIFFEIDs` **replace** it (they don’t add to it) for that specific egress rule or ingress port, letting you set a permissive default and lock down individual destinations or ports, or vice versa.
## Egress Filtering
[Section titled “Egress Filtering”](#egress-filtering)
Egress rules control outbound connections. Each rule targets one or more [Services](../services) by label selector rather than by naming individual Service resources, and can override the default connection policy, allowed SPIFFE IDs, SVID settings, and workload ID for traffic to those services:
```yaml
spec:
egress:
- selectors:
- tier: backend
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/orders-service
- spiffe://example.com/inventory-service
```
This allows the workload to reach any Service labeled `tier: backend`, over mutual TLS, but only if the remote side presents one of the two listed SPIFFE IDs. Because matching is by label rather than by naming each Service resource individually, this egress rule doesn’t need to change every time a new Service is added to the group it already trusts: label the new Service `tier: backend` and it’s covered without touching this WorkloadIdentity.
A workload with no matching egress rule for a given destination connects using the top-level `connection` and `allowedSPIFFEIDs` settings.
## Ingress Filtering
[Section titled “Ingress Filtering”](#ingress-filtering)
Ingress rules control inbound connections, per listening port:
```yaml
spec:
ingress:
- port: 8443
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/myapp/frontend
- spiffe://example.com/monitoring
- port: 8080
connection:
protocol: HTTP1
tls:
mode: PERMISSIVE
httpRequestPath:
- /healthz
```
Here, port `8443` requires mutual TLS from one of two callers, while port `8080` accepts plaintext but only forwards unauthenticated requests to `/healthz`; every other path on that port still requires a verified identity. Not every port on a workload needs the same trust requirement: a health-check port has to accept probes from a kubelet or load balancer that carries no workload identity at all, while an application port handling real traffic should require mutual TLS. Per-port rules let both live on the same workload without weakening the strict port, or standing up a separate proxy just to translate unauthenticated probe traffic into something that port would otherwise accept. See [Connection Security](../connections#ingress-and-egress-policies) for the full `httpRequestPath` semantics.
A port with no matching ingress rule falls back to the top-level `connection` and `allowedSPIFFEIDs` settings.
## Examples
[Section titled “Examples”](#examples)
### Restricting inbound callers
[Section titled “Restricting inbound callers”](#restricting-inbound-callers)
A payment service that only accepts connections from two specific workloads, rejecting everything else at the TLS handshake:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: payment-service
namespace: riptides-system
spec:
workloadID: myapp/payment-service
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: payment-service
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/myapp/checkout
- spiffe://example.com/myapp/billing
```
### Per-service egress overrides
[Section titled “Per-service egress overrides”](#per-service-egress-overrides)
A workload that reaches internal services over mutual TLS by default, but connects to one specific external analytics endpoint over simple TLS instead:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: checkout
namespace: riptides-system
spec:
workloadID: myapp/checkout
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: checkout
connection:
tls:
mode: MUTUAL
egress:
- selectors:
- tier: backend
connection:
tls:
mode: MUTUAL
- selectors:
- service: external-analytics
connection:
tls:
mode: SIMPLE
```
### Health probes alongside a strict application port
[Section titled “Health probes alongside a strict application port”](#health-probes-alongside-a-strict-application-port)
An API server that requires mutual TLS on its application port but lets an unauthenticated kubelet probe reach `/healthz` on a separate port:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: api-server
namespace: riptides-system
spec:
workloadID: myapp/api-server
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: api-server
connection:
tls:
mode: MUTUAL
ingress:
- port: 8080
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/myapp/frontend
- port: 9000
connection:
protocol: HTTP1
tls:
mode: PERMISSIVE
httpRequestPath:
- /healthz
- /readyz
```
# Access Control
The **Access Control** screen shows, per workload identity, which other identities it is allowed to connect to and from over mTLS. It is an allowlist of service-to-service connections.
Open it from **Configure → Access Control** in the sidebar (`/ui/access-control`).
Note
This screen governs connections between your workloads. To restrict which **models and tools** an AI agent may use, see the separate [Access Control](../../agentic/access-control) screen under **Agentic**.
## What you see
[Section titled “What you see”](#what-you-see)
A read-only overview table with these columns:
* **Workload ID**: the workload identity.
* **Allowed Inbound Workload IDs**: the identities allowed to connect **to** it.
* **Allowed Outbound Workload IDs**: the identities it is allowed to connect **out to**.
When a direction has no entries, the row shows **All connections allowed** for it. Search by workload ID.
The rule is an **allowlist**: an empty list in a direction means all connections are allowed that way, and listing identities restricts it to exactly those. So a workload is unrestricted until you add entries.
## Changing the rules
[Section titled “Changing the rules”](#changing-the-rules)
This screen is an overview. To change what an identity allows, click its **Workload ID** to open the identity, choose **Edit**, and use the **Access Policy** tab to set the allowed **Inbound** and **Outbound** identities. Finer, per-destination or per-port rules live on that identity’s **Egress** and **Ingress** rules. See [Identities](../identities) for the full form.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Connection Security](../../concepts/connections): how mTLS is established between workloads.
* [Implicit mTLS](../../concepts/mtls-without-services): when connections are secured without an explicit rule.
* [Identities](../identities): where these allowlists are edited.
# Connections
The **Connections** screen shows the network connections Riptides observes between workloads, and whether each is encrypted. It answers who is talking to whom, and over TLS or in the clear.
Open it from **Observe → Connections** in the sidebar (`/ui/connection-inventory`). Two tabs split the view: **Outbound Connections** (the default) and **Inbound Connections**.
## Overview
[Section titled “Overview”](#overview)
A collapsible **Overview** panel at the top summarizes the traffic:
* **% of connections with identity**: how much of your traffic is between identified workloads.
* **% of TLS connections**: how much is encrypted.
* **Number of connections**: a chart of TLS versus unencrypted connections over time.
## The table
[Section titled “The table”](#the-table)
Each row is one observed connection. On the **Outbound** tab the columns are **Active**, **Source Workload**, **Source Identity**, **Source Node**, **Encryption**, **Destination**, **Destination Port**, and **Destination Identity**. The **Inbound** tab mirrors this from the destination’s side.
Search by workload ID, and filter by **Active**, **Provider**, **Node**, **Encryption** (Unencrypted or TLS), and **Riptides Managed**. A **Show System Processes** toggle is off by default.
## Opening a connection
[Section titled “Opening a connection”](#opening-a-connection)
Click a row to see the detail:
* A **Source to Destination** diagram, each end showing the workload, identity, node, IP, and organization, with the encryption between them.
* **Traffic Analysis**: the protocol, and for AI traffic the MCP version.
* **Telemetry**: throughput over time.
* **Neighboring** and **related connections** for the same workload.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Workloads](../workloads): the workloads behind these connections.
* [Connection Security](../../concepts/connections): how Riptides upgrades connections to mTLS.
# Credential Bindings
The **Credential Bindings** screen is where you connect a credential source to a workload and control how it is delivered. A binding says: this workload identity receives this credential, delivered by injection into its outbound requests, as a secure file, or both.
Open it from **Configure → Credential Bindings** in the sidebar (`/ui/credential-bindings`).
## What you see
[Section titled “What you see”](#what-you-see)
Two cards summarize injection status and the credential-type distribution. The table lists each binding with:
* **Status**: **Active** or **Inactive**.
* **Name**.
* **Workload Identity**: the workload that receives the credential.
* **Credential Name**: the credential source being delivered.
* **Services**: the services the binding targets.
* **Usage (1h)**: recent read and injection counts.
Search by workload identity. Each row’s **⋯** menu offers **Edit** and **Delete**.
## Create a binding
[Section titled “Create a binding”](#create-a-binding)
Choose **Create Binding** and fill in:
* **Name** (optional, auto-generated from the workload and credential).
* **Workload ID** (required): the workload that receives the credential.
* **Credential** (required): the credential source to deliver.
* **Human ID** (optional): scope the binding to a specific person.
* **Propagation** (at least one): **Secure File** delivers the credential as an identity-enforced file that only the matched workload can read; **Injection** adds the credential into matching outbound requests. With Injection on, you target services with selector groups, or pick a service to prefill them.
## Edit, delete, and detail
[Section titled “Edit, delete, and detail”](#edit-delete-and-detail)
Edit or delete a binding from its row **⋯** menu. Clicking a binding opens a detail panel showing its workload, credential, and propagation, plus tables for **HTTP Injections** (credentials added to outbound requests) and **Credential Files** (credentials delivered as secure files).
## Next steps
[Section titled “Next steps”](#next-steps)
* [Credentials](../../concepts/credentials): how credential delivery works.
* [Credentials](../credentials): register the source a binding delivers.
* [Services](../services): the destinations injection rules target.
# Credentials
The **Credentials** screen lists your credential sources: where Riptides obtains or stores the secrets and tokens it delivers to workloads. A **credential source** defines how a credential is produced (a static secret, a short-lived cloud token, an OAuth2 token, a Vault secret, and so on). A [Credential Binding](../credential-bindings) then delivers it to a workload.
Open it from **Configure → Credentials** in the sidebar (`/ui/credential-sources`).
## What you see
[Section titled “What you see”](#what-you-see)
Three cards summarize your credentials (source status, credentials by type, and bindings by credential type). The table lists each source with:
* **Status**: **Active** or **Inactive**.
* **Name**.
* **Type**: the kind of source (see below).
* **Assigned Identities**: the workload identities using it.
Search by name and filter by **Type**. Each row’s **⋯** menu offers **Edit** and **Delete** (Delete is blocked while bindings still use the source).
## Add a credential
[Section titled “Add a credential”](#add-a-credential)
Choose **Add Credential**, give it a **Name** and optional **Description**, then pick a **Type**. The form then shows only the fields for that type:
* **Riptides Static Secret**: a stored bearer token or API key. You provide its **Value**.
* **Riptides JWT SVID**: short-lived signed JWTs, for services that accept OIDC-style tokens. You set the **Audience** and optional lifetime and claims.
* **AWS / Google Cloud / Azure / OCI Token Exchange**: exchange the workload’s identity for temporary cloud credentials. You provide the role or provider details for that cloud.
* **OAuth2 Client Credentials** and **OAuth2 Authorization Code**: fetch tokens from any OAuth2 endpoint, using the client-credentials or authorization-code flow.
* **Vault / OpenBao**: fetch a secret from HashiCorp Vault or OpenBao, authenticating with the workload’s JWT.
## Edit, delete, and detail
[Section titled “Edit, delete, and detail”](#edit-delete-and-detail)
Edit or delete a source from its row **⋯** menu. Clicking a source opens a detail panel with its configuration and a **Credential Bindings** table showing the workloads currently bound to it.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Credentials](../../concepts/credentials): how credential delivery works.
* [Credential Bindings](../credential-bindings): deliver a credential to a workload.
* Task guides: [Vault Integration](../../guides/vault-integration), [Secretless AWS Access](../../guides/secretless-aws), [GitHub API Access](../../guides/github-access).
# Daemons
The **Daemons** screen is where you connect hosts to Riptides and manage how they authenticate. A daemon is the Riptides agent that runs on each host; once a host has one, the workloads on it can be given identities and brought under policy.
Open it from **System → Daemons** in the sidebar (`/ui/daemons`). The screen has four tabs: **Daemons**, **Daemon Groups**, **Authentication Methods**, and **Join Tokens**.
## Daemons tab
[Section titled “Daemons tab”](#daemons-tab)
Lists the hosts that have a connected daemon, with their status. This is also where you start connecting a new host, using the **Attach Daemon** button in the top right.
## Attach a daemon
[Section titled “Attach a daemon”](#attach-a-daemon)
1. Choose **Attach Daemon**.
2. Pick the tab that matches your host: **Linux**, **Lima**, **Kubernetes**, or **GitHub Actions**.
3. Under **Authentication method**, select a method you have enabled (see the next section). If none exist yet, the dialog links you to the **Authentication Methods** tab to set one up first.
4. If you chose Join Token, pick an existing token or choose **Create join token** to make one on the spot. On the **Kubernetes** tab, set the **Namespace** (the default `riptides-system` suits most installs).
5. Copy the generated command and run it on the host. It installs and connects the daemon for you.
The host then appears in the **Daemons** tab within a few seconds.
## Authentication Methods tab
[Section titled “Authentication Methods tab”](#authentication-methods-tab)
A daemon proves which host it is when it connects, using an **authentication method**. This tab shows a card per method: **Join Token**, **Kubernetes**, **JWT / OIDC**, **Amazon Web Services**, **Google Cloud**, **Microsoft Azure**, **SSH Certificate**, **X.509 Certificate**, and **GitHub Actions**.
Choose **Enable** on a card to turn it on and fill in its settings. **Join Token** is the simplest to start with (you give it a **Name**). On a cloud host you can instead enable **Amazon Web Services**, **Google Cloud**, or **Microsoft Azure** so hosts attest themselves with no token to manage.
## Join Tokens tab
[Section titled “Join Tokens tab”](#join-tokens-tab)
This tab appears once a Join Token authentication method exists. Choose **Create Join Token**, optionally set a **Workload ID** and an **Expires In (days)** value, and choose **Create**. Tokens can be deleted from their row (with a confirmation) but not edited.
## Daemon Groups tab
[Section titled “Daemon Groups tab”](#daemon-groups-tab)
If you run many hosts, group them so you can manage and target them together. Choose **Create Daemon Group**, give it a **Daemon Group ID** and an optional **Name**, add **Selectors** that match the hosts (key/value pairs, with OR groups for alternatives), and save. You can then scope a [workload identity](../identities) to the whole group instead of a single daemon.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Identities](../identities): give a workload on a connected host its identity.
* [Architecture](../../concepts/architecture): where the daemon sits in the platform.
# Identities
The **Identities** screen lists your workload identities and is where you create, edit, and delete them. A **workload identity** is how Riptides recognizes a workload, whether a service or an AI agent, and gives it a cryptographic identity it uses for mTLS, access control, and traffic inspection.
Open it from **Configure → Identities** in the sidebar (`/ui/workload-identities`).
For an **AI agent**, creating an identity with traffic inspection turned on is the one prerequisite for the [Agentic AI](../../agentic/overview) features: once the agent has an identity, its LLM calls and tool use appear in the [Activity Monitor](../../agentic/activity-monitor) and can be governed in [Access Control](../../agentic/access-control).
## What you see
[Section titled “What you see”](#what-you-see)
Each identity appears as a row with its workload ID. Clicking a row opens its detail (selectors, scope, access policy, connection settings, and any egress or ingress rules), and each row’s **⋯** menu offers **Edit** and **Delete**. Use **Create Identity** (top right) to add one.
## Create an identity
[Section titled “Create an identity”](#create-an-identity)
Choose **Create Identity** to open the **Create Workload Identity** dialog. It has two fields at the top and then a set of tabs.
* **Workload ID** (required): a short identifier for the workload, such as `claude` for an agent or `payments-api` for a service (or something structured like `my-org/agents/claude`). As you type, the dialog shows the full identity it will create (`spiffe://your-trust-domain/claude`).
* **Name** (optional): leave it blank and Riptides generates one from the Workload ID.
Then work through the tabs:
### Selectors (required)
[Section titled “Selectors (required)”](#selectors-required)
Tell Riptides which process this identity applies to. Add a selector such as key `process:name`, value `claude`. Suggestion chips offer common keys (`process:name`, `k8s:pod:namespace`, `docker:name`, and more). You can add several values, and add more than one selector group to match “this **or** that.”
### Scope (required)
[Section titled “Scope (required)”](#scope-required)
Choose where the identity applies: a single **Daemon** or a **Daemon Group**, then pick the specific one. Riptides only matches the workload on hosts within this scope.
### Connection Properties
[Section titled “Connection Properties”](#connection-properties)
Control how connections are secured. The default **TLS mode** of **Permissive** suits most workloads.
**For an AI agent, make sure TLS intercept is on** (it is on by default). This is the setting that lets Riptides decrypt and inspect the agent’s HTTP and HTTPS calls, which is what makes them appear in the [Activity Monitor](../../agentic/activity-monitor) and become governable. There is no separate “evaluate traffic” switch: standard web traffic is inspected automatically once interception is on.
### Access Policy, Egress, Ingress (optional)
[Section titled “Access Policy, Egress, Ingress (optional)”](#access-policy-egress-ingress-optional)
Most workloads need only the tabs above. **Access Policy** limits which identities may connect to or from this workload (see [Access Control](../access-control)). **Egress** and **Ingress** override connection behavior per destination or per port.
Choose **Create** when done. The workload appears in the **Identities** list.
## Edit or delete
[Section titled “Edit or delete”](#edit-or-delete)
Use the **⋯** menu on a row: **Edit** reopens the same form (the Workload ID is fixed once created), and **Delete** asks you to type the name to confirm.
## Manage as code (optional)
[Section titled “Manage as code (optional)”](#manage-as-code-optional)
If you prefer GitOps, the same identity can be applied as a `WorkloadIdentity` resource. For an agent, the key field is `connection.tls.intercept: true`:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: claude
namespace: riptides-system
spec:
workloadID: claude
selectors:
- process:name: claude
scope:
daemonGroup:
id: daemongroup/dev-eu-west-1/on-demand-workers
connection:
tls:
mode: PERMISSIVE
intercept: true
```
## Next steps
[Section titled “Next steps”](#next-steps)
* [Workload Identity](../../concepts/workload-identity): the concept behind this resource.
* [Access Control](../access-control): control which workloads may connect to each other.
* For an AI agent: [Monitor AI Activity](../../agentic/activity-monitor) and the [Guardrails for an AI Agent](../../examples/agentic-guardrails) walkthrough.
# Services
The **Services** screen lists the services your workloads talk to, internal and external, and is where you register and manage them. A **service** is a named destination (one or more addresses) that access rules and credential deliveries can target.
Open it from **Configure → Services** in the sidebar (`/ui/service-inventory`).
Note
AI providers (LLMs) and MCP servers are a special kind of service with their own screens under **Agentic**: see [LLMs](../../agentic/llms) and [Connectors](../../agentic/connectors). This screen is for ordinary services.
## What you see
[Section titled “What you see”](#what-you-see)
A table with one row per address, with these columns:
* **Status**: **Active** or **Inactive**.
* **Name**: the service name, with its `host:port` beneath.
* **Type**: **Internal** or **External**.
* **Dependencies**: the workload identities this service sends traffic to.
* **Consumers**: the workload identities that send traffic to it.
* **Labels**: the service’s labels.
Search by name, host, or type, and filter by **Status**, **Network**, and **Kind**. Each row’s **⋯** menu offers **Edit** and **Delete**.
## Create a service
[Section titled “Create a service”](#create-a-service)
Choose **Create Service** and fill in:
* **Display Name** (required), and **Name** (auto-generated from it on create).
* **Addresses** (one or more): each has an **Address** (a hostname, IP, or wildcard such as `*.example.com`), a **Port**, and optional **Hostname aliases**. For a wildcard address you also provide **IP Prefixes (CIDR)** and **Network Names** (suggestions include `aws`, `github:api`, `google`, `azure`).
* **Type**: **Internal** (inside the cluster) or **External** (outside it). External services have a **TLS enabled** toggle.
* **Service Labels**: key/value pairs used to match the service in access and credential-injection rules.
## Edit, delete, and detail
[Section titled “Edit, delete, and detail”](#edit-delete-and-detail)
Edit or delete a service from its row **⋯** menu. Clicking a service opens a detail panel with its addresses and labels, a telemetry chart, and two tables: **Consumers** (identities that send traffic to it) and **Dependencies** (identities it sends traffic to).
## Next steps
[Section titled “Next steps”](#next-steps)
* [Services](../../concepts/services): the concept behind this resource.
* [Access Control](../access-control): control which workloads may reach a service.
* [Credential Bindings](../credential-bindings): inject credentials into requests to a service.
# Settings
The **Settings** screen holds environment-level administrative actions for a Riptides-managed console.
Open it from **System → Settings** in the sidebar (`/ui/settings`). It is available to administrators on a Riptides-managed control plane.
## Danger Zone
[Section titled “Danger Zone”](#danger-zone)
* **Delete console**: permanently deletes this console and all of its data. You confirm by typing the console name. This cannot be undone.
Deleting the console does **not** uninstall the Riptides daemons running on your hosts. Remove those separately if you no longer want them. See [Uninstalling](../../deployment/uninstall).
## Next steps
[Section titled “Next steps”](#next-steps)
* [Uninstalling](../../deployment/uninstall): remove Riptides daemons from your hosts.
# Trust
The **Trust** screen shows your trust domain and its certificates, plus any federated trust domains you peer with. It is read-only: it reflects your CA and federation configuration rather than editing it here.
Open it from **System → Trust** in the sidebar (`/ui/trust`). Two tabs split the view: **Trust Details** and **Federated Trust Domains**.
## Trust Details
[Section titled “Trust Details”](#trust-details)
* **Trust Domain**: your SPIFFE trust domain.
* **SVID TTLs**: the **JWT SVID TTL** and **X509 SVID TTL**, the lifetimes of the identities Riptides issues.
* **CA Configuration**: the **CA TTL** and **Key Algorithm**.
Below that, a table of X.509 key pairs (your CA certificates) with their **Serial**, **Status**, **Issued At**, and **Expires**.
## Federated Trust Domains
[Section titled “Federated Trust Domains”](#federated-trust-domains)
Federation lets workloads in your trust domain establish mTLS with workloads in another organization’s trust domain. This tab shows one entry per federated peer, each with its **Trust Domain**, **Bundle Endpoint**, **Profile**, **Last Fetched** time, and any **Error**, along with the certificates and keys in that peer’s trust bundle (**Serial / Key ID**, **Type**, **Issued At**, **Expires**).
## Next steps
[Section titled “Next steps”](#next-steps)
* [Trust Domain Federation](../../concepts/federation): how peering between trust domains works.
* [Workload Identity](../../concepts/workload-identity): what the trust domain secures.
# Users
The **Users** screen (under System) manages the people who can sign in to and operate this Riptides console, and the role each one has.
Open it from **System → Users** in the sidebar (`/ui/users`). It appears when external user provisioning is enabled for your environment.
Note
These are console operator accounts. They are different from the [Users](../../agentic/users) screen under **Agentic**, which lists the identity-provider people who *drive agents* and are used as policy actors.
## What you see
[Section titled “What you see”](#what-you-see)
A table with these columns:
* **Name**: first and last name.
* **Email**.
* **Role**: **Viewer**, **Editor**, or **Admin**.
* **Created**: when the account was added.
Search by email. Each row’s **⋯** menu offers **Edit** and **Delete** (not for your own account).
## Add a user
[Section titled “Add a user”](#add-a-user)
Choose **Add User** and provide a **First name**, **Last name**, **Email**, and a **Role** (**Viewer**, **Editor**, or **Admin**). The role controls what the person can do in the console.
## Edit or delete
[Section titled “Edit or delete”](#edit-or-delete)
**Edit** changes a user’s role; **Delete** removes the account after a confirmation.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Users](../../agentic/users): the identity-provider people who drive AI agents.
* [OIDC and Identity Provider Setup](../../guides/oidc-setup): connect an identity provider for sign-in.
# Workloads
The **Workloads** screen shows every workload Riptides is observing across your connected hosts. A workload is a **process** running on a host, and Riptides observes each one together with the environment it runs in. The screen shows whether each has been matched to an identity. It is the observe-side counterpart to [Identities](../identities): Identities is what you configure, Workloads is what Riptides actually sees running.
Open it from **Observe → Workloads** in the sidebar (`/ui/workloads`).
## What you see
[Section titled “What you see”](#what-you-see)
A table of observed workloads, with these columns:
* **Status**: **Active** or **Inactive**.
* **Name**: the process name, with an icon indicating the environment it runs in (a plain host process, a container, or a Kubernetes pod).
* **Identity**: the workload identity that matches it. A warning icon appears when more than one identity matches (overlapping identities).
* **Node**: the host (daemon) it runs on, with cloud provider and instance shown where known.
* **Last Seen**: when it was last observed.
Search by name, and filter by **Status**, **Type**, **Identity** (whether it has one), and **Node**. A **Show System Processes** toggle brings in operating-system processes, which are hidden by default.
## A workload versus an identity
[Section titled “A workload versus an identity”](#a-workload-versus-an-identity)
A **workload** is a process running on one of your hosts, observed live (with a status and last-seen time). Riptides records the environment it runs in as metadata: the container or Kubernetes pod when there is one, or plain host facts otherwise. A **workload identity** is what you configure to give that process a cryptographic identity. The **Identity** column links an observed workload to the identity that matches it. A workload can have no identity yet, exactly one, or several overlapping ones.
## Opening a workload
[Section titled “Opening a workload”](#opening-a-workload)
Click a row to open its detail panel:
* **Workload Identity**: the identity matching it, and any overlapping or conflicting identities.
* **Environment**: node, region, and instance type.
* **Key Metadata**: the facts Riptides collected about the process and its environment (for example the process name and user, plus Kubernetes namespace, service account, and image, or Docker container name and image, depending on where it runs).
* **Inbound** and **Outbound connections**: what talks to it and what it talks to, with encryption and peer identity.
* The full workload and daemon metadata.
The panel also has a **Create identity** action that opens the identity form prefilled from this workload’s metadata: a quick way to turn something you are observing into a configured identity.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Identities](../identities): configure the identities workloads are matched to.
* [Connections](../connections): see the traffic between workloads.
# Deployment Architecture Overview
This document gives a brief overview of the components that make up a Riptides deployment and where each one runs.
The control plane is hosted and operated by Riptides: see [Control Plane](../control-plane) for how to connect to it. An on-premises control plane is also available; contact to discuss your requirements. The daemon and kernel module described below run in your own environment regardless of where the control plane is hosted.
## Components
[Section titled “Components”](#components)
### Control Plane
[Section titled “Control Plane”](#control-plane)
The control plane is hosted and operated by Riptides. It stores your configuration (WorkloadIdentities, Services, CredentialSources, and more), issues certificates, and distributes policy to daemons. You interact with it through the UI and [`riptides-cli`](../cli).
### Frontend
[Section titled “Frontend”](#frontend)
A web-based UI that shows registered workloads and their identities, active connections and mTLS status, and policy configuration and enforcement state.
### Daemon
[Section titled “Daemon”](#daemon)
The daemon is the node-level component that runs on every machine in your workload environment. It connects to the control plane to authenticate the node, receives policy and certificates, loads them into the kernel module, and collects metadata from the host environment (process info, cloud instance metadata, Kubernetes pod context) used to match workloads to identities.
On Kubernetes, the daemon is deployed as a **DaemonSet**. On bare metal or VMs, it runs as a systemd service or standalone process.
### Driver (Kernel Module)
[Section titled “Driver (Kernel Module)”](#driver-kernel-module)
The Riptides kernel module provides transparent, in-kernel security for TCP sockets:
* TLS/mTLS termination without application changes
* SPIFFE-based identity enforcement
* Policy-driven access control
* Works with kTLS offload when available, falls back to an in-kernel TLS 1.3 implementation
The daemon loads the driver on startup. See [Daemon on Kubernetes](../daemon-kubernetes) and [Daemon on Bare Metal](../daemon-bare-metal) for installation details.
## Mixed Environments
[Section titled “Mixed Environments”](#mixed-environments)
Riptides supports mixed environments where some workloads run on Kubernetes and others on bare-metal servers or VMs: all daemons connect to the same control plane regardless of where each workload runs. See [Daemon on Kubernetes](../daemon-kubernetes) and [Daemon on Bare Metal](../daemon-bare-metal) for per-environment installation steps.
## Network Requirements
[Section titled “Network Requirements”](#network-requirements)
Workload nodes (Kubernetes or bare metal) must be able to reach the control plane on these endpoints, all over HTTPS/TLS on port 443:
| Source | Destination | Protocol | Purpose |
| ------ | ------------------------ | -------- | ------------------------------------------------------------------ |
| Daemon | `` | HTTPS | API communication, certificate issuance |
| Daemon | `grpc.` | gRPCS | Information sync and streaming, including real-time policy updates |
| Daemon | `tunnel.` | TLS | Telemetry retrieval (pull model) |
The control plane does not initiate connections to daemons. All communication is daemon-initiated, making deployment behind NAT and firewalls straightforward.
# Install the Riptides CLI
The Riptides CLI (`riptides-cli`) is the primary tool for managing control plane resources. It provides the `riptides-cli ctl` command - a kubectl-compatible interface that handles authentication automatically - and `riptides-cli context` for managing multiple control plane connections.
## Installation
[Section titled “Installation”](#installation)
### macOS
[Section titled “macOS”](#macos)
Install via Homebrew:
```bash
brew tap riptides-packages/homebrew-tap
brew trust riptides-packages/tap
brew install --cask riptides-cli
```
### Linux
[Section titled “Linux”](#linux)
Packages are available for `amd64` and `arm64`. Replace `` with your architecture and `` with the release you want (e.g. `0.5.16`):
#### Debian / Ubuntu
[Section titled “Debian / Ubuntu”](#debian--ubuntu)
```bash
curl -LO https://github.com/riptides-packages/daemon/releases/download/v/riptides-cli__linux_.deb
sudo dpkg -i riptides-cli__linux_.deb
```
#### RHEL / Fedora / Amazon Linux
[Section titled “RHEL / Fedora / Amazon Linux”](#rhel--fedora--amazon-linux)
```bash
curl -LO https://github.com/riptides-packages/daemon/releases/download/v/riptides-cli__linux_.rpm
sudo rpm -i riptides-cli__linux_.rpm
```
#### Tarball
[Section titled “Tarball”](#tarball)
```bash
curl -LO https://github.com/riptides-packages/daemon/releases/download/v/riptides-cli__linux_.tar.gz
tar -xzf riptides-cli__linux_.tar.gz
sudo mv riptides-cli /usr/local/bin/
```
All releases are published at [github.com/riptides-packages/daemon/releases](https://github.com/riptides-packages/daemon/releases).
## Connect to a Control Plane
[Section titled “Connect to a Control Plane”](#connect-to-a-control-plane)
Add a context for your control plane. This opens a browser window to complete OIDC authentication and saves the session locally under `~/.riptides/contexts/`.
```bash
riptides-cli context add --url https://.console.riptides.io
```
On the first run, a browser window opens to authenticate. After authenticating, the token is cached and reused on subsequent commands until it expires - at which point `riptides-cli` will prompt you to log in again.
Verify the connection:
```bash
riptides-cli ctl get daemons
```
## Managing Contexts
[Section titled “Managing Contexts”](#managing-contexts)
If you connect to multiple control planes, use contexts to switch between them.
| Command | Description |
| -------------------------------------- | ---------------------------------------- |
| `riptides-cli context add []` | Add a new context and authenticate |
| `riptides-cli context list` | List all saved contexts |
| `riptides-cli context current` | Show the active context |
| `riptides-cli context use ` | Switch to a different context |
| `riptides-cli context status` | Show auth status for the current context |
| `riptides-cli context login []` | Re-authenticate an existing context |
| `riptides-cli context delete []` | Remove a context |
To target a specific context for a single command without switching, use the `--context` flag:
```bash
riptides-cli --context staging ctl get daemons
```
## Using `riptides-cli ctl`
[Section titled “Using riptides-cli ctl”](#using-riptides-cli-ctl)
`riptides-cli ctl` is a kubectl-compatible interface scoped to the Riptides control plane. It authenticates using your active context and defaults to the `riptides-system` namespace.
Supported subcommands: `get`, `describe`, `delete`, `apply`, `patch`, `replace`, `diff`, `wait`, `edit`, `label`, `annotate`, `explain`, `api-resources`, `api-versions`.
```bash
# List all connected daemons
riptides-cli ctl get daemons
# Inspect a WorkloadIdentity
riptides-cli ctl describe workloadidentity my-workload
# Apply a resource manifest
riptides-cli ctl apply -f my-resource.yaml
# Apply an inline manifest
riptides-cli ctl apply -f - <
The Riptides control plane is hosted and operated by Riptides. You do not need to deploy or manage it yourself. Your daemons connect to the hosted control plane, and you manage resources (WorkloadIdentities, Services, CredentialSources, etc.) through it.
An on-premises control plane is also available for organizations that require it. Contact to discuss your requirements.
## Accessing the Control Plane
[Section titled “Accessing the Control Plane”](#accessing-the-control-plane)
Log in to the control plane web UI at your tenant URL using your GitHub credentials.
For programmatic access, use [`riptides-cli`](../cli) (e.g., `riptides-cli ctl apply` for Riptides resources) configured with the control plane URL provided after signup.
## Architecture
[Section titled “Architecture”](#architecture)
The hosted control plane exposes three subdomains under your tenant’s base hostname (e.g. `0d4e539f.console.riptides.io`), each serving a different protocol:
| Endpoint | Protocol | Description |
| ------------------------ | -------- | ------------------------------------------------------------------- |
| `` | HTTPS | Primary API and UI endpoint for daemons and users |
| `grpc.` | gRPCS | Information sync and streaming between daemons and the controlplane |
| `tunnel.` | TLS | Telemetry retrieval from daemons (pull model) |
### Trust Domain
[Section titled “Trust Domain”](#trust-domain)
Your trust domain is assigned when you register at [console.riptides.io](https://console.riptides.io). It must match across the control plane and all daemons. This is typically a domain you own (e.g., `example.com`).
### Tunnel Server
[Section titled “Tunnel Server”](#tunnel-server)
The tunnel server at `tunnel.` lets the control plane retrieve telemetry from daemons in a pull model, over a persistent connection the daemon initiates. This applies regardless of whether the daemon is behind NAT.
### gRPC Server
[Section titled “gRPC Server”](#grpc-server)
The gRPC server at `grpc.` handles information sync and streaming between daemons and the control plane, including policy and certificate updates.
## Connecting Daemons
[Section titled “Connecting Daemons”](#connecting-daemons)
Daemons authenticate to the hosted control plane using one of the following methods:
* **JoinToken**: A pre-shared token created in the control plane. Suitable for initial setup and on-premises nodes.
* **AWSIID**: Automatic attestation using the EC2 instance identity document. No shared secrets needed.
* **GCPIIT**: Automatic attestation using GCP instance identity tokens.
See the [Getting Started](../../guides/getting-started) guide for a walkthrough of connecting your first daemon, or the daemon deployment guides for [Kubernetes](../daemon-kubernetes) and [bare metal / VM](../daemon-bare-metal) environments.
# Daemon Deployment on Bare Metal and VMs
This guide covers installing the Riptides daemon and kernel module on bare-metal Linux servers and virtual machines. This approach works for any Linux-based environment outside of Kubernetes, including EC2 instances, GCP VMs, Azure VMs, on-premises hardware, local development VMs (e.g., [Lima](https://lima-vm.io/)), and Windows hosts via [WSL2](#wsl2-on-windows).
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* Linux kernel 5.15+ (x86\_64 or ARM64), including the WSL2 kernel on Windows hosts
* Root access
* Network connectivity to the control plane’s API, gRPC, and tunnel endpoints (HTTPS/TLS on port 443)
## Step 1: Install the Kernel Module
[Section titled “Step 1: Install the Kernel Module”](#step-1-install-the-kernel-module)
The Riptides kernel module provides transparent in-kernel TLS/mTLS termination for TCP sockets.
The recommended way to install it is via the **driver-loader** package, which automatically detects your kernel version and architecture and downloads and installs the correct driver package. Download the appropriate package from the [driver-loader releases page](https://github.com/riptides-packages/driver-loader/releases) and install it:
**Debian / Ubuntu:**
```bash
sudo dpkg -i riptides-driver-loader__.deb
# or
sudo apt install ./riptides-driver-loader__.deb
```
**CentOS / Fedora / Amazon Linux:**
```bash
sudo rpm -i riptides-driver-loader-..rpm
# or
sudo dnf install ./riptides-driver-loader-..rpm
```
Alternatively, download the driver package directly from the [driver releases page](https://github.com/riptides-packages/driver/releases). Select the driver version and the package matching your kernel version and architecture, then install it manually:
```bash
# Debian / Ubuntu
sudo dpkg -i riptides-driver--__.deb
# e.g. riptides-driver-ubuntu-6.14.0-37-generic_v0.5.15_arm64.deb
# CentOS / Fedora / Amazon Linux
sudo rpm -i riptides-driver--_..rpm
```
### Verify the Module
[Section titled “Verify the Module”](#verify-the-module)
Confirm the kernel module loaded successfully:
```bash
# Check kernel messages
sudo dmesg -T | grep riptides
# Verify the module is loaded
lsmod | grep riptides
# Check driver health
cat /proc/riptides/health
```
The health endpoint will report “waiting for daemon” until the daemon connects and pushes configuration. This is expected.
## Step 2: Install the Daemon Binary
[Section titled “Step 2: Install the Daemon Binary”](#step-2-install-the-daemon-binary)
Install the daemon from the package repository:
**Debian / Ubuntu:**
```bash
sudo apt install riptides-daemon
```
**RHEL / Fedora / Amazon Linux:**
```bash
sudo dnf install riptides-daemon
```
Alternatively, build from source (requires a GitHub account with access to the daemon repository):
```bash
git clone https://github.com/riptideslabs/daemon.git
cd daemon
GOOS=linux make build
# The binary is at ./build/riptides
sudo cp ./build/riptides /usr/local/bin/riptides
```
## Step 3: Configure the Daemon
[Section titled “Step 3: Configure the Daemon”](#step-3-configure-the-daemon)
Create the configuration directories:
```bash
sudo mkdir -p /etc/riptides/identities
sudo mkdir -p /etc/riptides/services
sudo mkdir -p /etc/riptides/credentials
```
Create a configuration file at `/etc/riptides/config.yaml`:
```yaml
daemon:
trustDomain: example.com
defaultCertTTL: 2h
dataDir: /var/lib/riptides
metadataCollectors:
procfs:
enabled: true
extractEnvs: false
linuxos:
enabled: true
sysfsdmi:
enabled: true
ec2:
enabled: false # Set to true on AWS EC2
gcp:
enabled: false # Set to true on GCP
azure:
enabled: false # Set to true on Azure
kubernetes:
enabled: false # Disable on bare metal
docker:
enabled: false
controlPlane:
enabled: true
url: https://cp.example.com
grpcServerAddress: grpc.example.com:443
tokenBrokerBaseURL: https://cp.example.com/token-broker
authPlugin:
type: joinToken
config:
token: "your-join-token-here"
tunnelServer:
address: tunnel.example.com:443
```
Enable the cloud metadata collectors relevant to your environment:
* **AWS EC2**: Set `ec2.enabled: true` and use `authPlugin.type: AWSIID` for automatic attestation
* **GCP**: Set `gcp.enabled: true` and use `authPlugin.type: GCPIIT`
* **Azure**: Set `azure.enabled: true` and use `authPlugin.type: AzureIMDS`
* **On-premises / local VMs**: Use `authPlugin.type: joinToken` with a pre-shared token
## Step 4: Run the Daemon
[Section titled “Step 4: Run the Daemon”](#step-4-run-the-daemon)
Run the daemon manually:
```bash
sudo riptides daemon \
--identities-path /etc/riptides/identities \
--services-path /etc/riptides/services \
--credentials-path /etc/riptides/credentials
```
### Run as a systemd Service
[Section titled “Run as a systemd Service”](#run-as-a-systemd-service)
Create a systemd unit file at `/etc/systemd/system/riptides-daemon.service`:
```ini
[Unit]
Description=Riptides Daemon
After=network-online.target
Wants=network-online.target
ConditionPathExists=/dev/riptides
[Service]
Type=simple
ExecStart=/usr/local/bin/riptides daemon \
--identities-path /etc/riptides/identities \
--services-path /etc/riptides/services \
--credentials-path /etc/riptides/credentials
Restart=always
RestartSec=5
LimitNOFILE=65536
[Install]
WantedBy=multi-user.target
```
Enable and start the service:
```bash
sudo systemctl daemon-reload
sudo systemctl enable riptides-daemon
sudo systemctl start riptides-daemon
sudo systemctl status riptides-daemon
```
## Step 5: Verify
[Section titled “Step 5: Verify”](#step-5-verify)
Once the daemon is running, the driver health should report OK:
```bash
cat /proc/riptides/health
```
Check daemon logs:
```bash
# If running as a systemd service
sudo journalctl -u riptides-daemon -f
# If running manually, logs go to stdout/stderr
```
## Local Development with Lima
[Section titled “Local Development with Lima”](#local-development-with-lima)
You can run Riptides in a local [Lima](https://lima-vm.io/) VM for development and testing. This is useful for testing workload identity assignment and credential injection locally before deploying to production infrastructure.
### One command with the Riptides Lima template
[Section titled “One command with the Riptides Lima template”](#one-command-with-the-riptides-lima-template)
The [`riptideslabs/lima-templates`](https://github.com/riptideslabs/lima-templates) repo ships a ready-made template (requires Lima 2.0 or later) that boots the latest Ubuntu, installs the daemon and kernel driver, and joins your control plane - all from a single `limactl start`. Generate a join token first (**Daemons → Attach Daemon** in the UI, or a `JoinToken` resource), then:
```bash
limactl start --name=riptides \
--param controlplaneUrl="https://.console.riptides.io" \
--param token="" \
github:riptideslabs/lima-templates/templates/riptides
```
> **Tip:** You don’t have to fill this in by hand - the control plane UI generates a ready-to-use command with your control plane URL and a fresh join token already inserted. Go to **Daemons → Attach Daemon** and open the **Lima** tab, then copy the command.
Lima’s `github:` scheme fetches the template straight from the repo’s default branch - no cloning required. Append `@` to pin a specific version. Once the VM is up, verify the daemon:
```bash
limactl shell riptides -- systemctl status riptides
```
The join is idempotent across reboots, so a single-use token is not re-consumed. The first boot is slower because the driver is compiled against the VM’s kernel.
### Manual install
[Section titled “Manual install”](#manual-install)
Alternatively, install the kernel module and daemon inside any Lima VM using the same installer steps as above, and connect it to the hosted control plane using a JoinToken.
## WSL2 on Windows
[Section titled “WSL2 on Windows”](#wsl2-on-windows)
On a Windows host the workload runs inside WSL2, and Riptides installs into the WSL2 distribution exactly as it does on any other Linux machine. The examples below assume **Ubuntu**, the default WSL distribution; any Debian-family distribution installs the same way, and rpm-based ones take the `.rpm` packages instead.
WSL2 boots Microsoft’s own kernel rather than the distribution’s, so `uname -r` reports something like `6.6.123.2-microsoft-standard-WSL2`. The driver is built per kernel version, so the package has to match that kernel. The driver-loader keys on the kernel release rather than on `/etc/os-release` for exactly this reason - every WSL distribution on a machine shares the one Microsoft kernel, so one driver package serves all of them.
Three things are specific to WSL2:
**systemd is required, and Ubuntu enables it by default.** The driver-loader and the daemon both run as systemd services. In WSL2 systemd is a per-distribution setting rather than a platform default, but Ubuntu’s WSL image enables it out of the box, so on Ubuntu there is nothing to do. Check inside the distribution:
```bash
ps -p 1 -o comm= # systemd, or init/wsl-init if it is not running
```
If it is not systemd, add it to `/etc/wsl.conf` and restart the VM from Windows:
```ini
[boot]
systemd=true
```
```powershell
wsl --shutdown
```
Running without systemd is planned but not implemented yet. Until it lands, a distribution that cannot enable systemd needs the container route: the daemon runs in a container (Docker, or Kubernetes with the [Helm chart](/deployment/daemon-kubernetes/)) while the kernel module is still loaded into the WSL2 kernel from the distribution itself. The native installer deliberately refuses to run inside a container.
**Reinstall the driver after a WSL update.** `wsl --update` replaces the WSL2 kernel, and a module built for the previous version will no longer load. Re-run the driver-loader after updating WSL to pick up the driver for the new kernel.
Caution
WSL2 ships no kernel headers package, so the driver cannot be rebuilt on the machine - DKMS has nothing to build against. It must come from a prebuilt package matching the running WSL2 kernel.
## Diagnostics
[Section titled “Diagnostics”](#diagnostics)
The Riptides kernel module exposes several diagnostic endpoints for troubleshooting.
### Direct Endpoints
[Section titled “Direct Endpoints”](#direct-endpoints)
| Path | Description |
| ----------------------------------- | ------------------------------------- |
| `/proc/riptides/health` | Driver health status |
| `/proc/riptides/certificates` | Currently loaded certificates |
| `/proc/riptides/connections` | Active connection state |
| `/proc/riptides/trust_anchors` | Trust anchor chain |
| `/sys/module/riptides/credentials/` | Credential files loaded by the daemon |
Example - dump certificates directly:
```bash
cat /proc/riptides/certificates | python3 -m json.tool
```
Example - enable kernel dynamic debug for the module:
```bash
echo -n '-p; module riptides +pftl' | sudo tee /proc/dynamic_debug/control > /dev/null
```
## Uninstalling
[Section titled “Uninstalling”](#uninstalling)
### Remove the Daemon
[Section titled “Remove the Daemon”](#remove-the-daemon)
```bash
sudo systemctl stop riptides-daemon
sudo systemctl disable riptides-daemon
sudo rm /etc/systemd/system/riptides-daemon.service
sudo systemctl daemon-reload
```
If installed via package:
```bash
sudo apt remove riptides-daemon # Debian/Ubuntu
sudo dnf remove riptides-daemon # RHEL/Fedora
```
### Remove the Kernel Module
[Section titled “Remove the Kernel Module”](#remove-the-kernel-module)
```bash
# Unload the module
sudo modprobe -r riptides
# Remove the package
sudo apt remove riptides-driver # Debian/Ubuntu
sudo dnf remove riptides-driver # RHEL/Fedora
```
## Example: AWS EC2 Deployment
[Section titled “Example: AWS EC2 Deployment”](#example-aws-ec2-deployment)
A complete configuration for an EC2 instance that attests using the instance identity document:
```yaml
daemon:
trustDomain: example.com
defaultCertTTL: 2h
dataDir: /var/lib/riptides
metadataCollectors:
procfs:
enabled: true
extractEnvs: false
linuxos:
enabled: true
sysfsdmi:
enabled: true
ec2:
enabled: true
gcp:
enabled: false
azure:
enabled: false
kubernetes:
enabled: false
docker:
enabled: false
controlPlane:
enabled: true
url: https://cp.example.com
grpcServerAddress: grpc.example.com:443
tokenBrokerBaseURL: https://cp.example.com/token-broker
authPlugin:
type: AWSIID
tunnelServer:
address: tunnel.example.com:443
```
No shared secrets are needed - the daemon uses the EC2 instance identity document signed by AWS for attestation with the control plane.
# Daemon Deployment on Kubernetes
This guide covers deploying the Riptides daemon as a DaemonSet on Kubernetes clusters. The daemon runs on every node, loads the Riptides kernel module, and connects to the control plane for identity issuance and policy enforcement.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* Kubernetes 1.24+
* Helm 3.2.0+
* Privileged container support (required for kernel module loading)
* On Azure, use an **AKS Standard** cluster. AKS Automatic blocks the daemon by default; see [AKS Automatic: daemon blocked by admission policies](#aks-automatic-daemon-blocked-by-admission-policies) under Troubleshooting.
* Network connectivity from workload nodes to the control plane’s API, gRPC, and tunnel endpoints (HTTPS/TLS on port 443)
* A running Riptides control plane (see [Control Plane Deployment](../control-plane))
## Installation
[Section titled “Installation”](#installation)
Install the daemon using the Riptides OCI Helm chart:
```bash
helm install riptides-daemon oci://ghcr.io/riptides-packages/helm/daemon --version version \
--namespace riptides-system \
--create-namespace \
-f daemon-values.yaml
```
## How It Works
[Section titled “How It Works”](#how-it-works)
The daemon Helm chart deploys a **DaemonSet** that runs on every node in your cluster. Each pod consists of:
1. **Driver loader init container**: loads the Riptides kernel module onto the host before the daemon starts. The init container runs privileged and uses a pre-built image matching your kernel version and distribution.
2. **Daemon container**: the main daemon process that communicates with the kernel module (via `/dev/riptides`), connects to the control plane, manages certificates, and applies policies.
## Configuration Reference
[Section titled “Configuration Reference”](#configuration-reference)
### Daemon Core Settings
[Section titled “Daemon Core Settings”](#daemon-core-settings)
All daemon settings live under `config.daemon`:
| Parameter | Description | Default |
| ---------------------------------- | ----------------------------------------------------------------------------------------------------------------------------------------------------------------------------------------- | -------------------- |
| `config.daemon.trustDomain` | SPIFFE trust domain (must match control plane) | `example.com` |
| `config.daemon.defaultCertTTL` | Default TTL for issued workload certificates | `2h` |
| `config.daemon.dataDir` | Persistent data directory inside the container | `/data/riptides` |
| `config.daemon.kernelModuleDevice` | Path to the kernel module character device | `/host/dev/riptides` |
| `config.daemon.ephemeral` | Auto-remove this daemon after it stops heart-beating. Overrides the control-plane attestation default; omit to let the control plane decide. Useful for daemons on autoscaled/spot nodes. | *(unset)* |
### Control Plane Connection
[Section titled “Control Plane Connection”](#control-plane-connection)
Settings under `config.daemon.controlPlane`:
| Parameter | Description | Default |
| ---------------------------------------------------- | ---------------------------------------- | --------------------------- |
| `config.daemon.controlPlane.enabled` | Enable control plane connection | `true` |
| `config.daemon.controlPlane.url` | HTTPS base URL of the control plane | `https://controlplane:8443` |
| `config.daemon.controlPlane.grpcServerAddress` | gRPC endpoint (host:port) | *none* |
| `config.daemon.controlPlane.tokenBrokerBaseURL` | Token broker endpoint URL | *none* |
| `config.daemon.controlPlane.allowInsecureConnection` | Skip TLS verification (development only) | `false` |
| `config.daemon.controlPlane.authPlugin.type` | Authentication plugin type (see below) | `joinToken` |
When using separate DNS records for each control plane service (typical in production), configure all three endpoints:
```yaml
config:
daemon:
controlPlane:
url: https://cp.example.com
grpcServerAddress: grpc.example.com:443
tokenBrokerBaseURL: https://cp.example.com/token-broker
```
### Tunnel Server
[Section titled “Tunnel Server”](#tunnel-server)
Configure a tunnel connection so the control plane can retrieve telemetry from the daemon in a pull model:
| Parameter | Description | Default |
| ------------------------------------ | ---------------------------------- | ------- |
| `config.daemon.tunnelServer.address` | Tunnel server endpoint (host:port) | *none* |
```yaml
config:
daemon:
tunnelServer:
address: tunnel.example.com:443
```
### Authentication Plugins
[Section titled “Authentication Plugins”](#authentication-plugins)
The daemon authenticates to the control plane using one of these plugins:
#### Kubernetes Service Account Token (K8sSAT)
[Section titled “Kubernetes Service Account Token (K8sSAT)”](#kubernetes-service-account-token-k8ssat)
**Recommended for DaemonSets.** Since the daemon runs as one pod per node, K8sSAT lets every pod authenticate on its own: the Helm chart automatically projects a ServiceAccount token into the pod (audience `riptides`) when this plugin is selected, so there’s no secret to create or distribute across nodes.
```yaml
config:
daemon:
controlPlane:
authPlugin:
type: K8sSAT
config:
clusterID: "your-cluster-id"
```
Create the corresponding Verifier on the control plane once for the whole cluster:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: k8s-cluster
namespace: riptides-system
spec:
K8sSAT:
clusterID: "your-cluster-id"
audience: riptides
jwksSource:
remote:
url: "https://your-k8s-api-server/openid/v1/jwks"
```
`clusterID` is an arbitrary identifier you choose — it just has to match between the Verifier and the daemon config. See [Attestation and Selectors](../../concepts/workload-attestation#example-k8ssat-verifier) for details on the JWKS source.
#### Join Token
[Section titled “Join Token”](#join-token)
A single-use, pre-shared token: the control plane deletes it as soon as one daemon authenticates with it. This makes it a good fit for a one-off manual attach (a single VM or bare-metal host), but **not for a DaemonSet** — every pod would need its own distinct token, since only the first pod to present a given token succeeds and the rest fail authentication. Use K8sSAT (above) for DaemonSets instead.
```yaml
config:
daemon:
controlPlane:
authPlugin:
type: joinToken
config:
token: "your-join-token-here"
```
Create the corresponding resources on the control plane:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: jointoken
namespace: riptides-system
spec:
joinToken: {}
---
apiVersion: auth.riptides.io/v1alpha1
kind: JoinToken
metadata:
name: my-join-token
namespace: riptides-system
spec:
token: "your-join-token-here"
```
#### AWS Instance Identity Document (AWSIID)
[Section titled “AWS Instance Identity Document (AWSIID)”](#aws-instance-identity-document-awsiid)
Recommended for AWS deployments. The daemon uses the EC2 instance identity document for attestation, so no shared secrets are required:
```yaml
config:
daemon:
controlPlane:
authPlugin:
type: AWSIID
```
#### GCP Instance Identity Token (GCPIIT)
[Section titled “GCP Instance Identity Token (GCPIIT)”](#gcp-instance-identity-token-gcpiit)
Recommended for GCP deployments. Uses the GCP instance identity token:
```yaml
config:
daemon:
controlPlane:
authPlugin:
type: GCPIIT
```
### Metadata Collectors
[Section titled “Metadata Collectors”](#metadata-collectors)
Metadata collectors enrich workload identity information with context from the runtime environment. Configure under `config.daemon.metadataCollectors`:
| Collector | Description | Default |
| -------------------- | --------------------------------------- | ---------------- |
| `procfs` | Collects process information from /proc | `enabled: true` |
| `procfs.extractEnvs` | Also collect environment variables | `false` |
| `linuxos` | Collects OS release information | `enabled: true` |
| `sysfsdmi` | Collects DMI/SMBIOS hardware info | `enabled: true` |
| `ec2` | AWS EC2 instance metadata | `enabled: true` |
| `gcp` | GCP instance metadata | `enabled: true` |
| `azure` | Azure instance metadata | `enabled: true` |
| `kubernetes` | Kubernetes pod and node metadata | `enabled: true` |
| `docker` | Docker container metadata | `enabled: false` |
For the Kubernetes metadata collector:
| Parameter | Description | Default |
| ------------------------------------ | ------------------------------ | ----------------------------------------------------- |
| `kubernetes.kubeletHost` | Kubelet API host | `localhost` |
| `kubernetes.kubeletPort` | Kubelet API port | `10250` |
| `kubernetes.kubeletCA` | Path to kubelet CA certificate | `/etc/kubernetes/pki/ca.crt` |
| `kubernetes.skipKubeletVerification` | Skip kubelet TLS verification | `true` |
| `kubernetes.credentials` | Path to service account token | `/var/run/secrets/kubernetes.io/serviceaccount/token` |
Disable cloud provider collectors that do not apply to your environment to avoid unnecessary metadata API calls:
```yaml
config:
daemon:
metadataCollectors:
ec2:
enabled: true
gcp:
enabled: false
azure:
enabled: false
```
### Driver Loader
[Section titled “Driver Loader”](#driver-loader)
The driver loader init container loads the Riptides kernel module before the daemon starts:
| Parameter | Description | Default |
| ------------------------------- | ------------------------------------------- | ------------------------------------------------ |
| `driverLoader.image.repository` | Driver loader image | `ghcr.io/riptides-packages/images/driver-loader` |
| `driverLoader.image.pullPolicy` | Pull policy | `IfNotPresent` |
| `driverLoader.driverVersion` | Driver version (git branch, tag, or commit) | `main` |
| `driverLoader.commandTimeout` | Timeout in seconds for load commands | `5` |
| `driverLoader.dynDBG` | Enable kernel dynamic debug for the module | `false` |
### Health Check
[Section titled “Health Check”](#health-check)
| Parameter | Description | Default |
| ------------------- | ------------------------ | ------- |
| `healthStatus.port` | Daemon health check port | `10100` |
## Example: AWS EKS Deployment
[Section titled “Example: AWS EKS Deployment”](#example-aws-eks-deployment)
A complete `daemon-values.yaml` for an AWS EKS cluster:
```yaml
image:
tag: "v0.1.0"
pullPolicy: Always
driverLoader:
image:
tag: "v0.5.2"
driverVersion: "v0.1.0"
commandTimeout: 5
dynDBG: false
config:
daemon:
trustDomain: example.com
defaultCertTTL: 2h
dataDir: /data/riptides
metadataCollectors:
procfs:
enabled: true
extractEnvs: false
linuxos:
enabled: true
sysfsdmi:
enabled: true
ec2:
enabled: true
gcp:
enabled: false
azure:
enabled: false
kubernetes:
enabled: true
kubeletHost: localhost
kubeletPort: 10250
kubeletCA: /etc/kubernetes/pki/ca.crt
skipKubeletVerification: true
credentials: /var/run/secrets/kubernetes.io/serviceaccount/token
docker:
enabled: false
controlPlane:
enabled: true
url: https://cp.example.com
grpcServerAddress: grpc.example.com:443
tokenBrokerBaseURL: https://cp.example.com/token-broker
authPlugin:
type: AWSIID
tunnelServer:
address: tunnel.example.com:443
healthStatus:
port: 10100
resources:
requests:
cpu: 100m
memory: 128Mi
limits:
cpu: 500m
memory: 512Mi
tolerations:
- operator: Exists
```
## Verifying the Deployment
[Section titled “Verifying the Deployment”](#verifying-the-deployment)
Check that daemon pods are running on all nodes:
```bash
kubectl get pods -n riptides-system -l app.kubernetes.io/name=daemon -o wide
```
Check the driver loader init container logs to confirm the kernel module loaded:
```bash
kubectl logs -n riptides-system -l app.kubernetes.io/name=daemon -c daemon-driver-loader
```
Check the daemon logs for control plane connectivity:
```bash
kubectl logs -n riptides-system -l app.kubernetes.io/name=daemon -f
```
Verify health:
```bash
kubectl port-forward -n riptides-system daemonset/riptides-daemon 10100:10100
curl http://localhost:10100/healthz
```
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
### Driver loader fails
[Section titled “Driver loader fails”](#driver-loader-fails)
If the init container fails, the kernel module loader may have failed. Check the kernel module loader init container.
```bash
kubectl logs -n riptides-system -c daemon-driver-loader
```
### Daemon cannot reach control plane
[Section titled “Daemon cannot reach control plane”](#daemon-cannot-reach-control-plane)
Verify network connectivity from a workload node to the control plane endpoints:
```bash
kubectl run -n riptides-system netcheck --rm -it --image=busybox -- \
wget -qO- --timeout=5 https://cp.example.com/healthz
```
Ensure your security groups or network policies allow outbound HTTPS/TLS (port 443) traffic to the control plane’s API (`cp.example.com`), gRPC (`grpc.example.com`), and tunnel (`tunnel.example.com`) endpoints.
### Authentication failures
[Section titled “Authentication failures”](#authentication-failures)
Check that the trust domain in the daemon configuration exactly matches the trust domain configured on the control plane. For join token auth, verify the token value matches the `JoinToken` resource on the control plane — and remember a JoinToken is deleted after its first successful use, so if multiple pods (e.g. a DaemonSet) are configured with the same token, only the first one to start will succeed; the rest will fail with “invalid join token”. Switch to K8sSAT (above) if that’s what’s happening.
### AKS Automatic: daemon blocked by admission policies
[Section titled “AKS Automatic: daemon blocked by admission policies”](#aks-automatic-daemon-blocked-by-admission-policies)
On **AKS Automatic** clusters, `helm install` fails with admission errors such as:
```plaintext
ValidatingAdmissionPolicy 'aks-managed-baseline-host-namespaces' denied request:
Host network namespaces are disallowed: spec.hostNetwork is set to true
ValidatingAdmissionPolicy 'aks-managed-block-nodes-proxy-rbac' denied request:
Creating RBAC rules that grant nodes/proxy access is not allowed.
```
The daemon is a privileged, host-network DaemonSet that loads a kernel module. AKS Automatic turns on Kubernetes guardrails by default (Deployment Safeguards with baseline Pod Security Standards, plus managed admission policies), and they reject what the daemon needs: `hostNetwork`, privileged containers, `hostPath` mounts, and `nodes/proxy` RBAC.
The supported option is an **AKS Standard** cluster, where these policies are off by default and the daemon installs without changes.
If you have to run on AKS Automatic, exclude the daemon’s namespace from Deployment Safeguards:
```bash
az aks safeguards update --resource-group --name \
--level Enforce --excluded-ns riptides-system
```
Even then, some limits remain:
* Namespace exclusion is all or nothing. It removes every baseline Pod Security protection for that namespace, not only the ones the daemon needs.
* The `nodes/proxy` policy has no namespace exclusion, so the daemon’s `nodes/proxy` ClusterRole can’t be exempted and must not be created. That grant is only used by the direct-kubelet metadata path. The default metadata collection talks to the Kubernetes API server and doesn’t need it, so leave the `metadataCollectors.kubernetes` kubelet settings at their defaults. The chart has no flag to drop this ClusterRole on its own (it is created along with `serviceAccount.create`), so strip it with a Helm `--post-renderer` patch, or from the rendered manifests, until the chart adds an option.
* Managed node pools can still block loading an out-of-tree kernel module, so the driver may fail to load even after you exclude the namespace.
## Upgrading
[Section titled “Upgrading”](#upgrading)
```bash
helm upgrade riptides-daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
-f daemon-values.yaml
```
The DaemonSet performs a rolling update by default. The driver loader init container will reload the kernel module on each node as pods restart.
# Free Account
Register a free account to get started with Riptides. Free accounts are fully functional — you can connect daemons, define WorkloadIdentities, enforce mTLS, and deliver secretless credentials just as you would in production. Free accounts support a small number of nodes; contact for a production plan if you need more.
## Register
[Section titled “Register”](#register)
Go to **[console.riptides.io](https://console.riptides.io)** and submit the registration form.
## After registration
[Section titled “After registration”](#after-registration)
1. **Confirmation email** — check your inbox and click the approval link. The link expires after 7 days.
2. **Control plane deployment** — Riptides deploys your dedicated control plane. This typically takes a few minutes.
3. **Access details email** — once your control plane is ready, you’ll receive a second email containing:
| Item | What it is | Where you use it |
| ----------------- | ---------------------------------------------------------------------------------------- | ----------------------------- |
| Control plane URL | The HTTPS endpoint for your tenant (e.g. `https://db16a6be.console.riptides.io`) | Daemon config, `riptides-cli` |
| Trust domain | A domain string used as the root of all SPIFFE IDs (e.g. `db16a6be.console.riptides.io`) | Daemon config |
## Default authentication
[Section titled “Default authentication”](#default-authentication)
Free accounts ship with **email code** authentication pre-configured. The registering user’s email address is the only account authorised out of the box — when you log in to the UI or run a `riptides-cli` command for the first time, Riptides emails a one-time code to that address and you enter it to authenticate.
This is intentional for getting started quickly, but it is not suitable for team access. Once you are up and running, configure a proper [IdentityProvider](/guides/oidc-setup/) (GitHub, Google, Entra, or OIDC) so that team members can authenticate with their normal credentials.
## Set up riptides-cli access
[Section titled “Set up riptides-cli access”](#set-up-riptides-cli-access)
Install [`riptides-cli`](../cli) if you have not already, then add a context for your control plane:
```bash
riptides-cli context add --url https://.console.riptides.io
```
Verify access:
```bash
riptides-cli context status
```
On the first run this opens a browser window. You will be prompted to enter the email code sent to your registered address. After authenticating, the token is cached and reused until expiry.
## Next steps
[Section titled “Next steps”](#next-steps)
Once you have your access details, follow the [Getting Started guide](/guides/getting-started/) to connect your first daemon.
# Uninstalling Riptides
The Riptides uninstaller removes the daemon, kernel module, and associated systemd services from a Linux host. It supports both a standard removal (configuration and data are preserved) and a full purge that deletes everything.
The installer places the uninstall script at `/usr/local/bin/riptides-uninstall.sh`, so on any node where Riptides was installed with `install.sh` you can run it directly:
```bash
# Standard removal - config and data directories are kept
sudo riptides-uninstall.sh
# Full purge - also deletes /etc/riptides and /var/lib/riptides
sudo riptides-uninstall.sh --purge
# Skip the confirmation prompt
sudo riptides-uninstall.sh --yes
```
If the script is not present (for example, it was manually removed or installation was incomplete), you can fetch and run it directly:
```bash
curl -fsSL https://docs.riptides.io/uninstall.sh | sudo bash
# with flags:
curl -fsSL https://docs.riptides.io/uninstall.sh | sudo bash -s -- --purge
```
The uninstaller needs root privileges. If you run `riptides-uninstall.sh` without `sudo`, it automatically re-runs itself under `sudo`; if `sudo` is unavailable it exits with an error.
## What Gets Removed
[Section titled “What Gets Removed”](#what-gets-removed)
### Always removed
[Section titled “Always removed”](#always-removed)
| Item | Details |
| ---------------- | --------------------------------------------------------------------------------------------- |
| systemd services | `riptides`, `riptides-modules`, `riptides-driver-loader` - stopped and disabled |
| systemd drop-in | `/etc/systemd/system/riptides-driver-loader.service.d/` |
| Kernel module | Unloaded with `modprobe -r riptides` (or `rmmod` as fallback) |
| Packages | All `riptides*` packages via `dpkg -r` (Debian/Ubuntu) or `rpm -e` (RHEL/Fedora/Amazon Linux) |
| Uninstall script | `/usr/local/bin/riptides-uninstall.sh` |
### Removed only with `--purge`
[Section titled “Removed only with --purge”](#removed-only-with---purge)
| Directory | Contents |
| ------------------- | ------------------------------------------------------------- |
| `/var/lib/riptides` | Certificates, private keys, and workload identity state |
| `/etc/riptides` | Daemon configuration, identity, service, and credential files |
Caution
`--purge` permanently deletes certificates and keys. The daemon will need to re-attest and obtain new credentials the next time it starts. Do not use `--purge` on a node you intend to re-enroll without re-provisioning through the control plane.
## Options
[Section titled “Options”](#options)
| Flag | Description |
| ------------------ | --------------------------------------------------------------- |
| `--purge` | Also remove the data directory and config directory |
| `--data-dir DIR` | Override the data directory path (default: `/var/lib/riptides`) |
| `--config-dir DIR` | Override the config directory path (default: `/etc/riptides`) |
| `--yes`, `-y` | Skip the confirmation prompt |
| `--verbose`, `-v` | Print full output from package manager and `systemctl` commands |
| `--help`, `-h` | Show usage |
## Confirmation Prompt
[Section titled “Confirmation Prompt”](#confirmation-prompt)
By default the script prints a summary of what will be removed and asks for confirmation:
```plaintext
▶ Riptides Uninstaller
The following will be removed:
• riptides systemd services (riptides, riptides-modules, riptides-driver-loader)
• riptides kernel module
• riptides packages (daemon + driver)
daemon version : v0.5.3
driver version : v0.5.3
• data directory : /var/lib/riptides (kept - pass --purge to also remove)
• config directory: /etc/riptides (kept - pass --purge to also remove)
Continue? [y/N]
```
Pass `--yes` to skip this prompt in automated or scripted environments.
## Kernel Module Caveat
[Section titled “Kernel Module Caveat”](#kernel-module-caveat)
If the kernel module cannot be unloaded (for example because a process still holds an open socket managed by the driver), the script emits a warning and continues:
```plaintext
⚠ Kernel module still loaded - reboot may be required
```
A reboot will fully unload the module. Everything else (packages, services, files) will have been removed by that point.
## Manual Uninstall
[Section titled “Manual Uninstall”](#manual-uninstall)
If you prefer to uninstall without the script, or need to clean up a partial install, follow these steps:
### 1. Stop and disable services
[Section titled “1. Stop and disable services”](#1-stop-and-disable-services)
```bash
sudo systemctl stop riptides riptides-modules riptides-driver-loader
sudo systemctl disable riptides riptides-modules riptides-driver-loader
```
### 2. Unload the kernel module
[Section titled “2. Unload the kernel module”](#2-unload-the-kernel-module)
```bash
sudo modprobe -r riptides
# or, if modprobe is unavailable:
sudo rmmod riptides
```
### 3. Remove packages
[Section titled “3. Remove packages”](#3-remove-packages)
**Debian / Ubuntu:**
```bash
sudo dpkg -r $(dpkg -l 'riptides*' | awk '/^ii/{print $2}')
```
**RHEL / Fedora / Amazon Linux:**
```bash
sudo rpm -e $(rpm -qa 'riptides*')
```
### 4. Remove leftover files
[Section titled “4. Remove leftover files”](#4-remove-leftover-files)
```bash
# systemd drop-in
sudo rm -rf /etc/systemd/system/riptides-driver-loader.service.d
sudo systemctl daemon-reload
# Uninstall script (if present)
sudo rm -f /usr/local/bin/riptides-uninstall.sh
# Config and data (--purge equivalent)
sudo rm -rf /etc/riptides
sudo rm -rf /var/lib/riptides
```
# Updating Riptides
Update the Riptides daemon and kernel driver on an already-installed node in place. The daemon keeps its existing identity and configuration, so **no re-authentication happens** - updating never re-runs enrollment.
The installer leaves an update helper at `/usr/local/bin/riptides-update.sh` (alongside `riptides-uninstall.sh`), so on any node installed with `install.sh` you can run it directly:
```bash
# Update both the daemon and the driver to the latest release
sudo riptides-update.sh
# Daemon only - no kernel-module reload, so no traffic interruption
sudo riptides-update.sh --update-daemon
# Reinstall/restart even if already at the target version
sudo riptides-update.sh --force
```
The helper is a thin wrapper: it fetches the current installer and runs it in update mode, forwarding any flags. The equivalent one-liner (for a first upgrade before the helper exists, or in automation) is:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- --update
```
## What Gets Updated
[Section titled “What Gets Updated”](#what-gets-updated)
The update compares the installed versions against the latest releases and **only reinstalls what is out of date**. If everything is already current it exits without restarting anything.
| Flag | Effect |
| ----------------- | ------------------------------------------------------- |
| `--update` | Update the daemon **and** the driver |
| `--update-daemon` | Update only the daemon |
| `--update-driver` | Update only the driver |
| `--force` | Reinstall/restart even if already at the target version |
## Pinning a Version
[Section titled “Pinning a Version”](#pinning-a-version)
By default the latest release of each component is installed. Pin a specific target with `--daemon-version` / `--driver-version` - the daemon and driver are versioned independently:
```bash
sudo riptides-update.sh --daemon-version v0.5.13
# or via the installer one-liner:
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- --update --daemon-version v0.5.13
```
Driver updates briefly interrupt traffic
`--update` and `--update-driver` reload the kernel module, which momentarily tears down active mTLS interception on the node. Use `--update-daemon` to update the daemon alone with no effect on intercepted connections.
## No Re-authentication
[Section titled “No Re-authentication”](#no-re-authentication)
Updating never re-enrolls the node: credentials and identity persist in `/var/lib/riptides`, and the configuration in `/etc/riptides/config.yaml` is preserved. No control plane URL or join token is needed to update.
## Kubernetes (Helm)
[Section titled “Kubernetes (Helm)”](#kubernetes-helm)
On Kubernetes the daemon runs from its Helm chart, not this installer, so update it with `helm upgrade` instead of `riptides-update.sh`. Reuse the same values file you installed with:
```bash
helm upgrade riptides-daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
-f daemon-values.yaml
```
The chart deploys a **DaemonSet**, so this performs a rolling update across nodes; on each node the **driver-loader init container reloads the kernel module** as the pod restarts.
Pin the chart with `--version ` (omit it to move to the latest chart). The kernel **driver** version is set separately by the `driverLoader.driverVersion` chart value - bump it in your values and re-run `helm upgrade`:
daemon-values.yaml
```yaml
driverLoader:
driverVersion: "v0.5.15"
```
See [Daemon on Kubernetes](../daemon-kubernetes) for the full chart reference and values.
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Uninstalling Riptides](../uninstall) - remove the daemon, driver, and services from a node.
# Guardrails for an AI Agent
This example walks through the full agentic workflow end to end. You bring a coding agent under Riptides, watch what it does, then lock it down to just the models and tools it should use, and confirm the guardrails work. The scenario uses a Claude Code agent (`claude`) that calls the Anthropic API and a Linear MCP connector; the same flow applies to Codex (`codex`).
## Scenario
[Section titled “Scenario”](#scenario)
```plaintext
┌──────────────────────────────┐
│ Riptides host │
│ │
you ─────────────▶ │ claude (AI agent) │
(drive the agent) │ │ │
│ ├──▶ Anthropic API (LLM) │
│ └──▶ Linear MCP (tools) │
└──────────────────────────────┘
observed + governed by Riptides
```
You will:
1. Confirm the agent is identified and its AI traffic is inspected.
2. Watch a session in the Activity Monitor.
3. Restrict the agent to specific models and tools.
4. (Optional) Scope stricter rules to a specific person.
5. Verify a blocked attempt and trace it back to the policy.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A Riptides daemon on the host where the agent runs. See [Getting Started](../../guides/getting-started).
* The agent defined as a workload identity with AI traffic inspection turned on. The easiest way is the [Identities](../../console/identities) screen in the console, where **TLS intercept** is on by default. The key setting is `connection.tls.intercept: true`, which lets Riptides decrypt and inspect the agent’s HTTP(S) calls. Traffic on the standard HTTP and HTTPS ports is evaluated automatically, so no separate flag is needed. As code it looks like this:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: claude
namespace: riptides-system
spec:
workloadID: claude
scope:
daemonGroup:
id: daemongroup/dev-eu-west-1/on-demand-workers
selectors:
- process:name: claude
connection:
tls:
mode: PERMISSIVE
intercept: true
```
With this in place, the agent’s calls to LLMs and MCP servers are observed and governed, with no changes to the agent itself.
## Step 1: Watch a session
[Section titled “Step 1: Watch a session”](#step-1-watch-a-session)
Run the agent as you normally would, then open **Agentic → [Activity Monitor](../../agentic/activity-monitor)**. Your run appears as a session. Open it and view the **graph**: you will see yourself as the caller, the `claude` agent, the models it used, and, if it called Linear, the `list_teams` or `search_issues` tools with the Linear service behind them.
This is your baseline. It shows exactly which models and tools the agent actually uses, which is what you will allow in the policy.
## Step 2: Decide the guardrails
[Section titled “Step 2: Decide the guardrails”](#step-2-decide-the-guardrails)
Suppose you want the agent, when running unattended, to:
* use **only** the Claude Haiku model on Anthropic (not the larger, more expensive models), and
* use **only** read-style Linear tools (`search_issues`, `list_teams`), never anything that creates or changes data.
You do that by adding Anthropic and Linear to the Autonomous Operation policy and narrowing each. Other providers or connectors you never add stay unrestricted for that policy scope.
## Step 3: Create and narrow the policy
[Section titled “Step 3: Create and narrow the policy”](#step-3-create-and-narrow-the-policy)
1. Open **Agentic → [Access Control](../../agentic/access-control)** and choose **Add policy**.
2. Select the `claude` workload identity and confirm. This creates an empty policy (full access) which you now narrow.
3. In the editor, select **Autonomous Operation** (the rules for the agent itself).
4. On the **LLM Models** tab, **Add restriction** for the Anthropic provider, expand it, and leave only **Claude Haiku** toggled on.
5. On the **Connectors** tab, **Add restriction** for the Linear connector, expand it, and leave only `search_issues` and `list_teams` toggled on.
6. Choose **Save**.
The dashboard now shows `claude` with its LLM and Connector counts and an **Autonomous: Restricted** badge.
The same result as YAML:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: TrafficPolicy
metadata:
name: claude-autonomous
namespace: riptides-system
spec:
workloadID: claude
llmRules:
- llmRef:
name: anthropic-api
models:
- claude-haiku-4-5-20251001
connectorRules:
- serverRef:
name: mcp-linear
tools:
- search_issues
- list_teams
```
## Step 4 (optional): Scope stricter rules to a person
[Section titled “Step 4 (optional): Scope stricter rules to a person”](#step-4-optional-scope-stricter-rules-to-a-person)
If you want different limits depending on who is driving the agent, add a **user** policy. In the editor choose **Restrict user**, pick the person from your [Users](../../agentic/users), and set their restrictions. Their rules apply only when they drive the agent. Autonomous runs still use only the Autonomous Operation policy from Step 3. Other users who do not have their own policy are **not** covered by Autonomous Operation; they keep full access until you add a user policy for them.
## Step 5: Verify the guardrails
[Section titled “Step 5: Verify the guardrails”](#step-5-verify-the-guardrails)
Run the agent again in a context the policy covers, for example unattended after Step 3, or as the restricted user after Step 4, and have it try something outside a restriction, such as a larger Anthropic model or creating a Linear issue. In the **Activity Monitor**:
* the **Blocked events** card goes up,
* the session is flagged, and
* the blocked model or tool node is tagged red in the graph.
Note the workload and who was driving, then open **Access Control** for that agent and select the matching Autonomous Operation or user policy to confirm or adjust the restriction.
## Security highlights
[Section titled “Security highlights”](#security-highlights)
* **No changes to the agent**: guardrails are applied to the agent’s traffic, not baked into its configuration or code.
* **Default allow, restrict by rule**: traffic is allowed unless you add a restriction for that provider or connector; then only the models and tools you leave on for that service are permitted.
* **Autonomous vs. human-driven**: Autonomous Operation and per-user policies are separate, with no fallback between them, so you must set each scope you care about.
* **Observable enforcement**: every block is visible in the Activity Monitor, so you can audit what was denied and reconcile it with the policy in Access Control.
## Next steps
[Section titled “Next steps”](#next-steps)
* [Controlling Agent Access](../../agentic/access-control): the full policy model.
* [Monitoring AI Activity](../../agentic/activity-monitor): read sessions and trace blocks.
* [Agentic AI Overview](../../agentic/overview): the building blocks and how they fit together.
# Connect AWS EC2 Nodes
This guide shows you how to connect AWS EC2 instances to Riptides using the AWSIID (AWS Instance Identity Document) verifier. With AWSIID, daemons authenticate automatically using the cryptographically signed instance identity document that every EC2 instance provides - no manual tokens required.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane (see [Getting Started](../getting-started))
* [`riptides-cli`](../../deployment/cli) configured to access the Riptides control plane
* One or more EC2 instances you want to connect
* The EC2 instances must be able to reach the control plane endpoint over the network
## How It Works
[Section titled “How It Works”](#how-it-works)
Every EC2 instance has access to an Instance Identity Document (IID) via the instance metadata service (IMDS). The Riptides daemon reads this document and presents it to the control plane during registration. The control plane verifies the document’s signature against AWS public certificates and checks that the instance metadata (account ID, region, etc.) matches the Verifier’s `requiredMetadata` constraints.
## Step 1: Create an AWSIID Verifier
[Section titled “Step 1: Create an AWSIID Verifier”](#step-1-create-an-awsiid-verifier)
Create a Verifier that accepts daemons presenting a valid AWS Instance Identity Document. Use `requiredMetadata` to restrict which AWS accounts are allowed to register:
verifier-awsiid.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: awsiid
namespace: riptides-system
spec:
AWSIID: {}
requiredMetadata:
- awsiid:account:id: "123456789012"
```
Apply it:
```bash
riptides-cli ctl apply -f verifier-awsiid.yaml
```
Confirm the Verifier is available:
```bash
riptides-cli ctl get verifiers
```
Expected output:
```plaintext
NAME STATE
awsiid Available
```
> **Security note:** Always set `requiredMetadata` with your AWS account ID to prevent instances in unauthorized accounts from registering daemons. You can add multiple entries to allow several accounts.
### Filtering by Multiple Accounts
[Section titled “Filtering by Multiple Accounts”](#filtering-by-multiple-accounts)
To allow instances from more than one AWS account:
```yaml
spec:
AWSIID: {}
requiredMetadata:
- awsiid:account:id: "123456789012"
- awsiid:account:id: "987654321098"
```
## Step 2: Create a DaemonGroup (Optional)
[Section titled “Step 2: Create a DaemonGroup (Optional)”](#step-2-create-a-daemongroup-optional)
A [DaemonGroup](../../reference/daemongroup) lets you organize daemons into logical groups based on OS or other metadata. This is useful for scoping WorkloadIdentity assignments to specific sets of nodes:
daemongroup-aws.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: DaemonGroup
metadata:
name: aws-linux-nodes
namespace: riptides-system
spec:
workloadID: daemongroup/aws-linux-nodes
selectors:
- linuxos:name: ubuntu
- linuxos:name: amazon
- linuxos:name: alpine
```
Apply it:
```bash
riptides-cli ctl apply -f daemongroup-aws.yaml
```
This group will automatically include any connected daemon running Ubuntu, Amazon Linux, or Alpine. You can later scope WorkloadIdentity resources to this group using the `scope.daemonGroup.id` field.
Choose the installation method that matches your infrastructure:
* **[Kubernetes](#kubernetes)** - deploy the daemon as a Helm chart into an existing cluster
* **[Virtual Machines / Bare Metal](#virtual-machines--bare-metal)** - configure the daemon installed via `.deb` or `.rpm` packages
## Kubernetes
[Section titled “Kubernetes”](#kubernetes)
**Additional prerequisites for Kubernetes:**
* Kubernetes cluster v1.26 or later
* [Helm](https://helm.sh/docs/intro/install/) v3.12 or later
### Daemon Configuration
[Section titled “Daemon Configuration”](#daemon-configuration)
When installing the daemon via Helm, set `authPlugin.type` to `AWSIID` and enable the `ec2` metadata collector so the daemon can read the Instance Identity Document from IMDS. Use the following `values.yaml` in place of the one shown in the getting-started guide:
daemon-values-aws.yaml
```yaml
config:
daemon:
metadataCollectors:
procfs:
enabled: true
linuxos:
enabled: true
ec2:
enabled: true
kubernetes:
enabled: true
kubeletHost: localhost
kubeletPort: 10250
kubeletCA: /etc/kubernetes/pki/ca.crt
skipKubeletVerification: true
credentials: /var/run/secrets/kubernetes.io/serviceaccount/token
controlPlane:
enabled: true
url: https://.console.riptides.io
authPlugin:
type: AWSIID
dataDir: /data/riptides
```
> **Note:** The `ec2` metadata collector must be enabled - the daemon reads the Instance Identity Document from `http://169.254.169.254/latest/dynamic/instance-identity/document` to authenticate with the control plane. The `trustDomain` must match the value configured on the control plane.
Then install with:
```bash
helm install daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
--create-namespace \
-f daemon-values-aws.yaml
```
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected)
After deploying the daemon, check that your EC2 nodes have registered:
```bash
riptides-cli ctl get daemons
```
You should see entries like:
```plaintext
NAME WORKLOAD-ID
a1b2c3d4-e5f6-7890-abcd-ef0123456789 riptides/daemon/123456789012/us-east-1/i-0123456789abcdef0
```
## Virtual Machines / Bare Metal
[Section titled “Virtual Machines / Bare Metal”](#virtual-machines--bare-metal)
### One-line install (recommended)
[Section titled “One-line install (recommended)”](#one-line-install-recommended)
Run the installer on each EC2 instance:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io
```
The script detects IMDS, selects AWSIID automatically, writes the config, and starts the daemon - no token required.
To force AWSIID explicitly (e.g. in user-data scripts where auto-detection timing matters):
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--awsiid
```
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected-1)
Confirm the daemon has registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see an entry like:
```plaintext
NAME WORKLOAD-ID STATE
a1b2c3d4-e5f6-7890-abcd-ef0123456789 riptides/daemon/123456789012/us-east-1/i-0123456789abcdef0 Connected
```
## How Authentication Happens
[Section titled “How Authentication Happens”](#how-authentication-happens)
When the daemon starts on an EC2 instance, it:
1. Retrieves the Instance Identity Document from the EC2 metadata service (`http://169.254.169.254/latest/dynamic/instance-identity/document`)
2. Sends the signed document to the Riptides control plane
3. The control plane verifies the document signature against AWS public certificates
4. The control plane checks that the instance’s account ID matches the Verifier’s `requiredMetadata`
5. On success, the daemon is registered and receives a workload ID in the format `riptides/daemon///` (for example, `riptides/daemon/123456789012/us-east-1/i-0123456789abcdef0`)
No tokens, no secrets to distribute - the EC2 instance’s own identity is the credential.
## Step 3: Assign Workload Identities
[Section titled “Step 3: Assign Workload Identities”](#step-3-assign-workload-identities)
Now that your EC2 nodes are connected, create WorkloadIdentity resources to assign SPIFFE identities to workloads running on those nodes. Scope identities to your DaemonGroup so they only apply to your AWS fleet:
workload-identity-aws.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-api-server
namespace: riptides-system
spec:
workloadID: my-app/api-server
scope:
daemonGroup:
id: daemongroup/aws-linux-nodes
selectors:
- process:name: api-server
k8s:pod:namespace: my-app
k8s:label:app: api-server
connection:
tls:
mode: PERMISSIVE
```
Apply it:
```bash
riptides-cli ctl apply -f workload-identity-aws.yaml
```
Any process named `api-server` running on a node in the `aws-linux-nodes` daemon group will receive the SPIFFE ID `spiffe://example.com/my-app/api-server`.
For full details on WorkloadIdentity configuration, see the [WorkloadIdentity reference](../../reference/workloadidentity).
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
| Symptom | Possible Cause | Resolution |
| -------------------------------------------------------- | --------------------------------- | ------------------------------------------------------------------------------------------------------------- |
| Daemon does not appear in `riptides-cli ctl get daemons` | Daemon cannot reach control plane | Verify network connectivity and security group rules between EC2 and the control plane endpoint |
| Daemon shows authentication error | Account ID mismatch | Check that the Verifier’s `requiredMetadata` includes the correct AWS account ID |
| Daemon shows authentication error | IMDS not accessible | Ensure IMDSv1 or IMDSv2 is enabled on the instance and the hop limit allows container access |
| DaemonGroup shows no daemons | Selector mismatch | Verify the `linuxos:name` selector matches the OS running on your instances (e.g., `amazon` for Amazon Linux) |
| VM daemon fails after config change | Stale process | Run `sudo systemctl restart riptides-daemon` and check `journalctl -u riptides-daemon` |
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Connect GCP Instances](../connect-gcp-nodes) - connect Google Cloud VMs using the GCPIIT verifier
* [WorkloadIdentity Reference](../../reference/workloadidentity) - full selector and TLS mode documentation
* [Verifier Reference](../../reference/verifier) - all verifier types and metadata filtering options
# Connect Azure VMs
This guide shows you how to connect Azure virtual machines to Riptides using the AzureIMDS (Azure Instance Metadata Service) verifier. With AzureIMDS, daemons authenticate automatically using the signed identity token provided by the Azure IMDS - no manual tokens required.
Choose the installation method that matches your infrastructure:
* **[Kubernetes](#kubernetes)** - deploy the daemon as a Helm chart into an existing cluster
* **[Virtual Machines](#virtual-machines)** - configure the daemon installed via the install script on Azure Linux VMs
Kernel module - VM type requirement
The Riptides kernel driver is a loadable kernel module. It can only be inserted on **standard Azure VMs** (Generation 1 and [Generation 2](https://learn.microsoft.com/en-us/azure/virtual-machines/generation-2) without Trusted Launch).
**[Trusted Launch VMs](https://learn.microsoft.com/en-us/azure/virtual-machines/trusted-launch)** with Secure Boot enabled block unsigned kernel modules from loading. If your VM has Trusted Launch / Secure Boot active, the `riptides-modules` service will fail to load the driver. Disable Secure Boot in the VM’s security configuration, or use a standard Generation 2 VM instead.
To check whether Secure Boot is enabled:
```bash
mokutil --sb-state
```
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane (see [Getting Started](../getting-started))
* [`riptides-cli`](../../deployment/cli) configured to access the Riptides control plane
* One or more Azure Linux VMs you want to connect
* The VMs must be able to reach the control plane endpoint over the network
* A [managed identity](https://learn.microsoft.com/en-us/azure/active-directory/managed-identities-azure-resources/overview) attached to each VM - **this is required and must be done before installing the daemon** (see below)
Managed identity is mandatory
The Riptides daemon authenticates to the control plane by requesting a signed identity token from the Azure Instance Metadata Service. Azure only issues this token to VMs that have a managed identity assigned. **Without a managed identity the daemon cannot authenticate and registration will fail.**
To attach a system-assigned managed identity:
```bash
az vm identity assign --name --resource-group
```
Or in the Azure portal: **VM → Identity → System assigned → On → Save**.
Takes effect immediately - no reboot required. Verify the identity is working before running the installer:
```bash
curl -s -H "Metadata: true" \
"http://169.254.169.254/metadata/identity/oauth2/token?api-version=2018-02-01&resource=https://management.azure.com/"
```
A successful response contains an `access_token` field. An `{"error":"invalid_request","error_description":"Identity not found"}` response means the managed identity is not yet attached.
## How It Works
[Section titled “How It Works”](#how-it-works)
Every Azure VM with a managed identity can request a signed identity token from the Azure Instance Metadata Service (IMDS) at `http://169.254.169.254/metadata/identity/oauth2/token`. The Riptides daemon retrieves this token and presents it to the control plane during registration. The control plane verifies the token signature using Microsoft’s public OIDC certificates and checks that the instance metadata (subscription ID, resource group, etc.) matches the Verifier’s `requiredMetadata` constraints.
## Step 1: Create an AzureIMDS Verifier
[Section titled “Step 1: Create an AzureIMDS Verifier”](#step-1-create-an-azureimds-verifier)
Create a Verifier that accepts daemons presenting a valid Azure managed identity token. Use `requiredMetadata` to restrict which Azure subscriptions are allowed to register:
verifier-azureimds.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: azureimds
namespace: riptides-system
spec:
AzureIMDS: {}
requiredMetadata:
- azureimds:subscription:id: "00000000-0000-0000-0000-000000000000"
```
Apply it:
```bash
riptides-cli ctl apply -f verifier-azureimds.yaml
```
Confirm the Verifier is available:
```bash
riptides-cli ctl get verifiers
```
Expected output:
```plaintext
NAME STATE
azureimds Available
```
> **Security note:** Always set `requiredMetadata` with your Azure subscription ID to prevent VMs from unauthorized subscriptions from registering daemons. You can add multiple entries to allow several subscriptions.
Finding your subscription ID
Run the following command with the [Azure CLI](https://learn.microsoft.com/en-us/cli/azure/install-azure-cli):
```bash
az account show --query id -o tsv
```
To list all subscriptions available to your account:
```bash
az account list --query "[].{Name:name, ID:id}" -o table
```
### Filtering by Multiple Subscriptions
[Section titled “Filtering by Multiple Subscriptions”](#filtering-by-multiple-subscriptions)
To allow VMs from more than one Azure subscription:
```yaml
spec:
AzureIMDS: {}
requiredMetadata:
- azureimds:subscription:id: "00000000-0000-0000-0000-000000000000"
- azureimds:subscription:id: "11111111-1111-1111-1111-111111111111"
```
## Step 2: Create a DaemonGroup (Optional)
[Section titled “Step 2: Create a DaemonGroup (Optional)”](#step-2-create-a-daemongroup-optional)
A [DaemonGroup](../../reference/daemongroup) lets you organize daemons into logical groups based on OS or other metadata, useful for scoping WorkloadIdentity assignments to your Azure fleet:
daemongroup-azure.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: DaemonGroup
metadata:
name: azure-linux-nodes
namespace: riptides-system
spec:
workloadID: daemongroup/azure-linux-nodes
selectors:
- linuxos:name: ubuntu
- linuxos:name: debian
- linuxos:name: fedora
```
Apply it:
```bash
riptides-cli ctl apply -f daemongroup-azure.yaml
```
This group will automatically include any connected daemon running Ubuntu, Debian, or Fedora. You can later scope WorkloadIdentity resources to this group using the `scope.daemonGroup.id` field.
## Kubernetes
[Section titled “Kubernetes”](#kubernetes)
**Additional prerequisites for Kubernetes:**
* Kubernetes cluster v1.26 or later
* [Helm](https://helm.sh/docs/intro/install/) v3.12 or later
### Daemon Configuration
[Section titled “Daemon Configuration”](#daemon-configuration)
When installing the daemon via Helm, set `authPlugin.type` to `AzureIMDS` and enable the `azure` metadata collector so the daemon can retrieve the identity token from the Azure IMDS. Use the following `values.yaml` in place of the one shown in the getting-started guide:
daemon-values-azure.yaml
```yaml
config:
daemon:
metadataCollectors:
procfs:
enabled: true
linuxos:
enabled: true
azure:
enabled: true
kubernetes:
enabled: true
kubeletHost: localhost
kubeletPort: 10250
kubeletCA: /etc/kubernetes/pki/ca.crt
skipKubeletVerification: true
credentials: /var/run/secrets/kubernetes.io/serviceaccount/token
controlPlane:
enabled: true
url: https://.console.riptides.io
authPlugin:
type: AzureIMDS
dataDir: /data/riptides
```
> **Note:** The `azure` metadata collector must be enabled - the daemon requests the identity token from `http://169.254.169.254/metadata/identity/oauth2/token` to authenticate with the control plane. The managed identity must be attached to the VM or node pool. The `trustDomain` must match the value configured on the control plane.
### Custom Resource
[Section titled “Custom Resource”](#custom-resource)
By default the daemon requests an identity token for the resource `https://management.azure.com/`, which must match the resource configured in your AzureIMDS Verifier. To use a different resource URI, set `authPlugin.resource` in your `values.yaml`:
```yaml
authPlugin:
type: AzureIMDS
resource: https://my-custom-resource.example.com/
```
### Nodes with Multiple Managed Identities
[Section titled “Nodes with Multiple Managed Identities”](#nodes-with-multiple-managed-identities)
When a node has more than one user-assigned managed identity attached, authentication needs the client id of the identity to use. This is common on AKS: the cluster’s kubelet identity (`-agentpool`) is attached to every node, and add-ons such as Azure Policy attach their own.
On AKS the daemon supplies it, reading the kubelet identity’s client id from the node’s Kubernetes Azure cloud provider config (`/etc/kubernetes/azure.json`, visible to the daemon at `/host/etc`). No configuration is needed.
Set `clientID` to authenticate as a different identity:
```yaml
authPlugin:
type: AzureIMDS
clientID: 00000000-0000-0000-0000-000000000000
```
To read the client id of an AKS cluster’s kubelet identity:
```bash
az aks show -g -n \
--query identityProfile.kubeletidentity.clientId -o tsv
```
`authPlugin.cloudConfigPath` overrides where the cloud provider config is read from. It defaults to the mounted host path in a DaemonSet and is unset elsewhere, so a plain Azure VM never looks for the file.
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected)
After deploying the daemon, check that your Azure nodes have registered:
```bash
riptides-cli ctl get daemons
```
You should see entries like:
```plaintext
NAME WORKLOAD-ID STATE
a1b2c3d4-e5f6-7890-abcd-e01234567890 riptides/daemon/my-subscription/my-resource-group/my-vm Connected
```
## Virtual Machines
[Section titled “Virtual Machines”](#virtual-machines)
### Step 1: Run the Installer
[Section titled “Step 1: Run the Installer”](#step-1-run-the-installer)
Run the install script with `--azureimds`. The script auto-detects Azure VMs, but you can pass the flag explicitly:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--azureimds
```
The script installs the kernel driver and daemon, writes `/etc/riptides/config.yaml` with `authPlugin.type: AzureIMDS`, and starts the `riptides` systemd service. The daemon authenticates automatically using the VM’s managed identity on first start.
> **Note:** The managed identity must be attached to the VM before running the installer. The `azure` metadata collector is enabled automatically by the daemon when `authPlugin.type` is `AzureIMDS`.
To follow live logs and confirm a successful AzureIMDS handshake:
```bash
sudo journalctl -u riptides -f
```
### Custom Resource
[Section titled “Custom Resource”](#custom-resource-1)
By default the daemon requests an identity token for the resource `https://management.azure.com/`, which must match the resource configured in your AzureIMDS Verifier. If you configured your Verifier with a different resource URI, pass it as an argument to `--azureimds`:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--azureimds https://my-custom-resource.example.com/
```
### Selecting a Managed Identity
[Section titled “Selecting a Managed Identity”](#selecting-a-managed-identity)
A VM with more than one user-assigned managed identity attached needs the client id of the identity to authenticate as. Pass `--azureimds-client-id`:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--azureimds \
--azureimds-client-id 00000000-0000-0000-0000-000000000000
```
A VM with one managed identity does not need it — the daemon authenticates as the identity attached to the VM. Without it on a VM with several, the daemon cannot get a token and never connects.
System-assigned identities take precedence
A VM carrying a system-assigned identity alongside user-assigned ones authenticates as the **system-assigned** one unless `--azureimds-client-id` names another, and the metadata the Verifier sees differs accordingly: a system-assigned identity reports `azureimds:instance:name`, a user-assigned one reports `azureimds:identity:name`. Check which your Verifier’s `requiredMetadata` matches on before adding an identity to a VM that is already connected.
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected-1)
Confirm the daemon has registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see an entry like:
```plaintext
NAME WORKLOAD-ID STATE
a1b2c3d4-e5f6-7890-abcd-e01234567890 riptides/daemon/my-subscription/my-resource-group/my-vm Connected
```
## How Authentication Happens
[Section titled “How Authentication Happens”](#how-authentication-happens)
When the daemon starts on an Azure VM, it:
1. Requests a signed identity token from the Azure IMDS (`http://169.254.169.254/metadata/identity/oauth2/token`)
2. Sends the token to the Riptides control plane
3. The control plane verifies the token signature using Microsoft’s public OIDC certificates
4. The control plane checks that the instance’s subscription ID matches the Verifier’s `requiredMetadata`
5. On success, the daemon is registered and receives a workload ID in the format `riptides/daemon///` (for example, `riptides/daemon/my-subscription/my-resource-group/my-vm`)
No tokens to distribute, no secrets to manage - the VM’s managed identity is the credential.
## Step 3: Assign Workload Identities
[Section titled “Step 3: Assign Workload Identities”](#step-3-assign-workload-identities)
Now that your Azure nodes are connected, create WorkloadIdentity resources to assign SPIFFE identities to workloads running on those VMs. Scope identities to your DaemonGroup so they only apply to your Azure fleet:
workload-identity-azure.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-backend-service
namespace: riptides-system
spec:
workloadID: my-app/backend-service
scope:
daemonGroup:
id: daemongroup/azure-linux-nodes
selectors:
- process:name: backend-service
connection:
tls:
mode: PERMISSIVE
```
Apply it:
```bash
riptides-cli ctl apply -f workload-identity-azure.yaml
```
Any process named `backend-service` running on a node in the `azure-linux-nodes` daemon group will receive the SPIFFE ID `spiffe://example.com/my-app/backend-service`.
For full details on WorkloadIdentity configuration, see the [WorkloadIdentity reference](../../reference/workloadidentity).
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
| Symptom | Possible Cause | Resolution |
| ------------------------------------------------------------------- | --------------------------------------------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------ |
| `riptides-modules` fails to load | [Trusted Launch](https://learn.microsoft.com/en-us/azure/virtual-machines/trusted-launch) / Secure Boot enabled | Disable Secure Boot in the VM’s security configuration, or switch to a standard Generation 2 VM |
| Daemon does not appear in `riptides-cli ctl get daemons` | Daemon cannot reach control plane | Verify network connectivity and firewall rules between the Azure VM and the control plane endpoint |
| Daemon shows authentication error | Subscription ID mismatch | Check that the Verifier’s `requiredMetadata` includes the correct Azure subscription ID |
| Daemon shows authentication error | No managed identity attached | Ensure the VM has a system-assigned or user-assigned managed identity configured in the Azure portal |
| `IMDS returned status 400: Multiple user assigned identities exist` | Several user-assigned identities on the VM or node pool, none selected | On AKS check the daemon can read `/etc/kubernetes/azure.json`; otherwise set `clientID` (Helm) or `--azureimds-client-id` (install script) |
| Daemon shows authentication error | IMDS not accessible | Confirm the VM can reach `http://169.254.169.254` (this is available by default on Azure VMs) |
| DaemonGroup shows no daemons | Selector mismatch | Verify the `linuxos:name` selector matches the OS running on your instances |
| VM daemon fails after config change | Stale process | Run `sudo systemctl restart riptides` and check `journalctl -u riptides` |
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Connect AWS EC2 Nodes](../connect-aws-nodes) - connect Amazon EC2 instances using the AWSIID verifier
* [Connect GCP Instances](../connect-gcp-nodes) - connect Google Cloud VMs using the GCPIIT verifier
* [WorkloadIdentity Reference](../../reference/workloadidentity) - full selector and TLS mode documentation
* [Verifier Reference](../../reference/verifier) - all verifier types and metadata filtering options
# Connect GCP Instances
This guide shows you how to connect Google Cloud Platform (GCP) VM instances to Riptides using the GCPIIT (GCP Instance Identity Token) verifier. With GCPIIT, daemons authenticate automatically using the instance identity token provided by the GCP metadata server - no manual tokens required.
Choose the installation method that matches your infrastructure:
* **[Kubernetes](#kubernetes)** - deploy the daemon as a Helm chart into an existing cluster
* **[Virtual Machines / Bare Metal](#virtual-machines--bare-metal)** - configure the daemon installed via `.deb` or `.rpm` packages
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane (see [Getting Started](../getting-started))
* [`riptides-cli`](../../deployment/cli) configured to access the Riptides control plane
* One or more GCP Compute Engine VM instances you want to connect
* The VM instances must be able to reach the control plane endpoint over the network
## How It Works
[Section titled “How It Works”](#how-it-works)
Every GCP VM instance can request a signed identity token from the GCP metadata server. The Riptides daemon retrieves this token and presents it to the control plane during registration. The control plane verifies the token signature using Google’s public OIDC certificates and checks that the instance metadata (project ID, zone, etc.) matches the Verifier’s `requiredMetadata` constraints.
The token includes an `audience` claim that the control plane validates, preventing tokens issued for other purposes from being used for daemon registration.
## Step 1: Create a GCPIIT Verifier
[Section titled “Step 1: Create a GCPIIT Verifier”](#step-1-create-a-gcpiit-verifier)
Create a Verifier that accepts daemons presenting a valid GCP Instance Identity Token. Set the `audience` field to a value that the daemon will request in its token, and use `requiredMetadata` to restrict which GCP projects are allowed to register:
verifier-gcpiit.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: gcpiit
namespace: riptides-system
spec:
GCPIIT:
audience: gcp-iit
requiredMetadata:
- gcpiit:project:id: "my-gcp-project-123"
```
Apply it:
```bash
riptides-cli ctl apply -f verifier-gcpiit.yaml
```
Confirm the Verifier is available:
```bash
riptides-cli ctl get verifiers
```
Expected output:
```plaintext
NAME STATE
gcpiit Available
```
> **Security note:** Always set `requiredMetadata` with your GCP project ID to prevent instances from unauthorized projects from registering daemons. The `audience` field adds an additional layer of verification, ensuring only tokens explicitly requested for Riptides authentication are accepted.
### Filtering by Multiple Projects
[Section titled “Filtering by Multiple Projects”](#filtering-by-multiple-projects)
To allow instances from more than one GCP project:
```yaml
spec:
GCPIIT:
audience: riptides-daemon-auth
requiredMetadata:
- gcpiit:project:id: "my-gcp-project-123"
- gcpiit:project:id: "my-gcp-project-456"
```
## Step 2: Create a DaemonGroup (Optional)
[Section titled “Step 2: Create a DaemonGroup (Optional)”](#step-2-create-a-daemongroup-optional)
A [DaemonGroup](../../reference/daemongroup) lets you organize daemons into logical groups based on OS or other metadata. This is useful for scoping WorkloadIdentity assignments to specific sets of nodes:
daemongroup-gcp.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: DaemonGroup
metadata:
name: gcp-linux-nodes
namespace: riptides-system
spec:
workloadID: daemongroup/gcp-linux-nodes
selectors:
- linuxos:name: ubuntu
- linuxos:name: fedora
- linuxos:name: alpine
```
Apply it:
```bash
riptides-cli ctl apply -f daemongroup-gcp.yaml
```
This group will automatically include any connected daemon running Ubuntu, Fedora, or Alpine. You can later scope WorkloadIdentity resources to this group using the `scope.daemonGroup.id` field.
## Kubernetes
[Section titled “Kubernetes”](#kubernetes)
Caution
Container-Optimized OS (COS) restricts kernel module loading by default, which the Riptides driver requires. On COS nodes, a privileged init step patches the node’s kernel command line and reboots the node once to apply the change. This only runs on nodes detected as COS and is a no-op on other distros.
**Additional prerequisites for Kubernetes:**
* Kubernetes cluster v1.26 or later
* [Helm](https://helm.sh/docs/intro/install/) v3.12 or later
### Daemon Configuration
[Section titled “Daemon Configuration”](#daemon-configuration)
When installing the daemon via Helm, set `authPlugin.type` to `GCPIIT` and enable the `gcp` metadata collector so the daemon can retrieve the instance identity token from the GCP metadata server. Use the following `values.yaml` in place of the one shown in the getting-started guide:
daemon-values-gcp.yaml
```yaml
config:
daemon:
metadataCollectors:
procfs:
enabled: true
linuxos:
enabled: true
gcp:
enabled: true
kubernetes:
enabled: true
kubeletHost: localhost
kubeletPort: 10250
kubeletCA: /etc/kubernetes/pki/ca.crt
skipKubeletVerification: true
credentials: /var/run/secrets/kubernetes.io/serviceaccount/token
controlPlane:
enabled: true
url: https://.console.riptides.io
authPlugin:
type: GCPIIT
audience: gcp-iit # must match the audience field in your GCPIIT Verifier
dataDir: /data/riptides
```
> **Note:** The `gcp` metadata collector must be enabled - the daemon requests the identity token from the GCP metadata server using the configured `audience` value to authenticate with the control plane. The `audience` value must match the `audience` field in your GCPIIT Verifier. If omitted, it defaults to `gcp-iit`.
Then install with:
```bash
helm install daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
--create-namespace \
-f daemon-values-gcp.yaml
```
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected)
After deploying the daemon, check that your GCP nodes have registered:
```bash
riptides-cli ctl get daemons
```
You should see entries like:
```plaintext
NAME WORKLOAD-ID STATE
b1c2d3e4-f5a6-7890-bcde-f01234567890 riptides/daemon/my-gcp-project-123/us-central1-a/1234567890123456789 Connected
```
## Virtual Machines / Bare Metal
[Section titled “Virtual Machines / Bare Metal”](#virtual-machines--bare-metal)
### One-line install (recommended)
[Section titled “One-line install (recommended)”](#one-line-install-recommended)
Run the installer on each GCP instance:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io
```
The script detects IMDS, selects GCPIIT automatically, writes the config, and starts the daemon - no token required.
To force GCPIIT explicitly (e.g. in user-data scripts where auto-detection timing matters):
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--gcpiit
```
### Custom Audience
[Section titled “Custom Audience”](#custom-audience)
By default the daemon requests an identity token with the audience `gcp-iit`, which must match the `audience` field in your GCPIIT Verifier. If you configured your Verifier with a different audience, pass it as an argument to `--gcpiit`:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--gcpiit my-custom-audience
```
### Verify the Daemon Connected
[Section titled “Verify the Daemon Connected”](#verify-the-daemon-connected-1)
Confirm the daemon has registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see an entry like:
```plaintext
NAME WORKLOAD-ID STATE
b1c2d3e4-f5a6-7890-bcde-f01234567890 riptides/daemon/my-gcp-project-123/us-central1-a/1234567890123456789 Connected
```
## How Authentication Happens
[Section titled “How Authentication Happens”](#how-authentication-happens)
When the daemon starts on a GCP VM, it:
1. Requests an identity token from the GCP metadata server (`http://metadata.google.internal/computeMetadata/v1/instance/service-accounts/default/identity?audience=riptides-daemon-auth`)
2. Sends the signed token to the Riptides control plane
3. The control plane verifies the token signature using Google’s public OIDC certificates
4. The control plane checks that the `audience` claim matches the Verifier’s configured audience
5. The control plane checks that the instance’s project ID matches the Verifier’s `requiredMetadata`
6. On success, the daemon is registered and receives a workload ID in the format `riptides/daemon///` (for example, `riptides/daemon/my-gcp-project-123/us-central1-a/1234567890123456789`)
No tokens to distribute, no secrets to manage - the VM’s own cloud identity is the credential.
## Step 3: Assign Workload Identities
[Section titled “Step 3: Assign Workload Identities”](#step-3-assign-workload-identities)
Now that your GCP nodes are connected, create WorkloadIdentity resources to assign SPIFFE identities to workloads running on those VMs. Scope identities to your DaemonGroup so they only apply to your GCP fleet:
workload-identity-gcp.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-backend-service
namespace: riptides-system
spec:
workloadID: my-app/backend-service
scope:
daemonGroup:
id: daemongroup/gcp-linux-nodes
selectors:
- process:name: backend-service
k8s:pod:namespace: my-app
k8s:label:app: backend-service
connection:
tls:
mode: PERMISSIVE
```
Apply it:
```bash
riptides-cli ctl apply -f workload-identity-gcp.yaml
```
Any process named `backend-service` running on a node in the `gcp-linux-nodes` daemon group will receive the SPIFFE ID `spiffe://example.com/my-app/backend-service`.
For full details on WorkloadIdentity configuration, see the [WorkloadIdentity reference](../../reference/workloadidentity).
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
| Symptom | Possible Cause | Resolution |
| -------------------------------------------------------- | --------------------------------- | -------------------------------------------------------------------------------------------------------------------- |
| Daemon does not appear in `riptides-cli ctl get daemons` | Daemon cannot reach control plane | Verify network connectivity and firewall rules between the GCP VM and the control plane endpoint |
| Daemon shows authentication error | Project ID mismatch | Check that the Verifier’s `requiredMetadata` includes the correct GCP project ID |
| Daemon shows authentication error | Audience mismatch | Ensure the `audience` in the Verifier matches the audience the daemon requests from the metadata server |
| Daemon shows authentication error | Metadata server not accessible | Confirm the VM can reach `http://metadata.google.internal` (this is available by default on GCP VMs) |
| DaemonGroup shows no daemons | Selector mismatch | Verify the `linuxos:name` selector matches the OS running on your instances (e.g., `ubuntu` for Ubuntu-based images) |
| VM daemon fails after config change | Stale process | Run `sudo systemctl restart riptides-daemon` and check `journalctl -u riptides-daemon` |
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Connect AWS EC2 Nodes](../connect-aws-nodes) - connect Amazon EC2 instances using the AWSIID verifier
* [WorkloadIdentity Reference](../../reference/workloadidentity) - full selector and TLS mode documentation
* [Verifier Reference](../../reference/verifier) - all verifier types and metadata filtering options
# Connect GitHub Actions Runners
This guide shows you how to connect GitHub Actions runners to Riptides using the `GitHubActions` verifier. Runners authenticate automatically using the signed OIDC token provided by GitHub Actions, with no join tokens or long-lived credentials required.
Ephemeral runners
GitHub Actions runners are destroyed after each job. Each run connects a new short-lived daemon that appears in `riptides-cli ctl get daemons` for the duration of the job. When the job finishes and the runner stops heart-beating, the daemon is marked **Phased out** (an expected end-of-life state, not a failure) and is automatically removed a short time later — no manual cleanup needed. This is expected behaviour.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane (see [Getting Started](../getting-started))
* [`riptides-cli`](../../deployment/cli) configured to access the Riptides control plane
* A GitHub repository or organisation whose workflows you want to connect
## How It Works
[Section titled “How It Works”](#how-it-works)
GitHub Actions provides every runner with an OIDC token issued by `https://token.actions.githubusercontent.com`. The Riptides daemon requests this token from the Actions token endpoint using the `ACTIONS_ID_TOKEN_REQUEST_URL` and `ACTIONS_ID_TOKEN_REQUEST_TOKEN` environment variables that GitHub injects automatically. The control plane verifies the token signature against GitHub’s public JWKS and checks the token’s claims against the Verifier’s `requiredMetadata` selectors - exactly like the AWS, GCP, and Azure verifiers do with instance metadata.
No managed identity, no cloud account, no secrets. The runner’s GitHub identity is the credential.
## Step 1: Create a GitHubActions Verifier
[Section titled “Step 1: Create a GitHubActions Verifier”](#step-1-create-a-githubactions-verifier)
Create a Verifier that accepts runners from your GitHub organisation. Scope it with `requiredMetadata` - a `githubactions:repository:owner` selector restricts authentication to your org only.
verifier-github-actions.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: github-actions
namespace: riptides-system
spec:
GitHubActions:
audience: riptides
requiredMetadata:
- githubactions:repository:owner: your-org
```
Apply it:
```bash
riptides-cli ctl apply -f verifier-github-actions.yaml
```
Confirm the Verifier is available:
```bash
riptides-cli ctl get verifiers
```
Expected output:
```plaintext
NAME STATE
github-actions Available
```
Always set requiredMetadata
Without `requiredMetadata`, a GitHub Actions Verifier would accept OIDC tokens from any repository across all of GitHub. `requiredMetadata` is enforced at admission time - the resource is rejected if omitted - so scoping to your org is mandatory.
### Narrowing to a Specific Repository, Environment, or Branch
[Section titled “Narrowing to a Specific Repository, Environment, or Branch”](#narrowing-to-a-specific-repository-environment-or-branch)
Add more selectors to a group to narrow further. A token must match **every** selector in a group to be accepted:
```yaml
spec:
GitHubActions:
audience: riptides
requiredMetadata:
- githubactions:repository:owner: your-org
githubactions:repository:full_name: your-org/deploy-service # only this repository
githubactions:environment: production # only the "production" GH environment
githubactions:ref: refs/heads/main # only the main branch
```
To trust several orgs or repositories, add multiple groups - a token matching **any** group is accepted:
```yaml
requiredMetadata:
- githubactions:repository:owner: org-a
- githubactions:repository:owner: org-b
```
## Step 2: Add the Action to Your Workflow
[Section titled “Step 2: Add the Action to Your Workflow”](#step-2-add-the-action-to-your-workflow)
Add the [`riptideslabs/setup-riptides`](https://github.com/riptideslabs/setup-riptides) action to your workflow. The job must have `id-token: write` permission so GitHub can issue an OIDC token.
```yaml
jobs:
deploy:
runs-on: ubuntu-latest
permissions:
id-token: write # required, allows GitHub to issue an OIDC token
contents: read
steps:
- uses: actions/checkout@v4
- uses: riptideslabs/setup-riptides@v1
with:
controlplane-url: https://.console.riptides.io
# From here the runner has a verified SPIFFE identity and all outbound
# connections are transparently mTLS-secured by the Riptides daemon.
- name: Deploy
run: ./deploy.sh
```
The action installs the kernel driver and daemon, runs `riptides daemon auth --plugin GitHubActions` to exchange the OIDC token for a SPIFFE x509 identity certificate, and starts the daemon as a systemd service.
To follow live logs during a run:
```bash
sudo journalctl -u riptides -f
```
### Pinning the Audience
[Section titled “Pinning the Audience”](#pinning-the-audience)
The `audience` input must match the `audience` field in your Verifier. The default for both is `riptides`.
```yaml
- uses: riptideslabs/setup-riptides@v1
with:
controlplane-url: https://.console.riptides.io
audience: my-custom-audience
```
```yaml
spec:
GitHubActions:
audience: my-custom-audience
requiredMetadata:
- githubactions:repository:owner: your-org
```
## Verify Runners Appear
[Section titled “Verify Runners Appear”](#verify-runners-appear)
After a workflow run, check that the runner daemon registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see an entry like:
```plaintext
NAME WORKLOAD-ID STATE
a1b2c3d4-e5f6-7890-abcd-e01234567890 riptides/daemon/your-org/your-org/deploy-service/CI Connected
```
The daemon will disappear from this list once the job finishes and the runner is destroyed.
## Step 3: Assign Workload Identities
[Section titled “Step 3: Assign Workload Identities”](#step-3-assign-workload-identities)
Create a WorkloadIdentity to assign a SPIFFE identity to processes running on your GitHub Actions runners. Scope it to the daemon’s workload ID so it only applies to runners from your repo:
workload-identity-github-actions.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: github-actions-deployer
namespace: riptides-system
spec:
workloadID: ci/github-actions/deployer
scope:
daemonGroup:
id: daemongroup/github-actions-runners
selectors:
- process:name: deploy.sh
connection:
tls:
mode: PERMISSIVE
```
Apply it:
```bash
riptides-cli ctl apply -f workload-identity-github-actions.yaml
```
For full details on WorkloadIdentity configuration, see the [WorkloadIdentity reference](../../reference/workloadidentity).
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
| Symptom | Possible Cause | Resolution |
| -------------------------------------------------------- | ------------------------------------------------------------------ | -------------------------------------------------------------------------------------------------------------------------------------- |
| `setup-riptides` step fails with authentication error | `id-token: write` permission missing | Add `permissions: id-token: write` to the job |
| Authentication error: `required metadata not satisfied` | Token claims don’t match any `requiredMetadata` group | Check the `githubactions:repository:owner` (and any other) selectors match the org/repo running the workflow |
| Authentication error: `audience mismatch` | Action `audience` input does not match Verifier’s `audience` field | Ensure both are set to the same value (default: `riptides`) |
| Runner joins from an unexpected repo | `requiredMetadata` too broad | Tighten the selectors (add `githubactions:repository:full_name`, `githubactions:ref`, etc.) |
| Daemon does not appear in `riptides-cli ctl get daemons` | Runner cannot reach control plane | Verify network connectivity from the runner to the control plane endpoint |
| Daemon shows “Phased out” then disappears after a job | Expected — runners are ephemeral | The daemon is auto-removed a short time after the runner stops heart-beating; “Phased out” is a normal end-of-life state, not an error |
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Connect AWS EC2 Nodes](../connect-aws-nodes)
* [Connect Azure VMs](../connect-azure-nodes)
* [Connect GCP Instances](../connect-gcp-nodes)
* [WorkloadIdentity Reference](../../reference/workloadidentity)
* [Verifier Reference](../../reference/verifier)
# Getting Started with Riptides
This guide walks you through connecting your first daemon and assigning a workload identity. Choose the installation method that matches your infrastructure:
* **[Virtual Machines / Bare Metal](#virtual-machines--bare-metal)** — install the daemon via a single script on any Linux host
* **[Kubernetes](#kubernetes)** — deploy the daemon as a Helm chart into an existing cluster
Both methods share the same control plane and use JoinToken authentication to register daemons.
Get a control plane first
You need a Riptides control plane before proceeding.
* **Free** — Register a free account at [console.riptides.io](https://console.riptides.io).
* **Production** — Contact .
Either way, you’ll receive a confirmation email to approve (link expires in 7 days), then a second email once deployment is complete containing your **control plane URL** and **trust domain**. The steps in this guide use those values.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
Before you begin, make sure you have [`riptides-cli`](../../deployment/cli) installed. It handles authentication to the Riptides-hosted control plane automatically via OIDC — no separate plugin required.
## Network Requirements
[Section titled “Network Requirements”](#network-requirements)
The daemon must reach the control plane on the following endpoints (all over HTTPS/TLS on port 443). Allow these in your firewall, security group, or egress policy before proceeding:
| Endpoint | Protocol | Purpose |
| ------------------------------------------ | -------- | ------------------------------------------------------------------- |
| `.console.riptides.io` | HTTPS | Primary API — `riptides-cli` commands and daemon registration |
| `grpc..console.riptides.io` | gRPCS | Information sync and streaming between the daemon and control plane |
| `tunnel..console.riptides.io` | TLS | Telemetry retrieval from the daemon (pull model) |
VM / Bare Metal: one click in the UI
Go to **Daemons** (`/ui/daemons`) and click **Attach Daemon**. The UI generates a pre-filled one-liner with your control plane URL and a fresh join token — copy it, paste it on your host, and press enter. No manual JoinToken setup needed; skip straight to the [Virtual Machines / Bare Metal](#virtual-machines--bare-metal) section.
## Step 1: Connect to the Hosted Control Plane
[Section titled “Step 1: Connect to the Hosted Control Plane”](#step-1-connect-to-the-hosted-control-plane)
The Riptides control plane is hosted and operated by Riptides. Log in to the control plane web UI at the URL provided in your access details email.
Free account: email code login
Free accounts authenticate via **email code** by default. When you first open the UI or run a `riptides-cli` command, Riptides emails a one-time code to the address you registered with — enter it to log in. This is only pre-configured for the registering user’s email. To add team members or switch to GitHub / Google / Entra login, follow the [OIDC and Identity Provider Setup](/guides/oidc-setup/) guide.
Add a context for the control plane:
```bash
riptides-cli context add --url https://.console.riptides.io
```
This opens a browser window for authentication. After authenticating, the token is cached and subsequent commands will not require re-authentication until it expires.
Verify connectivity:
```bash
riptides-cli context status
```
> **Note:** See the [Control Plane](../../deployment/control-plane) page for more details on the hosted control plane architecture.
## Step 2: Create a JoinToken Verifier
[Section titled “Step 2: Create a JoinToken Verifier”](#step-2-create-a-jointoken-verifier)
A Verifier tells the control plane which authentication methods it should accept from daemons. Start with the `joinToken` verifier for a simple token-based flow. This step applies to both Kubernetes and VM/bare metal daemons:
verifier-jointoken.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: jointoken
namespace: riptides-system
spec:
joinToken: {}
```
Apply it:
```bash
riptides-cli ctl apply -f verifier-jointoken.yaml
```
Confirm the Verifier is available:
```bash
riptides-cli ctl get verifiers
```
Expected output:
```plaintext
NAME STATE
jointoken Available
```
## Step 3: Create a JoinToken
[Section titled “Step 3: Create a JoinToken”](#step-3-create-a-jointoken)
Create a JoinToken resource that the daemon will present during registration. Set `token` to a strong, unique value and give the token a `workloadID` and an expiration time:
jointoken.yaml
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: JoinToken
metadata:
name: my-first-daemon-token
namespace: riptides-system
spec:
token: "my-secure-join-token"
workloadID: "riptides/daemon/my-first-node"
expireAt: "2026-12-31T23:59:59Z"
```
Apply it:
```bash
riptides-cli ctl apply -f jointoken.yaml
```
> **Tip:** Rotate join tokens regularly and set short expiration windows in production environments.
## Virtual Machines / Bare Metal
[Section titled “Virtual Machines / Bare Metal”](#virtual-machines--bare-metal)
The installer detects your distribution and kernel version, downloads the right packages, writes the daemon configuration, and starts the systemd service.
Run on the host, not in a container
This installer runs natively on VMs and bare-metal: it loads the kernel module and manages systemd services on the host, so it detects containers (Docker, LXC, Podman, systemd-nspawn, …) and stops with an error. To run the daemon **in a container**, use Kubernetes with the [Helm chart](#kubernetes) — there a privileged init container loads the module onto the node while the daemon runs in a pod. (The kernel module always lives in the host/node kernel, never inside a container.)
Just want a local test VM?
On macOS or Linux you can bring up a throwaway Riptides node in one command with [Lima](https://lima-vm.io/) and the ready-made template — no manual install inside the VM:
```bash
limactl start --name=riptides \
--param controlplaneUrl="https://.console.riptides.io" \
--param token="" \
github:riptideslabs/lima-templates/templates/riptides
```
You can also copy this command **ready to use** — with the control plane URL and a join token already filled in — from **Daemons → Attach Daemon**, then the **Lima** tab.
See [Local Development with Lima](../../deployment/daemon-bare-metal#local-development-with-lima) for details.
### Step 1: Run the Installer
[Section titled “Step 1: Run the Installer”](#step-1-run-the-installer)
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--join-token ""
```
#### EC2 / AWSIID
[Section titled “EC2 / AWSIID”](#ec2--awsiid)
On EC2, the script auto-detects the instance and authenticates using the AWS Instance Identity Document — no join token required:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io
```
Pass `--awsiid` explicitly if auto-detection does not trigger (e.g. when IMDSv2 is restricted).
#### Azure VMs
[Section titled “Azure VMs”](#azure-vms)
On Azure, the script auto-detects the instance and authenticates using the Azure Instance Metadata Service — no join token required. The VM must have a [managed identity](https://learn.microsoft.com/en-us/azure/active-directory/managed-identities-azure-resources/overview) attached:
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io
```
Pass `--azureimds` explicitly if auto-detection does not trigger. See [Connect Azure VMs](../connect-azure-nodes) for the required Verifier setup.
### Supported Platforms
[Section titled “Supported Platforms”](#supported-platforms)
| Distribution | Package |
| ------------------------------------ | ------- |
| Ubuntu, Debian | `.deb` |
| RHEL, CentOS, Rocky Linux, AlmaLinux | `.rpm` |
| Amazon Linux 2023 | `.rpm` |
| Fedora | `.rpm` |
Packages are built for `amd64` and `arm64`. The installer picks the right one automatically.
### Options
[Section titled “Options”](#options)
| Flag | Default | Description |
| -------------------------- | ---------------------- | ---------------------------------------------------------------------------------------------------------------------------- |
| `--controlplane-url URL` | — | Control plane URL (**required**) |
| `--join-token TOKEN` | — | Join token for daemon authentication |
| `--awsiid` | auto-detected on EC2 | Use AWS Instance Identity Document auth |
| `--azureimds` | auto-detected on Azure | Use Azure Instance Metadata Service auth |
| `--daemon-version VERSION` | `latest` | Daemon version to install (e.g. `v0.5.12`) |
| `--driver-version VERSION` | `latest` | Driver version to install (e.g. `v0.5.15`) |
| `--data-dir DIR` | `/var/lib/riptides` | Directory for daemon state and certificates |
| `--wait-ready` | off | Block until the daemon is connected and a workload identity is issued, so traffic started right after install is intercepted |
| `--wait-timeout SECONDS` | `120` | Readiness timeout, with `--wait-ready` |
#### Pinning versions
[Section titled “Pinning versions”](#pinning-versions)
```bash
curl -fsSL https://docs.riptides.io/install.sh | sudo bash -s -- \
--controlplane-url https://.console.riptides.io \
--join-token "" \
--daemon-version v0.5.12 \
--driver-version v0.5.15
```
The daemon and driver are versioned independently. Omit either flag to use the latest release of that component.
To update the daemon or driver on an already-installed node, see [Updating Riptides](../../deployment/update).
### What the script does
[Section titled “What the script does”](#what-the-script-does)
1. If Riptides is already installed and the driver is present, starts the daemon service if it is not running and prints a status summary. No reinstallation is performed — to update in place, see [Updating Riptides](../../deployment/update).
2. Detects your distribution (Debian/Ubuntu → `.deb`, RHEL/Amazon Linux/Fedora → `.rpm`), architecture, and running kernel version.
3. Downloads and installs the kernel driver loader from [riptides-packages/driver-loader](https://github.com/riptides-packages/driver-loader/releases). The loader downloads the pre-built driver package for your kernel and loads it via the `riptides-modules` systemd unit. If no pre-built package exists for your kernel, the loader queues a remote build and the script streams its output while waiting — this can take up to 30 minutes.
4. Downloads and installs the daemon package from [riptides-packages/daemon](https://github.com/riptides-packages/daemon/releases).
5. Writes `/etc/riptides/config.yaml` (mode `0600`, owned by `root`) with the control plane URL, trust domain, and auth plugin configuration.
6. Enables and starts the `riptides` systemd service. The daemon authenticates to the control plane on first start using the configured join token, AWSIID, or AzureIMDS.
### Step 2: Verify the Daemon Connected
[Section titled “Step 2: Verify the Daemon Connected”](#step-2-verify-the-daemon-connected)
Once the daemon is running, confirm it has registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see your VM daemon listed with its workload ID:
```plaintext
NAME WORKLOAD ID
e2140516-678a-419d-9a4c-156e971583ae riptides/daemon/my-first-node
```
The `WORKLOAD ID` will match the `workloadID` specified in the JoinToken.
## Kubernetes
[Section titled “Kubernetes”](#kubernetes)
Follow this section to install the Riptides daemon as a Helm chart on an existing Kubernetes cluster.
**Additional prerequisites for Kubernetes:**
* Kubernetes cluster v1.26 or later
* [Helm](https://helm.sh/docs/intro/install/) v3.12 or later
### Step 1: Deploy the Daemon
[Section titled “Step 1: Deploy the Daemon”](#step-1-deploy-the-daemon)
Install the Riptides daemon using Helm. The daemon connects back to the control plane using the join token you created.
Caution
Replace `https://.console.riptides.io` with your actual control plane URL (e.g. `https://db16a6be.console.riptides.io`) provided in the access details email.
```bash
helm install daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
--create-namespace \
--set config.daemon.controlPlane.enabled=true \
--set config.daemon.controlPlane.url=https://.console.riptides.io \
--set config.daemon.controlPlane.authPlugin.type=joinToken \
--set config.daemon.controlPlane.authPlugin.config.token=my-secure-join-token
```
Alternatively, create a `values.yaml` file for the daemon:
daemon-values.yaml
```yaml
config:
daemon:
controlPlane:
enabled: true
url: https://.console.riptides.io
authPlugin:
type: joinToken
config:
token: my-secure-join-token
dataDir: /data/riptides
```
Then install with:
```bash
helm install daemon oci://ghcr.io/riptides-packages/helm/daemon \
--namespace riptides-system \
--create-namespace \
-f daemon-values.yaml
```
### Step 2: Verify the Daemon Connected
[Section titled “Step 2: Verify the Daemon Connected”](#step-2-verify-the-daemon-connected-1)
Once the daemon pod is running, check that it has registered with the control plane:
```bash
riptides-cli ctl get daemons
```
You should see your daemon listed with its workload ID:
```plaintext
NAME WORKLOAD ID
e2140516-678a-419d-9a4c-156e971583ae riptides/daemon/my-first-node
```
The `WORKLOAD ID` will match the `workloadID` specified in the JoinToken. If the daemon does not appear, check the daemon pod logs for connection errors.
## Assigning Identities to Workloads
[Section titled “Assigning Identities to Workloads”](#assigning-identities-to-workloads)
### Step 1: Create Your First WorkloadIdentity
[Section titled “Step 1: Create Your First WorkloadIdentity”](#step-1-create-your-first-workloadidentity)
A [WorkloadIdentity](../../reference/workloadidentity) assigns a SPIFFE identity to processes that match a set of selectors. The following example assigns an identity to an Nginx process running in a specific Kubernetes namespace. The same resource type is used regardless of whether the daemon is running on Kubernetes or a VM.
workload-identity.yaml
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: nginx-web
namespace: riptides-system
spec:
workloadID: my-app/web/nginx
selectors:
- process:name: nginx
k8s:pod:namespace: my-app
k8s:label:app: nginx
connection:
tls:
mode: PERMISSIVE
```
Apply it:
```bash
riptides-cli ctl apply -f workload-identity.yaml
```
This WorkloadIdentity will issue the SPIFFE ID `spiffe://example.com/my-app/web/nginx` to any process named `nginx` in a pod labeled `app: nginx` within the `my-app` namespace.
**Selector Reference**
Selectors identify which processes receive the identity. Common selector keys include:
| Selector | Description |
| -------------------- | ------------------------------------ |
| `process:name` | Name of the running process binary |
| `k8s:pod:namespace` | Kubernetes namespace the pod runs in |
| `k8s:label:` | Value of a Kubernetes pod label |
| `k8s:container:name` | Name of the Kubernetes container |
For the full list of available selectors, see the [WorkloadIdentity reference](../../reference/workloadidentity).
**TLS Modes**
The `connection.tls.mode` field controls how TLS is enforced for the workload:
| Mode | Description |
| ------------ | --------------------------------------------------------------------- |
| `SIMPLE` | One-way TLS — the workload presents its certificate to clients |
| `MUTUAL` | Mutual TLS — both sides present and verify certificates |
| `PERMISSIVE` | Accepts both plaintext and mTLS connections (useful during migration) |
### Step 2: Verify the Identity Was Assigned
[Section titled “Step 2: Verify the Identity Was Assigned”](#step-2-verify-the-identity-was-assigned)
After applying the WorkloadIdentity, verify that the control plane has matched it against running workloads:
```bash
riptides-cli ctl get workloadidentities
```
You should see the `nginx-web` identity listed. If the daemon is running on a node where an Nginx process matches the selectors, the identity will be assigned and a SPIFFE ID issued.
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
### Authentication failed
[Section titled “Authentication failed”](#authentication-failed)
The daemon logs will show the reason. Common causes:
* **Join token expired or not applied** — confirm `riptides-cli ctl get jointokens` shows the token and that `expireAt` has not passed. Generate a new one and update `/etc/riptides/config.yaml` (VM) or your Helm values (Kubernetes), then restart the daemon:
```bash
sudo systemctl restart riptides
```
* **Wrong control plane URL** — verify it matches exactly what was provided after signup.
* **Outbound connectivity blocked** — the daemon needs access to `.console.riptides.io` and `grpc..console.riptides.io` over HTTPS:
```bash
curl -v https://.console.riptides.io/healthz
```
Driver build queued for your kernel
If no pre-built driver package exists for your kernel, the driver loader automatically queues a remote build and the install script streams the build output while waiting — this is expected and can take up to 30 minutes. The script continues once the build completes and the module is loaded.
If the build fails or times out, check the loader logs:
```bash
sudo journalctl -u riptides-driver-loader -n 50 --no-pager
```
Contact if the build consistently fails for your kernel.
### Service fails to start (VM / bare metal)
[Section titled “Service fails to start (VM / bare metal)”](#service-fails-to-start-vm--bare-metal)
```bash
sudo systemctl status riptides
sudo journalctl -u riptides -n 50 --no-pager
```
Common causes:
* **YAML syntax error** in `/etc/riptides/config.yaml`:
```bash
python3 -c "import yaml; yaml.safe_load(open('/etc/riptides/config.yaml'))"
```
* **Kernel module not loaded** — check `lsmod | grep riptides` and `sudo systemctl status riptides-modules`.
* **Port blocked** — the daemon needs outbound HTTPS/TLS access (port 443) to `.console.riptides.io` and `grpc..console.riptides.io`.
### Daemon pod in `CrashLoopBackOff` (Kubernetes)
[Section titled “Daemon pod in CrashLoopBackOff (Kubernetes)”](#daemon-pod-in-crashloopbackoff-kubernetes)
Check the pod logs for the root cause:
```bash
kubectl logs -n riptides-system -l app.kubernetes.io/name=daemon --previous
```
Common causes:
* **Image pull failure** — the `regcred` pull secret may be missing or the GHCR token has expired. Re-create it and restart the pod.
* **Wrong control plane URL** — double-check the URL matches exactly what was provided after signup.
### Daemon does not appear in `riptides-cli ctl get daemons`
[Section titled “Daemon does not appear in riptides-cli ctl get daemons”](#daemon-does-not-appear-in-riptides-cli-ctl-get-daemons)
The pod may be running but failing to register with the control plane. Check live logs:
```bash
kubectl logs -n riptides-system -l app.kubernetes.io/name=daemon -f
```
Common causes:
* **JoinToken expired or not applied** — confirm `riptides-cli ctl get jointokens` shows the token and that `expireAt` has not passed.
* **Outbound access blocked** — verify the daemon node can reach `.console.riptides.io` and `grpc..console.riptides.io`.
### `riptides-cli` does not open a browser
[Section titled “riptides-cli does not open a browser”](#riptides-cli-does-not-open-a-browser)
The OIDC login flow requires a desktop browser. On headless machines, `riptides-cli` will print a URL to open manually. If your environment blocks outbound OAuth redirects, check the [console.riptides.io](https://console.riptides.io) dashboard for alternative authentication options.
***
## Next Steps
[Section titled “Next Steps”](#next-steps)
* [Connect AWS Nodes](../connect-aws-nodes) — use the AWSIID verifier for automatic, token-free daemon authentication on AWS
* [Connect GCP Instances](../connect-gcp-nodes) — use the GCPIIT verifier for automatic daemon authentication on GCP
* [mTLS Between Services](../mtls-between-services) — enforce mutual TLS between your first two workloads
* [WorkloadIdentity Reference](../../reference/workloadidentity) — full API specification for WorkloadIdentity resources
* [Verifier Reference](../../reference/verifier) — all supported verifier types and their configuration
# GitHub API Access
This guide shows how to store a GitHub Personal Access Token in a Kubernetes Secret and have Riptides inject it transparently into outbound requests to `api.github.com` - including calls made by the `gh` CLI - with no token management in the workload.
## Overview
[Section titled “Overview”](#overview)
Accessing the GitHub API or running `gh` CLI commands from a workload traditionally requires embedding a token in environment variables, mounted files, or application configuration. With Riptides, you can instead:
1. Store your GitHub PAT in a Kubernetes Secret.
2. Create a WorkloadIdentity that assigns a SPIFFE identity to the workload and enables TLS intercept for outbound connections.
3. Create a CredentialSource that references the Secret.
4. Create a CredentialBinding that tells the kernel to inject `Authorization: Bearer ` into outbound connections to `api.github.com`.
Your application code and `gh` CLI invocations make plain, unauthenticated requests. The Riptides kernel module intercepts each outbound connection to `api.github.com`, terminates TLS, injects the credential, and re-originates the connection to GitHub.
***
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane with minimum one daemon deployed
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
* A GitHub Personal Access Token with the scopes your workload requires (e.g., `repo`, `read:org`)
* `gh`, the GitHub CLI
***
## Step 1: Create a Kubernetes Secret
[Section titled “Step 1: Create a Kubernetes Secret”](#step-1-create-a-kubernetes-secret)
Store your GitHub PAT in a Kubernetes Secret in the `riptides-system` namespace.
```bash
riptides-cli ctl create secret generic github-pat \
--from-literal=token='' \
-n riptides-system
```
> **Security note:** The Secret lives in the `riptides-system` namespace. Access is mediated through CredentialSource and CredentialBinding resources - the workload never directly accesses the Secret.
***
## Step 2: Create a WorkloadIdentity
[Section titled “Step 2: Create a WorkloadIdentity”](#step-2-create-a-workloadidentity)
The WorkloadIdentity must exist before other resources that reference its `workloadID`. It assigns a SPIFFE identity to the workload and enables TLS intercept for outbound connections so the kernel can inject credentials.
First, find the daemon running on the host:
```bash
riptides-cli ctl get daemons
```
Retrieve its ID:
```bash
riptides-cli ctl get daemon -o jsonpath='{.spec.workloadID}'
```
Use that value in the `scope.daemon.id` field below:
```bash
riptides-cli ctl apply -f - <"
selectors:
- process:name: gh
workloadID: "gh-cli"
EOF
```
Key field:
* **`connection.tls.intercept: true`**: The kernel intercepts outbound TLS connections and handles credential injection. Required for the `injection` propagation mode to work.
***
## Step 3: Create a CredentialSource
[Section titled “Step 3: Create a CredentialSource”](#step-3-create-a-credentialsource)
The CredentialSource tells Riptides where to find the credential and how to treat it.
```bash
riptides-cli ctl apply -f - <`. The workload does not set any authentication headers.
***
## Step 6: Configure the Riptides CA Bundle
[Section titled “Step 6: Configure the Riptides CA Bundle”](#step-6-configure-the-riptides-ca-bundle)
Because `tls.intercept: true` causes the kernel to terminate and re-originate TLS, processes need to trust the Riptides CA. The daemon automatically merges the intercept CA into the OS trust store, so on most hosts no extra configuration is needed.
In containers or environments where the OS trust store is not updated by the daemon, you will need to point your runtime at the Riptides CA file. `gh` is written in Go and uses the OS trust store - in containers, `SSL_CERT_FILE` covers it alongside other Go-based tools.
See [Trusting the Riptides CA](../../concepts/kernel-module/#trusting-the-riptides-ca-for-tls-intercept) for the full list of runtime-specific environment variables.
***
## Step 7: Use the Credential
[Section titled “Step 7: Use the Credential”](#step-7-use-the-credential)
Your workload makes plain, unauthenticated requests - no token handling in the application or script. The kernel intercepts each connection to `api.github.com` and injects the credential automatically.
### `gh` CLI
[Section titled “gh CLI”](#gh-cli)
`gh` requires `GH_TOKEN` to be set to a non-empty value before it will make API requests. Export a placeholder so `gh` proceeds - Riptides replaces it on the wire:
```bash
export GH_TOKEN=.
```
Then make API calls as normal:
```bash
gh api gists
```
The kernel intercepts `gh`’s outbound connection to `api.github.com`, strips the placeholder, injects the real PAT, and re-originates the TLS session to GitHub. The `gh` process never sees the token.
### HTTP libraries and curl
[Section titled “HTTP libraries and curl”](#http-libraries-and-curl)
```python
import requests
# No Authorization header - the Riptides kernel module injects it
response = requests.get("https://api.github.com/user/repos")
print(response.json())
```
```bash
# No -H flags needed
curl https://api.github.com/user
```
***
## Dynamic Tokens
[Section titled “Dynamic Tokens”](#dynamic-tokens)
Want short-lived, automatically-rotating tokens?
GitHub Apps installation tokens expire after one hour and can be generated programmatically - no manual rotation needed. To use them with Riptides, configure a token controller that exchanges the GitHub App private key for an installation token and writes it to the Kubernetes Secret referenced by the CredentialSource. Riptides will pick up the updated secret on the next refresh cycle.
For a fully automated approach where a secrets manager handles the rotation, see the [Vault Integration](./vault-integration) guide - Vault’s dynamic secrets engine can vend short-lived tokens and push them through Riptides automatically.
# Kubernetes Secret-Based Bearer Tokens
This guide shows how to store API keys in Kubernetes Secrets and have Riptides deliver them transparently to workloads as `Authorization: Bearer` headers - no application code changes required.
## Overview
[Section titled “Overview”](#overview)
Many external APIs (LLM providers, SaaS platforms, internal services) authenticate requests using bearer tokens passed in the `Authorization` header. Traditionally, applications read these tokens from environment variables or mounted files. With Riptides, you can instead:
1. Store the API key in a standard Kubernetes Secret.
2. Create a CredentialSource that references the Secret.
3. Create a CredentialBinding that tells the kernel which outbound traffic should receive the token.
4. The Riptides kernel automatically adds the `Authorization: Bearer ` header to matching requests.
Your application code makes plain HTTP/HTTPS requests to the API. The kernel intercepts them and injects the credential before the request leaves the node.
***
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane with daemons deployed
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
* An API key for the external service you want to call
***
## Step 1: Create a Kubernetes Secret
[Section titled “Step 1: Create a Kubernetes Secret”](#step-1-create-a-kubernetes-secret)
Store your API key in a standard Kubernetes Secret in the `riptides-system` namespace.
```bash
riptides-cli ctl create secret generic my-api-key \
--from-literal=token='' \
-n riptides-system
```
Or as YAML:
```yaml
apiVersion: v1
kind: Secret
metadata:
name: my-api-key
namespace: riptides-system
type: Opaque
stringData:
token: ""
```
```bash
riptides-cli ctl apply -f secret.yaml
```
> **Security note:** The Secret lives in the `riptides-system` namespace, not in your application namespace. Access is mediated through CredentialSource and CredentialBinding resources, so the workload never directly accesses the Secret.
***
## Step 2: Create a CredentialSource
[Section titled “Step 2: Create a CredentialSource”](#step-2-create-a-credentialsource)
The CredentialSource tells Riptides where to find the credential and what type it is.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: my-api-bearer
namespace: riptides-system
spec:
kubernetes:
secretRef:
key: token
name: my-api-key
type: BearerToken
```
**Field reference:**
| Field | Description |
| ---------------- | -------------------------------------------------------------------------------------------------- |
| `secretRef.name` | Name of the Kubernetes Secret. |
| `secretRef.key` | Key within the Secret that holds the token value. |
| `type` | Credential type. `BearerToken` means Riptides will inject it as an `Authorization: Bearer` header. |
```bash
riptides-cli ctl apply -f credentialsource.yaml
```
Verify:
```bash
riptides-cli ctl get credentialsource my-api-bearer
# STATE should show AVAILABLE
```
***
## Step 3: Create an External Service
[Section titled “Step 3: Create an External Service”](#step-3-create-an-external-service)
Define a Riptides Service for the external API endpoint. This tells Riptides which destination addresses should be considered part of this service.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: my-api-svc
namespace: riptides-system
spec:
addresses:
- address: api.example.com
port: 443
external: true
labels:
api: my-api
```
Key fields:
* **`external: true`**: Marks this as an external service (not running inside the cluster).
* **`labels`**: Used by CredentialBinding injection selectors and WorkloadIdentity egress selectors to match traffic to this service.
```bash
riptides-cli ctl apply -f service.yaml
```
***
## Step 4: Create a CredentialBinding
[Section titled “Step 4: Create a CredentialBinding”](#step-4-create-a-credentialbinding)
The CredentialBinding connects the CredentialSource to a specific workload and defines how the credential is delivered.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: my-workload-api-access
namespace: riptides-system
spec:
credentialSource: my-api-bearer
propagation:
injection:
selectors:
- api: my-api
workloadID: "my-namespace/app/my-workload"
```
**How injection works:**
* The `selectors` match against Service labels. The daemon evaluates the connection context and determines which services should receive the credential. When the workload makes an outbound connection to a Service with label `api: my-api`, the kernel injects the `Authorization: Bearer ` header.
* The workload does not need to know about the token at all. It simply makes requests to `https://api.example.com`.
```bash
riptides-cli ctl apply -f credentialbinding.yaml
```
Verify:
```bash
riptides-cli ctl get credentialbinding my-workload-api-access
# STATE should show OK
```
***
## Step 5: Create a WorkloadIdentity with Egress
[Section titled “Step 5: Create a WorkloadIdentity with Egress”](#step-5-create-a-workloadidentity-with-egress)
The WorkloadIdentity assigns a SPIFFE identity to your workload and enables TLS intercept for outbound connections. The CredentialBinding created in the previous step controls which services receive the credential via its `propagation.injection.selectors`.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-workload
namespace: riptides-system
spec:
connection:
tls:
mode: PERMISSIVE
intercept: true
scope:
daemonGroup:
id: "/"
selectors:
- k8s:label:app: my-workload
k8s:pod:namespace: my-namespace
process:name: node
workloadID: "my-namespace/app/my-workload"
```
Key fields:
* **`connection.tls.intercept: true`**: The kernel intercepts outbound connections and handles TLS + credential injection.
* **`selectors`**: Identifies which processes on which pods receive this identity.
```bash
riptides-cli ctl apply -f workloadidentity.yaml
```
***
## Complete Example: Calling an LLM API
[Section titled “Complete Example: Calling an LLM API”](#complete-example-calling-an-llm-api)
Here is a full working example for calling an LLM provider’s API.
### Secret
[Section titled “Secret”](#secret)
```yaml
apiVersion: v1
kind: Secret
metadata:
name: llm-api-key
namespace: riptides-system
type: Opaque
stringData:
token: ""
```
### CredentialSource
[Section titled “CredentialSource”](#credentialsource)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: llm-bearer
namespace: riptides-system
spec:
kubernetes:
secretRef:
key: token
name: llm-api-key
type: BearerToken
```
### Service
[Section titled “Service”](#service)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: llm-api-svc
namespace: riptides-system
spec:
addresses:
- address: api.llm-provider.com
port: 443
external: true
labels:
api: llm-provider
```
### CredentialBinding
[Section titled “CredentialBinding”](#credentialbinding)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: assistant-llm-access
namespace: riptides-system
spec:
credentialSource: llm-bearer
propagation:
injection:
selectors:
- api: llm-provider
workloadID: "my-namespace/app/assistant-api"
```
### WorkloadIdentity
[Section titled “WorkloadIdentity”](#workloadidentity)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: assistant-api
namespace: riptides-system
spec:
connection:
tls:
mode: PERMISSIVE
intercept: true
scope:
daemonGroup:
id: "/"
selectors:
- k8s:label:app: assistant
k8s:pod:namespace: my-namespace
process:name: node
workloadID: "my-namespace/app/assistant-api"
```
### Deploy
[Section titled “Deploy”](#deploy)
```bash
riptides-cli ctl apply -f secret.yaml
riptides-cli ctl apply -f credentialsource.yaml
riptides-cli ctl apply -f service.yaml
riptides-cli ctl apply -f credentialbinding.yaml
riptides-cli ctl apply -f workloadidentity.yaml
```
Your application can now call `https://api.llm-provider.com/v1/messages` without setting any `Authorization` header. The Riptides kernel adds it automatically.
***
## Multiple APIs
[Section titled “Multiple APIs”](#multiple-apis)
A single workload can access multiple external APIs. Create a separate CredentialSource, Service, and CredentialBinding for each API - each CredentialBinding specifies its own `propagation.injection.selectors` to control which service it targets. The WorkloadIdentity only needs `connection.tls.intercept: true` set once at the top level.
***
## Verification
[Section titled “Verification”](#verification)
1. **CredentialSource** is `AVAILABLE`:
```bash
riptides-cli ctl get credentialsource my-api-bearer
```
2. **CredentialBinding** is `OK`:
```bash
riptides-cli ctl get credentialbinding my-workload-api-access
```
3. **WorkloadIdentity** is assigned:
```bash
riptides-cli ctl get workloadidentity my-workload
```
4. Make a request from your workload to the external API. The response should succeed without your application setting any authentication headers.
# Setting Up mTLS Between Services
This guide walks through securing communication between two internal services using mutual TLS (mTLS) with Riptides. By the end, your frontend application will connect to a backend API over an encrypted, mutually authenticated channel - without any code changes to either service.
## Overview
[Section titled “Overview”](#overview)
Riptides uses a kernel module to transparently intercept network traffic and upgrade it to mTLS. Your applications continue to make plain HTTP calls on localhost or internal addresses, while the kernel handles certificate exchange, encryption, and identity verification underneath.
In this guide you will:
1. Create a **WorkloadIdentity** for the backend API with inbound SPIFFE ID restrictions
2. Create a **WorkloadIdentity** for the frontend app with egress rules targeting the backend
3. Create a **Service** representing the backend endpoint
4. Verify that the frontend connects over mTLS without application changes
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides daemon group (this guide uses `daemongroup/dev-eu-west-1/on-demand-workers`)
* Both workloads deployed to a Kubernetes cluster with the Riptides daemon installed
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
## Scenario
[Section titled “Scenario”](#scenario)
You have two services in the `myapp` namespace:
| Service | Description | Address | Port |
| -------- | --------------------------------- | ------------------------------------- | ---- |
| frontend | Web application serving end users | `frontend.myapp.svc.cluster.local` | 8080 |
| backend | REST API consumed by the frontend | `backend-api.myapp.svc.cluster.local` | 3000 |
The goal: only the frontend may call the backend, and the backend must verify the frontend’s identity via mTLS.
## Step 1: Create the Backend Service
[Section titled “Step 1: Create the Backend Service”](#step-1-create-the-backend-service)
Define a Riptides `Service` resource that tells the control plane about the backend API’s network address.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: backend-api-svc
namespace: riptides-system
spec:
addresses:
- address: backend-api.myapp.svc.cluster.local
port: 3000
labels:
app: myapp
service: backend-api
```
Apply it:
```bash
riptides-cli ctl apply -f backend-api-svc.yaml
```
The `labels` field is important - egress rules on the frontend’s WorkloadIdentity will use these labels as selectors to match this Service.
## Step 2: Create the Backend WorkloadIdentity
[Section titled “Step 2: Create the Backend WorkloadIdentity”](#step-2-create-the-backend-workloadidentity)
The backend’s WorkloadIdentity defines its SPIFFE identity, how inbound connections are handled, and which callers are permitted.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: backend-api
namespace: riptides-system
spec:
workloadID: myapp/app/backend-api
selectors:
- k8s:label:app: backend-api
k8s:pod:namespace: myapp
process:name: node
scope:
daemonGroup:
id: daemongroup/dev-eu-west-1/on-demand-workers
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/myapp/app/frontend
```
Apply it:
```bash
riptides-cli ctl apply -f backend-api-workloadidentity.yaml
```
Key fields explained:
* **`workloadID`**: Becomes the SPIFFE ID `spiffe://example.com/myapp/app/backend-api` (where `example.com` is your trust domain).
* **`selectors`**: Match criteria that bind this identity to running pods. The daemon verifies the pod label, namespace, and process name before issuing an identity.
* **`connection.tls.mode: MUTUAL`**: Requires all inbound connections to present a valid client certificate.
* **`allowedSPIFFEIDs.inbound`**: Only the frontend’s SPIFFE ID is authorized. Any other workload attempting to connect will be rejected.
## Step 3: Create the Frontend WorkloadIdentity
[Section titled “Step 3: Create the Frontend WorkloadIdentity”](#step-3-create-the-frontend-workloadidentity)
The frontend needs its own identity and an egress rule that targets the backend Service.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: frontend
namespace: riptides-system
spec:
workloadID: myapp/app/frontend
selectors:
- k8s:label:app: frontend
k8s:pod:namespace: myapp
process:name: node
scope:
daemonGroup:
id: daemongroup/dev-eu-west-1/on-demand-workers
connection:
tls:
mode: PERMISSIVE
allowedSPIFFEIDs:
outbound:
- spiffe://example.com/myapp/app/backend-api
egress:
- selectors:
- app: myapp
service: backend-api
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/myapp/app/backend-api
```
Apply it:
```bash
riptides-cli ctl apply -f frontend-workloadidentity.yaml
```
Key fields explained:
* **`connection.tls.mode: PERMISSIVE`**: The frontend accepts both plaintext and TLS inbound connections (useful when it sits behind a load balancer or ingress controller that terminates TLS).
* **`allowedSPIFFEIDs.outbound`**: Restricts which SPIFFE IDs the frontend is allowed to connect to. If the backend presented a different identity, the connection would fail.
* **`egress`**: Defines outbound connection policies. Each entry matches a Service by its labels (`selectors`) and specifies the TLS mode and allowed peer identities for that destination.
* **`selectors`**: Match the `labels` on the backend Service resource from Step 1.
* **`connection.tls.mode: MUTUAL`**: The kernel will perform a full mTLS handshake when connecting to this destination.
* **`allowedSPIFFEIDs`**: The frontend verifies the backend presents this exact SPIFFE ID.
## Step 4: Verify Transparent mTLS
[Section titled “Step 4: Verify Transparent mTLS”](#step-4-verify-transparent-mtls)
Your frontend application does not need any changes. It continues to make plain HTTP requests to `backend-api.myapp.svc.cluster.local:3000`:
```javascript
// No TLS configuration needed -- the kernel handles it
const response = await fetch('http://backend-api.myapp.svc.cluster.local:3000/api/data');
```
Under the hood:
1. The frontend process opens a TCP connection to `backend-api.myapp.svc.cluster.local:3000`
2. The Riptides kernel module intercepts the outgoing connection
3. The kernel matches the destination against the egress rules and initiates an mTLS handshake
4. Both sides exchange X.509-SVID certificates containing their SPIFFE IDs
5. The backend kernel verifies the client certificate against `allowedSPIFFEIDs.inbound`
6. The frontend kernel verifies the server certificate against the egress `allowedSPIFFEIDs`
7. Encrypted data flows between the two services
## TLS Mode Reference
[Section titled “TLS Mode Reference”](#tls-mode-reference)
Riptides supports three TLS modes. Choose the right one based on your migration stage and security requirements.
| Mode | Behavior | When to Use |
| ---------------- | --------------------------------------------------------------------------------------------------------------------- | -------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| **`MUTUAL`** | Both client and server must present valid X.509-SVID certificates. Connections without certificates are rejected. | Production workloads where both sides are managed by Riptides. This is the strongest security posture. |
| **`PERMISSIVE`** | The server presents a certificate and accepts mTLS if the client offers one, but also allows plaintext connections. | During migration, when some callers are not yet enrolled in Riptides. Also useful for health checks and load balancer probes that cannot present certificates. |
| **`SIMPLE`** | The server presents a certificate (server-side TLS), but the client does not authenticate. Similar to standard HTTPS. | Connecting to external services that support TLS but not SPIFFE-based mTLS. |
A common migration path:
1. Start with **PERMISSIVE** on all services so existing traffic is unaffected
2. Monitor Riptides telemetry to confirm all callers are using mTLS
3. Switch to **MUTUAL** to enforce certificate-based authentication
## How allowedSPIFFEIDs Restrict Connections
[Section titled “How allowedSPIFFEIDs Restrict Connections”](#how-allowedspiffeids-restrict-connections)
The `allowedSPIFFEIDs` field provides bidirectional access control based on cryptographic identity:
### Inbound restrictions (`allowedSPIFFEIDs.inbound`)
[Section titled “Inbound restrictions (allowedSPIFFEIDs.inbound)”](#inbound-restrictions-allowedspiffeidsinbound)
Defined on the **server** (the service receiving connections). Only workloads whose SPIFFE IDs appear in this list can establish connections. All other callers are rejected at the TLS handshake.
```yaml
# On the backend: only the frontend and a monitoring service may connect
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/myapp/app/frontend
- spiffe://example.com/monitoring/app/healthcheck
```
### Outbound restrictions (`allowedSPIFFEIDs.outbound`)
[Section titled “Outbound restrictions (allowedSPIFFEIDs.outbound)”](#outbound-restrictions-allowedspiffeidsoutbound)
Defined on the **client** (the service initiating connections). The kernel verifies the server’s SPIFFE ID during the TLS handshake and drops the connection if it does not match.
```yaml
# On the frontend: only allow connecting to the backend
allowedSPIFFEIDs:
outbound:
- spiffe://example.com/myapp/app/backend-api
```
### Egress-level restrictions
[Section titled “Egress-level restrictions”](#egress-level-restrictions)
Each egress entry can also specify `allowedSPIFFEIDs` for fine-grained, per-destination control:
```yaml
egress:
- selectors:
- app: myapp
service: backend-api
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/myapp/app/backend-api
- selectors:
- app: cache
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/myapp/app/redis
```
Together, these restrictions enforce a zero-trust network model where every connection is authenticated and authorized based on cryptographic workload identity - all without any application-level changes.
# OIDC and Identity Provider Setup
This guide covers configuring user authentication for the Riptides control plane UI and API using OpenID Connect (OIDC) identity providers.
Free accounts: replacing the default login
Free accounts ship with **email code** authentication pre-configured for the registering user’s email only. This guide is how you replace or supplement that default so that team members can log in with their own credentials.
## Overview
[Section titled “Overview”](#overview)
Riptides uses OIDC to authenticate human users (platform engineers, security teams, operators) who access the control plane. The flow works as follows:
1. A user navigates to the Riptides UI or runs a `riptides-cli` command that requires authentication.
2. They are redirected to the configured identity provider (GitHub, Google, Bitbucket, or a static provider).
3. After authenticating with the IdP, the user is redirected back with an OIDC token.
4. Riptides validates the token and establishes a session.
You configure this with two Riptides custom resources:
* **IdentityProvider**: Defines the external IdP (GitHub, Google, etc.) and any restrictions (e.g., required organizations).
* **OIDCClient**: Defines an application that can initiate OIDC flows (the Riptides UI, `riptides-cli`, or your own applications).
***
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
* OAuth app credentials from your identity provider (e.g., a GitHub OAuth App)
***
## Step 1: Create an IdentityProvider
[Section titled “Step 1: Create an IdentityProvider”](#step-1-create-an-identityprovider)
### GitHub
[Section titled “GitHub”](#github)
The most common setup uses GitHub as the identity provider, restricting access to members of specific organizations.
First, create a GitHub OAuth App:
1. Go to your GitHub organization’s Settings > Developer settings > OAuth Apps > New OAuth App.
2. Set the **Authorization callback URL** to `https:///oidc/auth/callback`.
3. Note the **Client ID** and generate a **Client Secret**.
Then create the IdentityProvider resource:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: IdentityProvider
metadata:
name: github
namespace: riptides-system
spec:
name: GitHub
github:
clientID: ""
clientSecret: ""
requiredOrgs:
- name: ""
```
**Field reference:**
| Field | Description |
| --------------------- | ----------------------------------------------------------------------------------- |
| `spec.name` | Display name shown on the login screen. |
| `github.clientID` | OAuth App client ID from GitHub. |
| `github.clientSecret` | OAuth App client secret from GitHub. |
| `github.requiredOrgs` | List of GitHub organizations. Only members of these organizations can authenticate. |
```bash
riptides-cli ctl apply -f identityprovider-github.yaml
```
Verify the provider is ready:
```bash
riptides-cli ctl get identityprovider github -o jsonpath='{.status.state}'
# Available
```
If it shows `Failed`, check the reason:
```bash
riptides-cli ctl get identityprovider github -o jsonpath='{.status.message}'
```
### Google
[Section titled “Google”](#google)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: IdentityProvider
metadata:
name: google
namespace: riptides-system
spec:
name: Google
google:
clientID: ""
clientSecret: ""
requiredHostedDomains:
- ""
```
The `requiredHostedDomains` field restricts login to users with email addresses in the specified domain(s).
### Bitbucket
[Section titled “Bitbucket”](#bitbucket)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: IdentityProvider
metadata:
name: bitbucket
namespace: riptides-system
spec:
name: Bitbucket
bitbucket:
clientID: ""
clientSecret: ""
```
### Static (Development / Testing)
[Section titled “Static (Development / Testing)”](#static-development--testing)
For development environments where you do not want to set up an external IdP, use the static provider with a single hardcoded user identity:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: IdentityProvider
metadata:
name: static-dev
namespace: riptides-system
spec:
name: "Dev Login"
static:
email: "admin@example.com"
name: "Dev Admin"
preferredUsername: "admin"
groups:
- "platform"
```
> **Warning:** The static provider is intended for development and testing only. Do not use it in production.
***
## Step 2: Create an OIDCClient
[Section titled “Step 2: Create an OIDCClient”](#step-2-create-an-oidcclient)
OIDCClients represent applications that initiate OIDC authentication flows. Riptides supports two types:
### Native Client (riptides-cli and Riptides UI)
[Section titled “Native Client (riptides-cli and Riptides UI)”](#native-client-riptides-cli-and-riptides-ui)
A native client is used for the built-in Riptides UI and `riptides-cli` access. It uses PKCE (Proof Key for Code Exchange) and does not require a client secret.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: OIDCClient
metadata:
name: riptides-ui
namespace: riptides-system
spec:
native: {}
redirectUrls:
- "https:///ui/callback"
- "http://localhost:8000/auth/callback"
```
The `redirectUrls` list includes:
* The production UI callback URL.
* A localhost callback for `riptides-cli` authentication flows (the CLI opens a local HTTP server to receive the callback).
```bash
riptides-cli ctl apply -f oidcclient-native.yaml
```
### Custom Client (External Applications)
[Section titled “Custom Client (External Applications)”](#custom-client-external-applications)
For integrating external applications (dashboards, CI/CD systems, custom tooling) with the Riptides control plane API, create a custom OIDCClient:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: OIDCClient
metadata:
name: my-dashboard
namespace: riptides-system
spec:
custom:
grantTypes:
- authorization_code
- refresh_token
responseTypes:
- code
authMethod: client_secret_post
redirectUrls:
- "https://dashboard.example.com/callback"
```
**Field reference:**
| Field | Description |
| ---------------------- | ------------------------------------------------------------------------------------------------- |
| `custom.grantTypes` | OAuth 2.0 grant types the client can use. |
| `custom.responseTypes` | OAuth 2.0 response types the client can use. |
| `custom.authMethod` | How the client authenticates to the token endpoint (`client_secret_post`, `client_secret_basic`). |
| `redirectUrls` | Allowed callback URLs after authentication. |
```bash
riptides-cli ctl apply -f oidcclient-custom.yaml
```
After creation, Riptides generates a client ID and client secret for the custom client. Retrieve them:
```bash
riptides-cli ctl get oidcclient my-dashboard -o yaml
```
Use these credentials in your application’s OIDC configuration.
***
## Authentication Flow
[Section titled “Authentication Flow”](#authentication-flow)
Once both resources are configured, the authentication flow works as follows:
1. **User visits the Riptides UI** (or runs a `riptides-cli` command that requires auth).
2. **Riptides redirects to the IdP** (e.g., GitHub’s OAuth authorization page).
3. **User authenticates** with their IdP credentials (e.g., GitHub username/password + 2FA).
4. **IdP redirects back** to the `redirectUrl` configured on the OIDCClient, with an authorization code.
5. **Riptides exchanges the code** for an ID token and validates it against the IdentityProvider configuration (checking organization membership, domain, etc.).
6. **Session is established**. The user can access the UI or issue authenticated API/`riptides-cli` commands.
For `riptides-cli`, the flow uses a local HTTP server:
```bash
# This triggers the OIDC flow — a browser window opens for authentication
riptides-cli ctl get workloadidentities
```
***
## Step 3: Grant access with ClusterRoleBindings
[Section titled “Step 3: Grant access with ClusterRoleBindings”](#step-3-grant-access-with-clusterrolebindings)
Configuring an IdentityProvider is not enough on its own. After authentication, Riptides checks Kubernetes RBAC to decide what the user can do. You grant access by binding the groups that your IdP returns to one of the predefined ClusterRoles:
| ClusterRole | Access |
| ------------------------ | --------------------------------------------------------------------------------------------- |
| `riptides:users:viewer` | Read-only access to all Riptides resources. |
| `riptides:users:editor` | Full read/write access to all Riptides resources and Kubernetes Secrets in `riptides-system`. |
| `riptides:cluster-admin` | Unrestricted access to all resources and verbs across the entire cluster. Use with caution. |
### GitHub teams as groups
[Section titled “GitHub teams as groups”](#github-teams-as-groups)
When a user authenticates via the GitHub IdentityProvider, their GitHub team memberships are injected as OIDC `groups` claims in the form `:`. For example, a member of the `devs` team in the `abbazappa` organization gets the group `abbazappa:devs`.
> **Important:** Groups are populated from **team memberships only**. Being a member of an org without belonging to any team produces an empty `groups` claim — the user can log in but will have no RBAC access. Make sure the users you want to grant access are in at least one GitHub team.
Bind a team group to the editor role:
```yaml
apiVersion: rbac.authorization.k8s.io/v1
kind: ClusterRoleBinding
metadata:
name: riptides-github-devs-editor
roleRef:
apiGroup: rbac.authorization.k8s.io
kind: ClusterRole
name: riptides:users:editor
subjects:
- apiGroup: rbac.authorization.k8s.io
kind: Group
name: "abbazappa:devs"
```
```bash
riptides-cli ctl apply -f clusterrolebinding-devs.yaml
```
Any member of `abbazappa/devs` who logs in with GitHub will now have editor access. Adding or removing someone from the GitHub team takes effect on their next login — no Kubernetes changes required.
For read-only access (e.g. for an `ops` team):
```yaml
subjects:
- apiGroup: rbac.authorization.k8s.io
kind: Group
name: "abbazappa:ops"
roleRef:
kind: ClusterRole
name: riptides:users:viewer
apiGroup: rbac.authorization.k8s.io
```
For nested teams the group name includes the full parent chain: `abbazappa:platform:devs`.
### Other providers
[Section titled “Other providers”](#other-providers)
The same pattern works for any IdentityProvider. The group names in the binding just need to match whatever `groups` claim the IdP returns:
| Provider | Groups claim format |
| ---------------- | ----------------------------------------------------------------------------------------- |
| GitHub | `:` (e.g. `abbazappa:devs`), or `::` for nested teams |
| Google / OIDC | Groups returned in the IdP’s `groups` claim |
| Entra (Azure AD) | Group object IDs or display names, depending on configuration |
Free account: granting yourself editor access after adding GitHub
On a free account the initial email-code login has admin rights provisioned separately. If you add a GitHub IdentityProvider and log in with it, you will have no rights until you create a ClusterRoleBinding for one of your GitHub teams. Make sure your GitHub user belongs to at least one team in the required org and bind that team’s group to `riptides:users:editor`.
### Applying changes to an existing session
[Section titled “Applying changes to an existing session”](#applying-changes-to-an-existing-session)
OIDC tokens are cached locally by `riptides-cli`. If you already have a valid cached token, creating or updating a ClusterRoleBinding will not take effect until the token is refreshed. Force a fresh login for the current context:
```bash
riptides-cli context login
```
This opens a browser for re-authentication and the new token will include the updated groups.
***
## Multiple Identity Providers
[Section titled “Multiple Identity Providers”](#multiple-identity-providers)
You can configure multiple IdentityProviders simultaneously. The login screen will show all available providers, and users choose which one to authenticate with.
```bash
riptides-cli ctl get identityprovider -o jsonpath='{range .items[*]}{.metadata.name}{"\t"}{.status.state}{"\n"}{end}'
```
***
## Verification
[Section titled “Verification”](#verification)
1. Check that each **IdentityProvider** reached `Available` state:
```bash
riptides-cli ctl get identityprovider -o jsonpath='{range .items[*]}{.metadata.name}{"\t"}{.status.state}{"\n"}{end}'
```
2. Check that the **OIDCClient** exists:
```bash
riptides-cli ctl get oidcclient
```
3. Open the Riptides UI in a browser. You should see a login page with your configured identity provider(s). Click the provider name, authenticate, and confirm you are redirected back to the UI with an active session.
4. Run any Riptides command and confirm it completes successfully:
```bash
riptides-cli ctl get workloadidentities
```
# Secretless AWS Access
This guide shows how to access AWS services (such as Amazon Bedrock) from your workloads without storing or distributing any AWS credentials. Riptides federates workload identity to AWS via OIDC, and the kernel module automatically signs outbound requests with AWS SigV4 - your application makes plain HTTP calls.
## Overview
[Section titled “Overview”](#overview)
Traditional approaches to AWS access require distributing long-lived IAM access keys or mounting service account tokens. Both create secrets that must be rotated, stored securely, and audited.
With Riptides, the flow is:
1. The Riptides control plane acts as an OIDC identity provider
2. AWS IAM is configured to trust this OIDC provider
3. A `CredentialSource` references the IAM role to assume
4. A `CredentialBinding` binds the credential to your workload’s identity
5. The kernel module intercepts outbound HTTP requests to AWS and attaches SigV4 signatures automatically
Your application never sees or handles AWS credentials.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A Riptides control plane with an OIDC endpoint (e.g., `https://cp.example.com/oidc`)
* An AWS account with permissions to create IAM roles and OIDC identity providers
* A workload deployed on a Kubernetes cluster with the Riptides daemon installed
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
## Step 1: Configure AWS IAM
[Section titled “Step 1: Configure AWS IAM”](#step-1-configure-aws-iam)
### Create an OIDC Identity Provider
[Section titled “Create an OIDC Identity Provider”](#create-an-oidc-identity-provider)
In the AWS Console or via CLI, register the Riptides control plane as an OIDC identity provider.
**AWS Console:**
1. Navigate to **IAM > Identity providers > Add provider**
2. Select **OpenID Connect**
3. Set the **Provider URL** to your Riptides control plane OIDC URL (e.g., `https://.console.riptides.io/oidc`)
4. Set the **Audience** to `sts.amazonaws.com`
5. Click **Add provider**
**AWS CLI:**
> **Note:** Riptides uses a Let’s Encrypt certificate, so AWS will validate the OIDC provider against its trusted CA bundle and `--thumbprint-list` is not required.
```bash
aws iam create-open-id-connect-provider \
--url https://.console.riptides.io/oidc \
--client-id-list sts.amazonaws.com
```
### Create an IAM Role with a Trust Policy
[Section titled “Create an IAM Role with a Trust Policy”](#create-an-iam-role-with-a-trust-policy)
Create an IAM role that AWS workloads will assume. The trust policy restricts assumption to a specific SPIFFE ID, ensuring only the intended workload can obtain credentials.
**AWS Console:**
1. Navigate to **IAM > Roles > Create role**
2. Select **Custom trust policy**
3. Apply the JSON below
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Principal": {
"Federated": "arn:aws:iam::123456789012:oidc-provider/.console.riptides.io/oidc"
},
"Action": "sts:AssumeRoleWithWebIdentity",
"Condition": {
"StringEquals": {
".console.riptides.io/oidc:aud": "sts.amazonaws.com"
}
}
}
]
}
```
**AWS CLI:**
Save the above JSON to `trust-policy.json`, replacing the account ID and `` placeholders:
```bash
aws iam create-role \
--role-name my-app-bedrock-role \
--assume-role-policy-document file://trust-policy.json
```
Attach the appropriate permissions policy for your use case. For example, to access Amazon Bedrock:
**AWS Console:**
1. Select the created Role
2. Add permissions > Create inline policy
3. Policy editor > JSON
```json
{
"Version": "2012-10-17",
"Statement": [
{
"Effect": "Allow",
"Action": [
"bedrock:InvokeModel",
"bedrock:InvokeModelWithResponseStream",
"bedrock:InvokeAgent"
],
"Resource": "*"
}
]
}
```
**AWS CLI:**
Save the above JSON to `bedrock-policy.json`, replacing `my-app-bedrock-role` with your role name:
```bash
aws iam put-role-policy \
--role-name my-app-bedrock-role \
--policy-name bedrock-access \
--policy-document file://bedrock-policy.json
```
## Step 2: Create a WorkloadIdentity
[Section titled “Step 2: Create a WorkloadIdentity”](#step-2-create-a-workloadidentity)
The WorkloadIdentity must exist before other resources that reference its `workloadID`. It assigns a SPIFFE identity to the workload and enables TLS intercept for outbound connections so the kernel can inject credentials.
First, find the daemon running on the host:
```bash
riptides-cli ctl get daemons
```
Retrieve its ID:
```bash
riptides-cli ctl get daemon -o jsonpath='{.spec.workloadID}'
```
Use that value in the `scope.daemon.id` field below:
```bash
riptides-cli ctl apply -f - <"
selectors:
- k8s:label:app: my-app
k8s:pod:namespace: my-app
process:name: python3
workloadID: my-app/workload
EOF
```
Key field:
* **`connection.tls.intercept: true`**: The kernel intercepts outbound TLS connections and handles credential injection. Required for the `injection` propagation mode to work.
## Step 3: Create the CredentialSource
[Section titled “Step 3: Create the CredentialSource”](#step-3-create-the-credentialsource)
The CredentialSource tells Riptides how to obtain AWS credentials. For AWS, it references the IAM role ARN. Riptides uses the workload’s SPIFFE-based JWT-SVID to call `sts:AssumeRoleWithWebIdentity` and obtain temporary credentials, which are automatically rotated before expiration.
```bash
riptides-cli ctl apply -f - <
EOF
```
Verify:
```bash
riptides-cli ctl describe credentialsource my-app-aws-creds
# STATE should show AVAILABLE
```
## Step 4: Create the AWS Service
[Section titled “Step 4: Create the AWS Service”](#step-4-create-the-aws-service)
Define a Riptides `Service` resource for the AWS API endpoint your workload needs to reach.
```bash
riptides-cli ctl apply -f - <
This guide shows how to access Google Cloud services from your workloads without distributing service account keys. Riptides federates workload identity to GCP via OIDC using Workload Identity Federation, and delivers credentials transparently - either injected on the wire or via sysfs for Application Default Credentials (ADC).
## Overview
[Section titled “Overview”](#overview)
GCP Workload Identity Federation allows external identity providers to impersonate GCP service accounts without long-lived keys. Riptides integrates with this mechanism:
1. The Riptides control plane acts as an OIDC identity provider
2. A GCP Workload Identity Pool and Provider are configured to trust the Riptides OIDC endpoint
3. A `CredentialSource` references the GCP federation details
4. A `CredentialBinding` binds the credential to your workload and controls delivery (wire injection, sysfs, or both)
5. The workload accesses GCP APIs without handling any credentials
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A Riptides control plane with an OIDC endpoint (e.g., `https://.console.riptides.io/oidc`)
* A GCP project with permissions to create Workload Identity Pools, providers, and service accounts
* A workload deployed on a Kubernetes cluster with the Riptides daemon installed
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
* `gcloud` CLI installed (for GCP configuration steps)
## Step 1: Configure GCP Workload Identity Federation
[Section titled “Step 1: Configure GCP Workload Identity Federation”](#step-1-configure-gcp-workload-identity-federation)
### Create a Workload Identity Pool
[Section titled “Create a Workload Identity Pool”](#create-a-workload-identity-pool)
A Workload Identity Pool is a container for external identities. Create one for your Riptides workloads.
```bash
gcloud iam workload-identity-pools create riptides-pool \
--project=my-gcp-project \
--location=global \
--display-name="Riptides Workload Pool"
```
### Create a Workload Identity Provider
[Section titled “Create a Workload Identity Provider”](#create-a-workload-identity-provider)
Add an OIDC provider to the pool that trusts the Riptides control plane.
```bash
gcloud iam workload-identity-pools providers create-oidc riptides-provider \
--project=my-gcp-project \
--location=global \
--workload-identity-pool=riptides-pool \
--issuer-uri=https://.console.riptides.io/oidc \
--allowed-audiences="//iam.googleapis.com/projects//locations/global/workloadIdentityPools/riptides-pool/providers/riptides-provider" \
--attribute-mapping="google.subject=assertion.sub"
```
Key parameters:
* **`--issuer-uri`**: The Riptides control plane OIDC endpoint.
* **`--allowed-audiences`**: The full resource name of the Workload Identity Provider. It follows the fixed format `//iam.googleapis.com/projects//locations/global/workloadIdentityPools//providers/`, where all components are known at this point. To get your `PROJECT_NUMBER`:
```bash
gcloud projects describe my-gcp-project --format="value(projectNumber)"
```
* **`--attribute-mapping`**: Maps the JWT `sub` claim (which contains the SPIFFE ID) to `google.subject` for use in IAM bindings.
### Create a GCP Service Account
[Section titled “Create a GCP Service Account”](#create-a-gcp-service-account)
Create a service account that your workload will impersonate.
```bash
gcloud iam service-accounts create my-app-sa \
--project=my-gcp-project \
--display-name="My App Service Account"
```
Grant the service account the permissions your workload needs. For example, to access Cloud Storage and Vertex AI:
```bash
gcloud projects add-iam-policy-binding my-gcp-project \
--member="serviceAccount:my-app-sa@my-gcp-project.iam.gserviceaccount.com" \
--role="roles/storage.objectViewer"
gcloud projects add-iam-policy-binding my-gcp-project \
--member="serviceAccount:my-app-sa@my-gcp-project.iam.gserviceaccount.com" \
--role="roles/aiplatform.user"
```
### Bind the External Identity to the Service Account
[Section titled “Bind the External Identity to the Service Account”](#bind-the-external-identity-to-the-service-account)
Allow the specific SPIFFE ID from Riptides to impersonate this service account.
```bash
gcloud iam service-accounts add-iam-policy-binding \
my-app-sa@my-gcp-project.iam.gserviceaccount.com \
--project=my-gcp-project \
--role="roles/iam.workloadIdentityUser" \
--member="principal://iam.googleapis.com/projects/123456789012/locations/global/workloadIdentityPools/riptides-pool/subject/spiffe://example.com/my-app/workload"
```
The `--member` field uses the format `principal://iam.googleapis.com/projects//locations/global/workloadIdentityPools//subject/`. This ensures only the workload with the matching SPIFFE ID can impersonate the service account.
To find your `PROJECT_NUMBER`, you can retrieve it from the pool’s resource name:
```bash
gcloud iam workload-identity-pools describe riptides-pool \
--location=global --project=my-gcp-project \
--format="value(name)"
```
The output will be in the form `projects//locations/global/workloadIdentityPools/riptides-pool`.
## Step 2: Create the GCP Service
[Section titled “Step 2: Create the GCP Service”](#step-2-create-the-gcp-service)
Define a Riptides `Service` resource for the GCP API endpoint your workload needs.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: gcp-storage-svc
namespace: riptides-system
spec:
addresses:
- address: storage.googleapis.com
port: 443
external: true
labels:
app: my-app
service: gcp-storage
```
Apply it:
```bash
riptides-cli ctl apply -f gcp-storage-svc.yaml
```
If your workload accesses multiple GCP APIs, create a Service for each endpoint:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: gcp-vertexai-svc
namespace: riptides-system
spec:
addresses:
- address: us-central1-aiplatform.googleapis.com
port: 443
external: true
labels:
app: my-app
service: gcp-vertexai
```
## Step 3: Create the WorkloadIdentity
[Section titled “Step 3: Create the WorkloadIdentity”](#step-3-create-the-workloadidentity)
Create (or update) the WorkloadIdentity for your application with TLS intercept enabled. The CredentialBinding you will create in the next steps handles which services receive the credentials via its `propagation.injection.selectors`.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-app
namespace: riptides-system
spec:
workloadID: my-app/workload
selectors:
- k8s:label:app: my-app
k8s:pod:namespace: my-app
process:name: python3
scope:
daemonGroup:
id: daemongroup/dev-eu-west-1/on-demand-workers
connection:
tls:
mode: PERMISSIVE
intercept: true
```
Apply it:
```bash
riptides-cli ctl apply -f my-app-workloadidentity.yaml
```
Key fields:
* **`connection.tls.intercept: true`**: Enables kernel-level TLS interception for outbound connections. Required for credential injection into HTTPS requests to external services.
## Step 4: Create the CredentialSource
[Section titled “Step 4: Create the CredentialSource”](#step-4-create-the-credentialsource)
A `CredentialSource` with the `gcp` type tells Riptides how to exchange a SPIFFE JWT-SVID for GCP access tokens.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: my-app-gcp-creds
namespace: riptides-system
spec:
gcp:
oidcProviderId: >-
//iam.googleapis.com/projects/123456789012/locations/global/workloadIdentityPools/riptides-pool/providers/riptides-provider
serviceAccount: my-app-sa@my-gcp-project.iam.gserviceaccount.com
scopes:
- https://www.googleapis.com/auth/cloud-platform
lifetime: 3600s
```
Apply it:
```bash
riptides-cli ctl apply -f my-app-gcp-credsource.yaml
```
Key fields:
* **`oidcProviderId`**: The full resource path to the Workload Identity Provider in GCP. Format: `//iam.googleapis.com/projects//locations/global/workloadIdentityPools//providers/`
* **`serviceAccount`**: The GCP service account email to impersonate.
* **`scopes`**: OAuth scopes for the generated access tokens. Use `https://www.googleapis.com/auth/cloud-platform` for broad access, or narrow it to specific API scopes.
* **`lifetime`**: How long each access token is valid. Riptides automatically refreshes tokens before expiration.
## Step 5: Create the CredentialBinding
[Section titled “Step 5: Create the CredentialBinding”](#step-5-create-the-credentialbinding)
A `CredentialBinding` connects the `CredentialSource` to your workload identity and defines how credentials are delivered.
### Option A: Wire Injection (for HTTP API calls)
[Section titled “Option A: Wire Injection (for HTTP API calls)”](#option-a-wire-injection-for-http-api-calls)
The kernel injects OAuth bearer tokens into outbound HTTP requests. Your application makes plain calls to GCP APIs.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: my-app-gcp-binding
namespace: riptides-system
spec:
workloadID: my-app/workload
credentialSource: my-app-gcp-creds
propagation:
injection:
selectors:
- app: my-app
service: gcp-storage
- app: my-app
service: gcp-vertexai
```
### Option B: sysfs Delivery (for Application Default Credentials)
[Section titled “Option B: sysfs Delivery (for Application Default Credentials)”](#option-b-sysfs-delivery-for-application-default-credentials)
Riptides can also expose credentials via the sysfs filesystem, allowing GCP client libraries that use Application Default Credentials (ADC) to pick them up automatically.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: my-app-gcp-binding
namespace: riptides-system
spec:
workloadID: my-app/workload
credentialSource: my-app-gcp-creds
propagation:
injection:
selectors:
- app: my-app
service: gcp-storage
sysfs: {}
```
### Option C: sysfs Only
[Section titled “Option C: sysfs Only”](#option-c-sysfs-only)
If your application uses the GCP SDK exclusively and you do not need wire-level injection:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: my-app-gcp-binding
namespace: riptides-system
spec:
workloadID: my-app/workload
credentialSource: my-app-gcp-creds
propagation:
sysfs: {}
```
Apply whichever option fits your use case:
```bash
riptides-cli ctl apply -f my-app-gcp-binding.yaml
```
Key fields:
* **`propagation.injection.selectors`**: Controls which egress destinations receive injected credentials. Selectors match Service labels.
* **`propagation.sysfs`**: When present (even as an empty object `{}`), Riptides exposes the credential via sysfs. The token becomes available at a path like `/sys/module/riptides/credentials///token.jwt`. GCP client libraries can be configured to read from this path.
## Step 6: Access GCP from Your Application
[Section titled “Step 6: Access GCP from Your Application”](#step-6-access-gcp-from-your-application)
### With Wire Injection
[Section titled “With Wire Injection”](#with-wire-injection)
Your application makes plain HTTP requests. The kernel injects the OAuth bearer token automatically.
```python
import requests
# No GCP SDK or credentials needed
response = requests.get(
"https://storage.googleapis.com/storage/v1/b/my-bucket/o",
headers={"Content-Type": "application/json"}
)
print(response.json())
```
### With sysfs and GCP Client Libraries
[Section titled “With sysfs and GCP Client Libraries”](#with-sysfs-and-gcp-client-libraries)
When using sysfs delivery, configure the GCP SDK to use the token from the sysfs path. The CredentialBinding status will show the exact file path after the binding is created:
```bash
riptides-cli ctl get credentialbinding my-app-gcp-binding -o yaml
```
Look for the `status.sysfs.files` field:
```yaml
status:
state: OK
sysfs:
files:
- path: /sys/module/riptides/credentials//my-app-gcp-binding/token.jwt
type: TOKEN
```
Your application can then use this path with the GCP client library:
```python
from google.cloud import storage
from google.auth import credentials
# The GCP SDK reads the token from the sysfs path
# configured via GOOGLE_APPLICATION_CREDENTIALS or
# programmatic credential loading
client = storage.Client(project="my-gcp-project")
buckets = list(client.list_buckets())
```
## How It Works: The OIDC Federation Flow
[Section titled “How It Works: The OIDC Federation Flow”](#how-it-works-the-oidc-federation-flow)
**Phase 1 - Credential provisioning (triggered by CredentialBinding creation):**
```plaintext
Riptides Control Plane
|
|-- (1) Workload has SPIFFE ID: spiffe://example.com/my-app/workload
|-- (2) Control plane presents workload's JWT-SVID to GCP STS for federation
|-- (3) GCP validates the JWT against the Riptides OIDC endpoint
|-- (4) GCP returns an access token scoped to the service account
|-- (5) Control plane pushes credentials to daemon → daemon loads them into kernel module
|-- (6) Credentials are automatically refreshed before expiration
```
**Phase 2 - Connection-time injection:**
```plaintext
Workload (plain HTTP or SDK call)
|
v
Riptides Kernel Module (intercepts outbound connection)
|
|-- (1) Daemon evaluates connection context
|-- (2) Daemon determines credential to inject; sets reference in eval context
|-- (3) Kernel checks eval context for credential reference
|-- (4) Kernel injects the bearer token into the outbound request
|
v
GCP API (e.g., Cloud Storage, Vertex AI)
```
## Credential Delivery Comparison
[Section titled “Credential Delivery Comparison”](#credential-delivery-comparison)
| Method | How It Works | Best For |
| ------------------ | --------------------------------------------------------------------------------------------------------------------------------------------------- | ---------------------------------------------------------------------------------------------------------- |
| **Wire injection** | The kernel intercepts outbound HTTP requests and adds the `Authorization: Bearer ` header. The application uses plain HTTP. | Applications that make direct REST API calls without using the GCP SDK. Zero application changes required. |
| **sysfs** | The credential is written to a file under `/sys/module/riptides/credentials/`. GCP client libraries can read it as Application Default Credentials. | Applications that use the GCP SDK and expect ADC-style credential discovery. |
| **Both** | Combine injection and sysfs for maximum flexibility. | Applications that mix direct HTTP calls and SDK usage. |
## Troubleshooting
[Section titled “Troubleshooting”](#troubleshooting)
| Symptom | Likely Cause | Fix |
| ----------------------------------- | ------------------------------------------------------------------------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `PERMISSION_DENIED` from GCP | The SPIFFE ID does not match the principal binding on the service account | Verify the `--member` in the IAM policy binding matches `principal://iam.googleapis.com/projects//.../subject/spiffe://example.com/` |
| CredentialSource stuck in `PENDING` | OIDC provider not configured correctly in GCP | Verify the Workload Identity Pool provider `issuer-uri` matches the Riptides control plane URL exactly |
| CredentialBinding state is not `OK` | Mismatched `workloadID` | Ensure the CredentialBinding `workloadID` matches the WorkloadIdentity `workloadID` |
| Token expired errors | Lifetime too short or clock skew | Increase `lifetime` in the CredentialSource spec. Riptides refreshes tokens before expiration, but large clock differences between the cluster and GCP can cause issues. |
| sysfs path not appearing | Missing `sysfs: {}` in propagation | Ensure the CredentialBinding includes `propagation.sysfs: {}`. Check `status.sysfs.files` in the binding resource. |
# Vault / OpenBao Integration
This guide walks through integrating HashiCorp Vault (or OpenBao) with Riptides so that workloads can retrieve secrets - API keys, database passwords, cloud credentials - without ever storing Vault tokens inside the cluster.
## How It Works
[Section titled “How It Works”](#how-it-works)
Every workload managed by Riptides receives a SPIFFE SVID (X.509 certificate). When a workload needs a secret from Vault, Riptides presents that SVID as a JWT to Vault’s JWT auth method. Vault validates the JWT against the Riptides control plane’s OIDC discovery endpoint, confirms the workload’s SPIFFE ID matches the configured role, and issues the requested secret. No long-lived Vault tokens are stored or distributed.
The flow:
1. The control plane reads the CredentialBinding and presents the workload’s JWT-SVID to Vault’s JWT auth method.
2. Vault validates the JWT using the issuer URL.
3. Vault returns the requested credential.
4. The control plane pushes the credential to the daemon, which loads it into the kernel.
5. The kernel injects the credential into outbound requests at connection time.
## Prerequisites
[Section titled “Prerequisites”](#prerequisites)
* A running Riptides control plane
* A Vault (or OpenBao) instance reachable from the cluster
* [`riptides-cli`](../../deployment/cli) configured with access to the control plane
***
## Step 1: Configure Vault JWT Auth Method
[Section titled “Step 1: Configure Vault JWT Auth Method”](#step-1-configure-vault-jwt-auth-method)
Enable the JWT auth method in Vault and point it at the Riptides control plane’s OIDC discovery URL.
```bash
# Enable the JWT auth method at a custom path
vault auth enable -path=jwt jwt
# Configure it to use the Riptides control plane for token validation
vault write auth/jwt/config \
oidc_discovery_url="https:///oidc" \
default_role=""
```
Replace `` with the address of your Riptides control plane (for example, `controlplane.example.com`). Note the `/oidc` suffix — the OIDC discovery endpoint is served under that path (e.g. `https://controlplane.example.com/oidc`).
## Step 2: Create a Vault Policy
[Section titled “Step 2: Create a Vault Policy”](#step-2-create-a-vault-policy)
Define a policy that grants read access to the secret path your workload needs.
```bash
vault policy write my-api-keys - </vault-api-keys-binding/token.jwt
type: TOKEN
```
## Step 7: Create a WorkloadIdentity with Egress
[Section titled “Step 7: Create a WorkloadIdentity with Egress”](#step-7-create-a-workloadidentity-with-egress)
The WorkloadIdentity assigns a SPIFFE ID to your workload and enables TLS intercept for outbound connections. The CredentialBinding created in the previous step controls which services receive the credential via its `propagation.injection.selectors`.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: my-workload
namespace: riptides-system
spec:
connection:
tls:
mode: PERMISSIVE
intercept: true
scope:
daemonGroup:
id: "/"
selectors:
- k8s:label:app: my-workload
k8s:pod:namespace: my-namespace
process:name: node
workloadID: "my-namespace/app/my-workload"
```
Key fields:
* **`connection.tls.intercept: true`**: Tells the kernel to intercept outbound connections and handle TLS + credential injection.
```bash
riptides-cli ctl apply -f workloadidentity.yaml
```
## Step 8: Configure the Riptides CA Bundle
[Section titled “Step 8: Configure the Riptides CA Bundle”](#step-8-configure-the-riptides-ca-bundle)
Because the egress rule uses `tls.intercept: true`, the kernel module terminates and re-originates the TLS connection. Applications that perform their own TLS certificate verification need to trust the Riptides CA.
Set the appropriate CA bundle environment variable for your application:
```bash
# For Python requests
export REQUESTS_CA_BUNDLE=/sys/module/riptides/certs/ca-certificates.crt
# For Node.js
export NODE_EXTRA_CA_CERTS=/sys/module/riptides/certs/ca-certificates.crt
# For cURL
export CURL_CA_BUNDLE=/sys/module/riptides/certs/ca-certificates.crt
```
If your application uses the `injection` propagation mode exclusively (the kernel injects credentials into plain HTTP requests), the kernel handles TLS entirely and no CA configuration is needed. The CA bundle is only required when the application itself initiates a TLS connection to a destination where `tls.intercept: true` is configured.
See [Trusting the Riptides CA](../../concepts/kernel-module/#trusting-the-riptides-ca-for-tls-intercept) for the full list of supported environment variables.
***
## Cloud Credential Types
[Section titled “Cloud Credential Types”](#cloud-credential-types)
In addition to the `token` type, Vault CredentialSources support cloud-native credential generation. These use Vault’s secrets engines to produce short-lived cloud credentials:
### AWS
[Section titled “AWS”](#aws)
```yaml
spec:
vault:
address: "https://vault.example.com"
audience:
- "your-vault-audience"
jwtAuthMethodPath: jwt
path: "aws/creds/my-role"
role: "my-aws-role"
type:
aws: {}
```
Vault’s AWS secrets engine generates temporary IAM credentials. The workload receives `AWS_ACCESS_KEY_ID`, `AWS_SECRET_ACCESS_KEY`, and `AWS_SESSION_TOKEN`.
### GCP
[Section titled “GCP”](#gcp)
```yaml
spec:
vault:
address: "https://vault.example.com"
audience:
- "your-vault-audience"
jwtAuthMethodPath: jwt
path: "gcp/token/my-role"
role: "my-gcp-role"
type:
gcp: {}
```
### Azure
[Section titled “Azure”](#azure)
```yaml
spec:
vault:
address: "https://vault.example.com"
audience:
- "your-vault-audience"
jwtAuthMethodPath: jwt
path: "azure/creds/my-role"
role: "my-azure-role"
type:
azure: {}
```
These cloud types remove the need for static cloud credentials entirely. Vault generates short-lived credentials on demand, and Riptides delivers them transparently to the workload.
***
## Verification
[Section titled “Verification”](#verification)
After deploying all resources, confirm the end-to-end flow:
1. **CredentialSource** is `AVAILABLE`:
```bash
riptides-cli ctl get credentialsource vault-api-keys
```
2. **CredentialBinding** is `OK`:
```bash
riptides-cli ctl get credentialbinding vault-api-keys-binding
```
3. **WorkloadIdentity** is assigned:
```bash
riptides-cli ctl get workloadidentity my-workload
```
4. Your workload can reach the API without any credential configuration in its code or environment variables. The Riptides kernel handles authentication transparently.
# What is Riptides?
Riptides gives every workload in your infrastructure, whether it’s a long-running service, a CI job, or an AI agent, a cryptographic identity, and uses that identity to enforce mTLS, control which destinations a workload is allowed to reach, and deliver credentials, all without storing secrets in code or config and without modifying application or agent code.
It works at the kernel level, so applications and agent frameworks don’t need to be modified, instrumented, or rebuilt. A daemon runs on each node and loads policy into a kernel module that intercepts TCP connections, performs mutual TLS handshakes, and injects credentials into outbound requests, transparently.
## The problem it solves
[Section titled “The problem it solves”](#the-problem-it-solves)
Most infrastructure security relies on network perimeter controls (VPCs, security groups, firewalls) or application-managed secrets (API keys in environment variables, credentials in Vault with sidecar proxies). Both approaches assume the thing behind them calls a fairly predictable set of destinations. Once a workload is running inside the perimeter, it’s implicitly trusted regardless of what it actually is, and every process sharing a service account or API key is indistinguishable from every other one holding the same credential.
That assumption breaks down hardest with AI agents. An agent decides at runtime what to call based on LLM output, so the same agent can take a different path through your infrastructure on every run, and a prompt injection can steer it toward a destination or tool call nobody intended. Static network rules and a service account shared across every agent instance can’t keep up with that, and when something does go wrong, there’s rarely a way to tell which agent, which session, or which user’s request was behind it.
Riptides replaces perimeter trust and shared credentials with identity assigned to the workload itself, whether it’s a classic service or an AI agent process:
* **Who is this?** The kernel module attests identity from process-level and environmental metadata: command name, Kubernetes labels, namespace, cgroup, cloud instance metadata. Attestation happens below the application, so a compromised process, or an agent acting on injected instructions, cannot spoof its identity. For an AI agent, that identity can be composite: the agent process, and the user or session it’s acting on behalf of, bound into the same identity, so an LLM call, an MCP tool call, and a local tool invocation all carry both.
* **Is it allowed to talk to that destination?** Policy defined as Kubernetes-style custom resources controls which identities can connect to which destinations: internal services, external APIs, or MCP servers and tool endpoints an agent calls.
* **What credentials does it need?** Credential bindings deliver short-lived, rotated credentials (cloud IAM, Vault, LLM provider API keys) directly to the kernel, so the workload’s process memory never holds a long-lived secret. There’s nothing in an agent’s context for a prompt injection or memory dump to steal.
## How it compares
[Section titled “How it compares”](#how-it-compares)
| | Riptides | Service mesh (Istio/Linkerd) | Vault + sidecar |
| -------------------------- | -------- | ---------------------------- | --------------- |
| Identity enforcement layer | Kernel | Sidecar proxy | Application |
| App changes required | None | None | Often |
| mTLS | Yes | Yes | No |
| Secretless credentials | Yes | No | Partial |
| Works on bare metal / VMs | Yes | Limited | Yes |
Riptides is not a replacement for a service mesh in all cases: if you need advanced traffic management (canary routing, retries, circuit breaking), a service mesh may be a better fit. Riptides is the right choice when you need strong workload identity, secretless credentials, or mTLS on bare metal and VM environments where sidecars are impractical.
For AI agents specifically, the comparable alternatives are an AI gateway or prompt-level guardrails, and both share the same limitation: they only see traffic that goes through them. A gateway covers the LLM calls routed through it; an agent that makes a direct connection, or that reaches an MCP server, a database, or an internal API outside the gateway’s path, bypasses it entirely. Guardrails try to stop an agent from *being told* to do something unsafe, but a credential sitting in the agent’s memory or a tool call to an unapproved endpoint doesn’t go through a prompt at all. Because Riptides enforces at the kernel, every outbound connection is covered regardless of which framework, library, or tool call initiated it, independent of whatever the agent’s LLM decided to do.
## Core components
[Section titled “Core components”](#core-components)
**Control plane**: Hosted and operated by Riptides. You manage all resources (WorkloadIdentities, Services, CredentialSources) through it using `riptides-cli ctl` and the Riptides CRDs. You don’t deploy or manage the control plane yourself.
**Daemon**: Runs on each node (as a Kubernetes DaemonSet or a systemd service on VMs). It watches the control plane for policy changes and loads them into the kernel module. The daemon handles certificate signing and credential delivery.
**Kernel module**: Loaded by the daemon on startup. It intercepts TCP connections at the socket level to enforce mTLS and inject credentials. No application changes needed.
## What you can do with Riptides
[Section titled “What you can do with Riptides”](#what-you-can-do-with-riptides)
* **Transparent mTLS**: enforce mutual TLS between any two workloads, or between agents in a multi-agent system, without changing application code or deploying sidecars
* **Secretless credentials**: workloads and AI agents call external APIs, cloud services, and LLM providers without ever holding a long-lived secret; credentials are injected at the kernel level and rotated automatically, so there’s nothing in process memory for a prompt injection or memory dump to expose
* **Per-agent identity and attribution**: every AI agent process gets its own SPIFFE identity, so multi-agent systems get agent-to-agent mutual authentication and every connection is attributable to a specific agent, session, and destination, not a shared “agent-service-account”
* **Composite identity for delegated actions**: bind the delegating user or session to the agent’s identity, so LLM calls, MCP tool calls, and local tool invocations alike carry both “which agent” and “on whose behalf,” not just which process made the call
* **Egress and tool-call control**: restrict which destinations, APIs, and MCP servers a workload or agent can reach, enforced below the application and independent of what an agent’s LLM decides to call
* **Secret manager integration**: bind secrets from any secret store to workload identities without static tokens, sidecars, or application-side SDKs
* **Cross-cluster identity federation**: workloads in different clusters, clouds, or on-premises environments trust each other’s identities via a shared trust domain
* **Zero-trust messaging and data planes**: extend mTLS and identity-based access control to brokers, queues, databases, and other infrastructure components without modifying producers or consumers
## Getting access
[Section titled “Getting access”](#getting-access)
Register for a [free account](/deployment/free-account/) to get started, or contact for a production plan. Once you have your access details, head to the [Getting Started guide](/guides/getting-started/).
# CredentialBinding
CredentialBinding binds a [CredentialSource](../credentialsource) to a workload and defines how the credential is delivered. Credentials can be injected on-the-wire (the kernel transparently rewrites HTTP headers) or made available as files on the sysfs filesystem.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `CredentialBinding`
* **Plural:** `credentialbindings`
> **Note:** CredentialBinding replaces the deprecated `WorkloadCredential` resource. All new configurations should use CredentialBinding.
## Spec
[Section titled “Spec”](#spec)
### `workloadID`
[Section titled “workloadID”](#workloadid)
| | |
| ------------ | -------- |
| **Type** | `string` |
| **Required** | Yes |
The workload ID this binding applies to. Must match the `workloadID` of an existing [WorkloadIdentity](../workloadidentity).
### `credentialSource`
[Section titled “credentialSource”](#credentialsource)
| | |
| ------------ | -------- |
| **Type** | `string` |
| **Required** | Yes |
The name of the [CredentialSource](../credentialsource) resource to bind.
### `propagation`
[Section titled “propagation”](#propagation)
| | |
| ------------ | -------- |
| **Type** | `object` |
| **Required** | Yes |
Defines how the credential is delivered to the workload. One or both of the following may be configured:
#### `propagation.injection`
[Section titled “propagation.injection”](#propagationinjection)
On-the-wire credential injection. When configured, the Riptides kernel module transparently rewrites outbound HTTP requests to inject the credential (e.g., as an `Authorization` header). Injection is activated when egress traffic matches the specified selectors.
| Field | Type | Required | Description |
| ----------- | --------------------------- | -------- | --------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `selectors` | `array` of selector objects | Yes | Label selectors that match against [Service](../service) labels. When outbound traffic targets a matching service, the credential is injected into the request. |
The selectors use the same label-matching mechanism as [Service](../service) labels. For example, `{api: openai}` matches a Service with `labels: {api: openai}`.
#### `propagation.sysfs`
[Section titled “propagation.sysfs”](#propagationsysfs)
File-based credential delivery. When configured (even as an empty object `{}`), the Riptides daemon writes credential files to a well-known sysfs path that the workload can read directly:
```plaintext
/sys/module/riptides/credentials///
```
The actual file paths are reported in the resource’s status.
## Status
[Section titled “Status”](#status)
| Field | Type | Description |
| ------------- | ----------------------- | -------------------------------------------------------------------------------------------------- |
| `state` | `string` | Current state of the binding. Valid values: `OK`, `FAILED`. |
| `message` | `string` | Human-readable message with additional detail. |
| `updateAt` | `string` (date-time) | Timestamp of the last status update. |
| `sysfs.files` | `array` of file objects | List of credential files available on sysfs (only present when `propagation.sysfs` is configured). |
### `sysfs.files[]`
[Section titled “sysfs.files\[\]”](#sysfsfiles)
| Field | Type | Description |
| ------ | -------- | -------------------------------------------------------------------- |
| `path` | `string` | Absolute filesystem path to the credential file. |
| `type` | `string` | Type of file content. Valid values: `CONFIG`, `CREDENTIAL`, `TOKEN`. |
## Examples
[Section titled “Examples”](#examples)
### Injection-only binding
[Section titled “Injection-only binding”](#injection-only-binding)
Inject a JWT credential into outbound HTTP requests targeting a specific service:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: client-jwt-binding
namespace: riptides-system
spec:
workloadID: demo/httpclient
credentialSource: my-jwt-svid
propagation:
injection:
selectors:
- service: my-backend
```
### Injection and sysfs binding
[Section titled “Injection and sysfs binding”](#injection-and-sysfs-binding)
Deliver a Vault-sourced credential both via on-the-wire injection and as a file on sysfs:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialBinding
metadata:
name: vault-api-keys-binding
namespace: riptides-system
spec:
workloadID: support-assistant/app/assistant-api
credentialSource: vault-api-keys
propagation:
injection:
selectors:
- api: openai
sysfs: {}
```
When the binding is active, the status reports the sysfs file paths:
```yaml
status:
state: OK
sysfs:
files:
- path: /sys/module/riptides/credentials/33bc2e42-24c0-5ca1-bb5b-80c2537580df/vault-api-keys-binding/token.jwt
type: TOKEN
updateAt: "2026-02-25T08:34:53.942667783Z"
```
## Usage with WorkloadIdentity
[Section titled “Usage with WorkloadIdentity”](#usage-with-workloadidentity)
CredentialBindings work in conjunction with [WorkloadIdentity](../workloadidentity) to deliver credentials transparently. The WorkloadIdentity enables TLS interception at the top level, and the CredentialBinding’s `propagation.injection.selectors` determine which outbound connections receive the credential:
```yaml
# WorkloadIdentity enables TLS interception:
connection:
tls:
mode: PERMISSIVE
intercept: true
---
# CredentialBinding targets specific services via selectors:
spec:
workloadID: my-app/workload
credentialSource: vault-api-keys
propagation:
injection:
selectors:
- api: openai # matches Service labels
```
When the workload makes an outbound connection to a service matching the injection selectors, Riptides transparently intercepts the connection and injects the bound credential.
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [CredentialSource](../credentialsource) - The credential source that this binding references.
* [WorkloadIdentity](../workloadidentity) - The workload that receives the injected credential.
* [Service](../service) - Injection selectors match against service labels.
* [API Reference Overview](../overview)
# CredentialSource
CredentialSource defines where and how credentials are obtained for workloads. It supports a wide range of credential types including Kubernetes secrets, cloud IAM federation (AWS, GCP, Azure), HashiCorp Vault, JWT minting, OAuth2 flows, and OCI.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `CredentialSource`
* **Plural:** `credentialsources`
## Spec
[Section titled “Spec”](#spec)
Exactly one credential type must be specified in the spec. The following sections describe each supported type.
***
### `kubernetes`
[Section titled “kubernetes”](#kubernetes)
Retrieves a credential from a Kubernetes Secret.
| Field | Type | Required | Description |
| ---------------- | -------- | -------- | --------------------------------------------------------- |
| `type` | `string` | Yes | Credential type. Valid options: `BearerToken`. |
| `secretRef.name` | `string` | Yes | Name of the Kubernetes Secret. |
| `secretRef.key` | `string` | Yes | Key within the Secret that contains the credential value. |
***
### `aws`
[Section titled “aws”](#aws)
Obtains temporary AWS credentials via OIDC federation (STS AssumeRoleWithWebIdentity).
| Field | Type | Required | Description |
| ----------------- | ------------------- | -------- | ----------------------------------------------------------------------------------- |
| `roleArn` | `string` | Yes | The ARN of the IAM role to assume (e.g., `arn:aws:iam::123456789012:role/my-role`). |
| `audience` | `array` of `string` | No | Audiences for the OIDC token presented to AWS STS. |
| `lifetime` | `string` | No | Requested session duration (e.g., `3600s`). |
| `idTokenLifetime` | `string` | No | Lifetime of the intermediate OIDC ID token (e.g., `300s`). |
| `idTokenClaims` | `object` | No | Additional claims to include in the OIDC ID token. |
***
### `gcp`
[Section titled “gcp”](#gcp)
Obtains GCP credentials via Workload Identity Federation.
| Field | Type | Required | Description |
| ----------------- | ------------------- | -------- | ------------------------------------------------------------------------------------------- |
| `oidcProviderId` | `string` | Yes | Full resource name of the GCP Workload Identity Pool provider. |
| `serviceAccount` | `string` | No | GCP service account email to impersonate. If omitted, uses the federated identity directly. |
| `scopes` | `array` of `string` | No | OAuth2 scopes to request (e.g., `https://www.googleapis.com/auth/cloud-platform`). |
| `lifetime` | `string` | No | Requested token lifetime (e.g., `3600s`). |
| `audience` | `array` of `string` | No | Audiences for the OIDC token. |
| `idTokenLifetime` | `string` | No | Lifetime of the intermediate OIDC ID token. |
| `idTokenClaims` | `object` | No | Additional claims to include in the OIDC ID token. |
***
### `azure`
[Section titled “azure”](#azure)
Obtains Azure AD credentials via federated identity.
| Field | Type | Required | Description |
| ----------------- | ------------------- | -------- | --------------------------------------------------------------------- |
| `clientId` | `string` | Yes | Azure AD application (client) ID. |
| `tenantId` | `string` | Yes | Azure AD tenant ID. |
| `scope` | `string` | Yes | The scope to request (e.g., `https://management.azure.com/.default`). |
| `audience` | `array` of `string` | No | Audiences for the OIDC token. |
| `idTokenLifetime` | `string` | No | Lifetime of the intermediate OIDC ID token. |
| `idTokenClaims` | `object` | No | Additional claims to include in the OIDC ID token. |
***
### `vault`
[Section titled “vault”](#vault)
Retrieves credentials from HashiCorp Vault. Riptides authenticates to Vault using a JWT and then reads from a specified secrets engine path.
| Field | Type | Required | Description |
| ------------------- | ------------------- | -------- | ---------------------------------------------------------------------------------------------------- |
| `address` | `string` | Yes | Vault server URL (e.g., `https://vault.example.com`). |
| `role` | `string` | Yes | Vault auth role name. |
| `path` | `string` | Yes | Vault secrets engine path to read from (e.g., `secret/data/myapp`). |
| `jwtAuthMethodPath` | `string` | No | Path to the JWT auth method in Vault (e.g., `jwt_prod`). If omitted, uses the default JWT auth path. |
| `audience` | `array` of `string` | No | Audiences for the JWT token presented to Vault. |
| `pollInterval` | `string` | No | How often to refresh the credential from Vault (e.g., `60s`). |
| `idTokenLifetime` | `string` | No | Lifetime of the JWT used for Vault authentication. |
| `idTokenClaims` | `object` | No | Additional claims in the JWT for Vault auth. |
| `type` | `object` | No | Specifies how to handle the secret returned by Vault. See below. |
#### `vault.type`
[Section titled “vault.type”](#vaulttype)
Defines the format of the credential returned by Vault and how Riptides should process it. Exactly one sub-field may be set:
* **`token`** - The Vault response contains a token or API key.
* `source` (`string`, required) - The key in the Vault response JSON that contains the token value (e.g., `api_key`).
* **`aws`** - The Vault response contains AWS credentials (from the AWS secrets engine). No additional configuration needed.
* **`gcp`** - The Vault response contains GCP credentials. One of:
* `accessToken` - Treat the response as a GCP access token. No additional fields.
* `serviceAccountKey` - Treat the response as a GCP service account key.
* `scopes` (`array` of `string`) - OAuth2 scopes to request when minting an access token from the key.
* **`azure`** - The Vault response contains Azure credentials.
* `tenantId` (`string`, required) - Azure AD tenant ID.
* `scopes` (`array` of `string`) - Scopes for minting the access token.
***
### `jwt`
[Section titled “jwt”](#jwt)
Mints a JWT credential using the workload’s SPIFFE identity. Useful for service-to-service authentication where the consumer expects a JWT.
| Field | Type | Required | Description |
| ---------- | ------------------- | -------- | ------------------------------------------------------- |
| `audience` | `array` of `string` | Yes | Audiences to include in the JWT `aud` claim. |
| `lifetime` | `string` | No | Token lifetime (e.g., `60s`). |
| `claims` | `object` | No | Additional custom claims to include in the JWT payload. |
***
### `oa2cc`
[Section titled “oa2cc”](#oa2cc)
Obtains an access token using the OAuth2 Client Credentials grant.
| Field | Type | Required | Description |
| ------------------ | ------------------- | -------- | ---------------------------------------------------------------- |
| `tokenEndpointUrl` | `string` | Yes | Token endpoint URL of the authorization server. |
| `secretRef.name` | `string` | Yes | Kubernetes Secret containing the client credentials. |
| `secretRef.key` | `string` | Yes | Key within the Secret. |
| `scopes` | `array` of `string` | No | OAuth2 scopes to request. |
| `authStyle` | `string` | No | How to send client credentials. Valid options: `HEADER`, `BODY`. |
| `additionalParams` | `map` of `string` | No | Additional parameters to include in the token request. |
***
### `oa2ac`
[Section titled “oa2ac”](#oa2ac)
Obtains an access token using the OAuth2 Authorization Code grant.
| Field | Type | Required | Description |
| -------------------------- | ------------------- | -------- | ---------------------------------------------------------------- |
| `authorizationEndpointUrl` | `string` | Yes | Authorization endpoint URL. |
| `tokenEndpointUrl` | `string` | Yes | Token endpoint URL. |
| `secretRef.name` | `string` | Yes | Kubernetes Secret containing the client credentials. |
| `secretRef.key` | `string` | Yes | Key within the Secret. |
| `scopes` | `array` of `string` | No | OAuth2 scopes to request. |
| `usePkce` | `boolean` | No | Enable PKCE (Proof Key for Code Exchange). |
| `authStyle` | `string` | No | How to send client credentials. Valid options: `HEADER`, `BODY`. |
| `additionalParams` | `map` of `string` | No | Additional parameters for the token request. |
***
### `oci`
[Section titled “oci”](#oci)
Obtains credentials from Oracle Cloud Infrastructure (OCI) Identity Domains.
| Field | Type | Required | Description |
| ------------------- | -------- | -------- | ------------------------------------------- |
| `region` | `string` | Yes | OCI region (e.g., `us-ashburn-1`). |
| `clientId` | `string` | Yes | OIDC client ID. |
| `clientSecret` | `string` | Yes | OIDC client secret. |
| `identityDomainUrl` | `string` | Yes | OCI Identity Domain URL. |
| `tenancyOcid` | `string` | Yes | OCI tenancy OCID. |
| `idTokenLifetime` | `string` | No | Lifetime of the intermediate OIDC ID token. |
| `idTokenClaims` | `object` | No | Additional claims in the OIDC ID token. |
## Status
[Section titled “Status”](#status)
| Field | Type | Description |
| --------- | -------- | --------------------------------------------------------------------------------- |
| `state` | `string` | Current state of the credential source. Valid values: `AVAILABLE`, `UNAVAILABLE`. |
| `message` | `string` | Human-readable message providing additional detail about the current state. |
## Examples
[Section titled “Examples”](#examples)
### Kubernetes BearerToken from a Secret
[Section titled “Kubernetes BearerToken from a Secret”](#kubernetes-bearertoken-from-a-secret)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: my-api-bearer
namespace: riptides-system
spec:
kubernetes:
type: BearerToken
secretRef:
name: my-api-key
key: token
```
### AWS IAM role via OIDC federation
[Section titled “AWS IAM role via OIDC federation”](#aws-iam-role-via-oidc-federation)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: aws-cred-source
namespace: riptides-system
spec:
aws:
roleArn: arn:aws:iam::123456789012:role/my-workload-role
```
### GCP Workload Identity Federation
[Section titled “GCP Workload Identity Federation”](#gcp-workload-identity-federation)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: gcp-cred-source
namespace: riptides-system
spec:
gcp:
oidcProviderId: //iam.googleapis.com/projects/123456789012/locations/global/workloadIdentityPools/my-pool/providers/my-provider
serviceAccount: my-service@my-project.iam.gserviceaccount.com
scopes:
- https://www.googleapis.com/auth/cloud-platform
lifetime: 3600s
```
### JWT credential
[Section titled “JWT credential”](#jwt-credential)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: my-jwt-svid
namespace: riptides-system
spec:
jwt:
audience:
- https://api.example.com
claims:
custom: value
lifetime: 60s
```
### HashiCorp Vault (token type)
[Section titled “HashiCorp Vault (token type)”](#hashicorp-vault-token-type)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: CredentialSource
metadata:
name: vault-api-keys
namespace: riptides-system
spec:
vault:
address: https://vault.example.com
role: my-api-keys
path: secret/creds/my-role
jwtAuthMethodPath: jwt_prod
audience:
- vault.example.com
type:
token:
source: api_key
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [CredentialBinding](../credentialbinding) - Bind this credential source to a workload for delivery.
* [WorkloadIdentity](../workloadidentity) - The workload that receives injected credentials.
* [API Reference Overview](../overview)
# Daemon
A Daemon represents a registered node running the Riptides daemon. Daemons are automatically created when a node connects to the control plane and successfully authenticates through a [Verifier](../verifier).
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `Daemon`
* **Plural:** `daemons`
## Spec
[Section titled “Spec”](#spec)
### `workloadID`
[Section titled “workloadID”](#workloadid)
* **Type:** `string`
* **Required:** Yes
The unique workload identity assigned to this daemon. Typically follows the pattern `riptides/daemon///`, derived from the verifier’s `workloadIDTemplate` or set explicitly during registration.
### `claimerType`
[Section titled “claimerType”](#claimertype)
* **Type:** `string`
* **Required:** Yes
The authentication method the daemon used to register with the control plane. Corresponds to one of the supported [Verifier](../verifier) types: `AWSIID`, `GCPIIT`, `JoinToken`, `X509CertPOP`, `SSHCertPOP`, `K8sSAT`, or `JWT`.
### `ephemeral`
[Section titled “ephemeral”](#ephemeral)
* **Type:** `boolean`
* **Required:** No (defaults to `false`)
Whether the daemon is ephemeral. Ephemeral daemons are automatically garbage-collected by the control plane once they stop heart-beating, so short-lived workloads (such as CI/CD runners) don’t leave stale entries behind. Daemons registered via a short-lived attestation type (e.g. GitHub Actions) default to `true`; a daemon can set this explicitly at join via the `--ephemeral` flag on `riptides daemon auth` (or `config.daemon.ephemeral`).
### `heartbeatTimeoutSeconds`
[Section titled “heartbeatTimeoutSeconds”](#heartbeattimeoutseconds)
* **Type:** `integer`
* **Required:** No
Per-daemon staleness window, in seconds, after which an ephemeral daemon is reaped. `0` (the default) uses the control-plane default.
## Status
[Section titled “Status”](#status)
Status fields are populated and managed by the control plane. They are read-only.
### `health`
[Section titled “health”](#health)
* **Type:** `object`
Reports the current health of the daemon and its kernel-level driver.
| Field | Type | Description |
| -------------- | -------- | -------------------------------------------------- |
| `daemonHealth` | `string` | Health status of the userspace daemon (e.g., `ok`) |
| `driverHealth` | `string` | Health status of the kernel driver (e.g., `ok`) |
| `lastProbeAt` | `string` | Timestamp of the last health check |
### `metadata`
[Section titled “metadata”](#metadata)
* **Type:** `array` of `{name, value}` objects
A flat list of key-value pairs describing the node. The metadata collected depends on the `claimerType` and the environment the daemon runs in. Common metadata categories include:
| Prefix | Description |
| ------------ | ------------------------------------------------------------------------------- |
| `awsiid:*` | AWS Instance Identity Document fields (account ID, region, instance type, etc.) |
| `gcpiit:*` | GCP Instance Identity Token fields (project ID, zone, instance name, etc.) |
| `ec2:*` | EC2 instance metadata (AMI, network, placement) |
| `gcp:*` | GCP instance metadata (machine type, image, network) |
| `linuxos:*` | Linux OS information (kernel release, distribution name and version) |
| `node:*` | Generic node info (hostname, architecture, network interfaces, OS type) |
| `status:*` | Daemon and driver version information |
| `sysfsdmi:*` | DMI/SMBIOS hardware information (BIOS vendor, product name) |
### `exposedEndpoints`
[Section titled “exposedEndpoints”](#exposedendpoints)
* **Type:** `map[string]string`
Endpoints exposed by the daemon, such as Prometheus metrics exporters. Keys are endpoint names, values are listen addresses.
## Example
[Section titled “Example”](#example)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Daemon
metadata:
name: 78e58ba0-275e-4dc2-876b-ae7f066d300d
namespace: riptides-system
spec:
claimerType: AWSIID
workloadID: riptides/daemon/123456789012/eu-west-1/i-0123456789abcdef0
status:
exposedEndpoints:
prom-metr-exp-addr: "[::]:50003"
health:
daemonHealth: ok
driverHealth: ok
lastProbeAt: "20260313T131417Z"
metadata:
- name: workload:id
value: 123456789012/eu-west-1/i-0123456789abcdef0
- name: awsiid:account:id
value: "123456789012"
- name: awsiid:architecture
value: x86_64
- name: awsiid:availability:zone
value: eu-west-1b
- name: awsiid:image:id
value: ami-0123456789abcdef0
- name: awsiid:instance:id
value: i-0123456789abcdef0
- name: awsiid:instance:type
value: t3.xlarge
- name: awsiid:private_ip
value: 10.0.1.100
- name: awsiid:region
value: eu-west-1
- name: linuxos:name
value: amazon
- name: linuxos:version
value: Amazon Linux 2023.9.20251208
- name: node:hostname
value: ip-10-0-1-100.eu-west-1.compute.internal
- name: node:kernel:arch
value: x86_64
- name: node:os:type
value: linux
- name: status:daemon:version
value: v0.5.10
- name: status:driver:version
value: v0.5.13
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [Verifier](../verifier) - defines how daemons authenticate with the control plane
* [Claim](../claim) - represents a daemon’s authentication attempt
* [DaemonGroup](../daemongroup) - groups daemons by metadata selectors
# DaemonGroup
A DaemonGroup defines a logical group of daemons selected by metadata key-value pairs. DaemonGroups are used to target sets of nodes when configuring workload identities and security policies.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `DaemonGroup`
* **Plural:** `daemongroups`
## Spec
[Section titled “Spec”](#spec)
### `workloadID`
[Section titled “workloadID”](#workloadid)
* **Type:** `string`
* **Required:** Yes
The workload identity assigned to this group. All daemons matching the selectors are associated with this identity. Must start with `daemongroup/` — follows a pattern like `daemongroup/` or a custom hierarchy such as `daemongroup//`.
### `selectors`
[Section titled “selectors”](#selectors)
* **Type:** `array` of objects (free-form key-value pairs)
* **Required:** Yes
A list of metadata selectors that determine which daemons belong to this group. Each selector is an object with a single key-value pair that is matched against daemon metadata. A daemon matches the group if it matches **any** of the selectors (OR logic).
Common selector keys:
| Key | Description |
| ------------------- | -------------------------------------------------------------------------------------------- |
| `linuxos:name` | Match daemons running a specific Linux distribution (`ubuntu`, `amazon`, `fedora`, `alpine`) |
| `awsiid:account:id` | Match daemons in a specific AWS account |
| `gcpiit:project:id` | Match daemons in a specific GCP project |
| `node:os:type` | Match by OS type (e.g., `linux`) |
## Status
[Section titled “Status”](#status)
Status fields are managed by the control plane and are read-only.
### `daemons`
[Section titled “daemons”](#daemons)
* **Type:** `array` of objects
Lists the daemons currently matched by this group’s selectors.
| Field | Type | Description |
| ---------------- | -------- | ------------------------------- |
| `name` | `string` | The daemon resource name (UUID) |
| `uuid` | `string` | The daemon’s Kubernetes UID |
| `workloadId` | `string` | The daemon’s workload identity |
| `workloadIdHash` | `string` | Hash of the workload identity |
## Example
[Section titled “Example”](#example)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: DaemonGroup
metadata:
name: linux-workers
namespace: riptides-system
spec:
selectors:
- linuxos:name: ubuntu
- linuxos:name: fedora
- linuxos:name: alpine
- linuxos:name: amazon
workloadID: daemongroup/linux-workers
status:
daemons:
- name: a1b2c3d4-e5f6-7890-abcd-ef1234567890
uuid: 12345678-abcd-ef01-2345-6789abcdef01
workloadId: riptides/daemon/123456789012/eu-west-1/i-0123456789abcdef0
workloadIdHash: d2d035b1-0feb-50e4-a48a-eb4628d3d7f2
- name: b2c3d4e5-f678-9012-bcde-f12345678901
uuid: 23456789-bcde-f012-3456-789abcdef012
workloadId: riptides/daemon/123456789012/eu-west-1/i-0abcdef1234567890
workloadIdHash: 88c57928-17e8-533f-8807-45f1e6f8cb43
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [Daemon](../daemon) - the individual daemons that are grouped
* [WorkloadIdentity](../workloadidentity) - uses DaemonGroups to scope identity and policy
# IdentityProvider
An IdentityProvider configures an external identity source for user authentication to the Riptides UI and API. This is separate from daemon authentication - IdentityProviders handle human user login via OAuth2/OIDC flows, while [Verifiers](verifier.md) handle machine-to-control-plane authentication.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `IdentityProvider`
* **Plural:** `identityproviders`
## Spec
[Section titled “Spec”](#spec)
### `name`
[Section titled “name”](#name)
* **Type:** `string`
* **Required:** Yes
A human-readable display name for the identity provider (e.g., `"GitHub"`, `"Google"`). Shown in the login UI.
The spec must include exactly **one** of the following provider configurations.
### `github`
[Section titled “github”](#github)
* **Type:** `object`
Authenticate users via GitHub OAuth.
| Field | Type | Required | Description |
| -------------- | ------------------ | -------- | -------------------------------------------- |
| `clientID` | `string` | Yes | GitHub OAuth app client ID |
| `clientSecret` | `string` | Yes | GitHub OAuth app client secret |
| `requiredOrgs` | `array` of objects | Yes | GitHub organizations the user must belong to |
Each entry in `requiredOrgs`:
| Field | Type | Required | Description |
| ------- | ------------------- | -------- | ------------------------------------------------------------------------------- |
| `name` | `string` | Yes | GitHub organization name |
| `teams` | `array` of `string` | No | Specific teams within the organization (if omitted, any org member is accepted) |
### `google`
[Section titled “google”](#google)
* **Type:** `object`
Authenticate users via Google OAuth.
| Field | Type | Required | Description |
| ----------------------- | ------------------- | -------- | ----------------------------------------------------------- |
| `clientID` | `string` | Yes | Google OAuth client ID |
| `clientSecret` | `string` | Yes | Google OAuth client secret |
| `requiredHostedDomains` | `array` of `string` | Yes | Restrict login to users from these Google Workspace domains |
### `bitbucket`
[Section titled “bitbucket”](#bitbucket)
* **Type:** `object`
Authenticate users via Bitbucket OAuth.
| Field | Type | Required | Description |
| -------------- | -------- | -------- | ------------------------------- |
| `clientID` | `string` | Yes | Bitbucket OAuth consumer key |
| `clientSecret` | `string` | Yes | Bitbucket OAuth consumer secret |
### `static`
[Section titled “static”](#static)
* **Type:** `object`
A static user identity for development and testing. Not intended for production use.
| Field | Type | Required | Description |
| ------------------- | ------------------- | -------- | -------------------- |
| `email` | `string` | Yes | User’s email address |
| `name` | `string` | Yes | User’s display name |
| `givenName` | `string` | No | First name |
| `familyName` | `string` | No | Last name |
| `nickname` | `string` | No | Nickname |
| `preferredUsername` | `string` | No | Preferred username |
| `groups` | `array` of `string` | No | Group memberships |
## Status
[Section titled “Status”](#status)
| Field | Type | Description |
| --------- | -------- | ------------------------------------------- |
| `state` | `string` | One of `Unspecified`, `Available`, `Failed` |
| `message` | `string` | Human-readable message (set on failure) |
## Example
[Section titled “Example”](#example)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: IdentityProvider
metadata:
name: github
namespace: riptides-system
spec:
name: GitHub
github:
clientID:
clientSecret:
requiredOrgs:
- name: your-organization
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [OIDCClient](../oidcclient) - defines the OIDC client that works with identity providers for user login
# JoinToken
A JoinToken defines a pre-shared secret token that daemons can use to authenticate with the Riptides control plane. JoinTokens provide a simple onboarding mechanism suitable for initial setup, development environments, or scenarios where platform-native identity (AWS IAM, GCP identity) is not available.
**A JoinToken is single-use.** The control plane deletes the JoinToken object the moment a daemon successfully authenticates with it. A second daemon presenting the same token value afterwards is rejected. Do not share one JoinToken across multiple daemons — for example, do not configure every pod of a Kubernetes DaemonSet with the same token; only the first pod to register will succeed, and the rest will fail authentication. Create one JoinToken per daemon, or for Kubernetes deployments use the [K8sSAT verifier](../verifier#k8ssat) instead, which authenticates each node automatically from its own projected ServiceAccount token.
* **API Group:** `auth.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `JoinToken`
* **Plural:** `jointokens`
## Spec
[Section titled “Spec”](#spec)
### `token`
[Section titled “token”](#token)
* **Type:** `string`
* **Required:** Yes
The secret token value. Daemons must present this exact value to authenticate. Treat this as a credential — avoid committing it to version control. The JoinToken object is deleted as soon as a daemon successfully authenticates with it, so each token can only be used once.
### `workloadID`
[Section titled “workloadID”](#workloadid)
* **Type:** `string`
* **Required:** No
The workload identity to assign to daemons that authenticate with this token. If not set, the daemon’s workload ID is derived from the associated [Verifier](../verifier)’s `workloadIDTemplate`.
### `expireAt`
[Section titled “expireAt”](#expireat)
* **Type:** `string` (RFC 3339 date-time)
* **Required:** No
Expiration timestamp for the token. After this time, the token is no longer accepted. If omitted, the token does not expire automatically.
## Example
[Section titled “Example”](#example)
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: JoinToken
metadata:
name: dev-onboarding-token
namespace: riptides-system
spec:
token: "my-secret-join-token-value"
workloadID: riptides/daemon/dev/onboarding-node
expireAt: "2026-06-01T00:00:00Z"
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [Verifier](../verifier) - a Verifier with `joinToken` type processes these tokens
* [Claim](../claim) - created when a daemon presents a join token
* [Daemon](../daemon) - created after successful authentication
# OIDCClient
An OIDCClient defines an OpenID Connect client used for user authentication to the Riptides UI and API. It works alongside [IdentityProviders](../identityprovider) to enable OAuth2/OIDC login flows.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `OIDCClient`
* **Plural:** `oidcclients`
## Spec
[Section titled “Spec”](#spec)
### `redirectUrls`
[Section titled “redirectUrls”](#redirecturls)
* **Type:** `array` of `string`
* **Required:** Yes
The allowed OAuth2 redirect URIs. After authentication, the identity provider redirects the user back to one of these URLs. Must match the URLs configured in your application or UI.
The spec must include exactly **one** of the following client type configurations.
### `native`
[Section titled “native”](#native)
* **Type:** `object` (empty)
A built-in OIDC client configuration suitable for the Riptides UI and CLI. No additional fields are required - the control plane manages the client credentials automatically.
### `custom`
[Section titled “custom”](#custom)
* **Type:** `object`
A custom OIDC client for advanced use cases or third-party integrations.
| Field | Type | Required | Description |
| ----------------- | ------------------- | -------- | ------------------------------- |
| `grantTypes` | `array` of `string` | No | Allowed OAuth2 grant types |
| `authMethod` | `string` | No | Client authentication method |
| `accessTokenType` | `string` | No | Type of access token to issue |
| `applicationType` | `string` | No | Application type classification |
**Grant type options:** `GRANT_TYPE_AUTHORIZATION_CODE`, `GRANT_TYPE_REFRESH_TOKEN`, `GRANT_TYPE_CLIENT_CREDENTIALS`, `GRANT_TYPE_JWT_BEARER`, `GRANT_TYPE_TOKEN_EXCHANGE`, `GRANT_TYPE_IMPLICIT`, `GRANT_TYPE_DEVICE_CODE`
**Auth method options:** `AUTH_METHOD_CLIENT_SECRET_BASIC`, `AUTH_METHOD_CLIENT_SECRET_POST`, `AUTH_METHOD_NONE`, `AUTH_METHOD_PRIVATE_KEY_JWT`
**Access token type options:** `ACCESS_TOKEN_TYPE_BEARER`, `ACCESS_TOKEN_TYPE_JWT`
**Application type options:** `APPLICATION_TYPE_WEB`, `APPLICATION_TYPE_USER_AGENT`, `APPLICATION_TYPE_NATIVE`
## Example
[Section titled “Example”](#example)
### Native Client (Riptides UI)
[Section titled “Native Client (Riptides UI)”](#native-client-riptides-ui)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: OIDCClient
metadata:
name: riptides-ui
namespace: riptides-system
spec:
native: {}
redirectUrls:
- https://app.example.com/callback
- https://app.example.com/ui/callback
```
### Custom Client
[Section titled “Custom Client”](#custom-client)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: OIDCClient
metadata:
name: custom-integration
namespace: riptides-system
spec:
custom:
grantTypes:
- GRANT_TYPE_AUTHORIZATION_CODE
- GRANT_TYPE_REFRESH_TOKEN
authMethod: AUTH_METHOD_CLIENT_SECRET_BASIC
accessTokenType: ACCESS_TOKEN_TYPE_JWT
applicationType: APPLICATION_TYPE_WEB
redirectUrls:
- https://integration.example.com/oauth/callback
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [IdentityProvider](../identityprovider) - configures the external identity source used with OIDC clients
# API Reference
Riptides exposes a declarative, Kubernetes-style API built on Custom Resource Definitions (CRDs). You manage workload identities, credential sources, credential bindings, and service definitions as standard Kubernetes resources using [`riptides-cli ctl`](../../deployment/cli).
## API Groups
[Section titled “API Groups”](#api-groups)
Riptides organizes its resources into three API groups:
| API Group | Description |
| -------------------- | ------------------------------------------------------------------------------------------------------------------------- |
| `core.riptides.io` | Primary resources for workload identity, credentials, and service definitions. |
| `auth.riptides.io` | Authentication primitives such as join tokens, and verifiers. |
| `crypto.riptides.io` | Cryptographic material management (certificates, keys). These resources are system-managed and not typically user-facing. |
## Version
[Section titled “Version”](#version)
All resources are currently served at version **v1alpha1**.
## Resource Reference
[Section titled “Resource Reference”](#resource-reference)
| Resource | API Group | Kind | Description |
| ----------------------------------------- | ------------------ | ------------------- | ---------------------------------------------------------------------------------------------------------------------------------------------------- |
| [WorkloadIdentity](../workloadidentity) | `core.riptides.io` | `WorkloadIdentity` | Defines a cryptographic identity for a workload, including its SPIFFE ID, selectors, TLS policy, and allowed communication peers. |
| [CredentialSource](../credentialsource) | `core.riptides.io` | `CredentialSource` | Defines where and how credentials are obtained - from Kubernetes secrets, cloud IAM (AWS, GCP, Azure), HashiCorp Vault, JWT minting, OAuth2, or OCI. |
| [CredentialBinding](../credentialbinding) | `core.riptides.io` | `CredentialBinding` | Binds a CredentialSource to a workload and defines how credentials are delivered (on-the-wire injection or sysfs files). |
| [Service](../service) | `core.riptides.io` | `Service` | Defines a network service (internal or external) that workloads connect to, used for egress policy matching. |
| Daemon | `core.riptides.io` | `Daemon` | Represents a Riptides daemon running on a node. |
| DaemonGroup | `core.riptides.io` | `DaemonGroup` | Groups daemons for scoping workload identity assignments. |
| JoinToken | `auth.riptides.io` | `JoinToken` | Bootstrap token used by daemons to join the control plane. |
| Verifier | `auth.riptides.io` | `Verifier` | Defines how identity claims are verified. |
| IdentityProvider | `core.riptides.io` | `IdentityProvider` | Configures an external identity provider for OIDC federation. |
| OIDCClient | `core.riptides.io` | `OIDCClient` | Registers an OIDC client for token exchange. |
> **Note:** Resources in the `crypto.riptides.io` group are managed automatically by the Riptides control plane and do not require direct user interaction under normal operation.
## Namespace
[Section titled “Namespace”](#namespace)
All Riptides CRDs are namespaced. By convention, resources are created in the `riptides-system` namespace.
## Deprecation Notice
[Section titled “Deprecation Notice”](#deprecation-notice)
The `WorkloadCredential` resource is deprecated. Use [CredentialBinding](../credentialbinding) instead to bind credentials to workloads.
# Service
Service defines a network service that workloads connect to. Services can be internal (within the infrastructure) or external (third-party APIs, cloud services). Their labels are used by [WorkloadIdentity](../workloadidentity) egress selectors and [CredentialBinding](../credentialbinding) injection selectors to match outbound traffic to the correct policy and credentials.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `Service`
* **Plural:** `services`
## Spec
[Section titled “Spec”](#spec)
### `labels`
[Section titled “labels”](#labels)
| | |
| ------------ | ----------------------------- |
| **Type** | `map` of `string` to `string` |
| **Required** | Yes |
Labels identify this service for matching by egress selectors in WorkloadIdentity and CredentialBinding resources. When an egress selector specifies `{api: openai}`, it matches any Service with a `labels` entry of `api: openai`.
### `addresses`
[Section titled “addresses”](#addresses)
| | |
| ------------ | -------------------------- |
| **Type** | `array` of address objects |
| **Required** | No |
The network addresses where this service is reachable. Each address entry contains:
| Field | Type | Required | Description |
| ----------------- | ------------------- | -------- | ------------------------------------------------------------------------------------------------------------------------------------------------------------- |
| `address` | `string` | Yes | Hostname, FQDN, wildcard FQDN (`*.example.com`), or IP address of the service endpoint. |
| `port` | `integer` | No | Port number the service listens on. |
| `aliases` | `array` of `string` | No | Alternative hostnames or FQDNs that resolve to this address. |
| `networkPrefixes` | `array` of `string` | No | Explicit CIDR ranges (e.g. `10.0.0.0/16`) that this address’s network resolves to. |
| `networkNames` | `array` of `string` | No | Symbolic, provider-backed names (see [Known network names](#known-network-names)) that the daemon resolves to that provider’s published IP ranges at runtime. |
A service can have multiple addresses, for example when it is reachable on different ports or through different DNS names.
#### Wildcard addresses
[Section titled “Wildcard addresses”](#wildcard-addresses)
A wildcard `address` (e.g. `*.s3.amazonaws.com`) is not directly resolvable to a concrete IP, so it cannot be enforced from DNS lookups alone. Any such address must also set `networkPrefixes` or `networkNames`, so the daemon knows the concrete network range the wildcard covers. This is validated at admission time: a wildcard address without one of these fields is rejected.
The only exception is a small set of well-known provider wildcards, including `*.amazonaws.com`, `*.amazonaws.cn`, `*.amazonaws.com.cn`, and `*.googleapis.com`, which are recognized automatically and don’t require `networkPrefixes` or `networkNames`.
#### Known network names
[Section titled “Known network names”](#known-network-names)
Each entry in `networkNames` is either just a provider name (matching every published IP range for that provider) or `:` (matching only the named type within that provider). Ranges are kept up to date automatically by the daemon.
| Provider | Types | Notes |
| -------------- | ------------------------------------------------------------------------------------------------------------------------------------------------ | ------------------------------------------------------------------------------------------------------------------------------------------------------------ |
| `aws` | Per-service, e.g. `s3`, `ec2`, `cloudfront`, `route53`, `dynamodb` | Sourced from AWS’s published `ip-ranges.json`. The full set of service names is defined by AWS and changes over time; `aws` alone matches every AWS service. |
| `azure` | Per service tag, e.g. `storage`, `sql`, `app_service` | Sourced from Azure’s published Service Tags file. Tag names are defined by Azure (converted to `snake_case`); `azure` alone matches every tag. |
| `google` | `service` | Google’s own service IP ranges (Search, Gmail, etc.), from `goog.json`. |
| `google-cloud` | `cloud` | Google Cloud Platform customer-facing IP ranges, from `cloud.json`. |
| `github` | `hooks`, `web`, `api`, `git`, `github_enterprise_importer`, `packages`, `pages`, `importer`, `actions`, `actions_macos`, `codespaces`, `copilot` | Sourced from GitHub’s published meta API. |
For example, `networkNames: [aws:s3]` matches only S3’s IP ranges, while `networkNames: [aws]` matches every AWS service’s ranges.
### `external`
[Section titled “external”](#external)
| | |
| ------------ | -------------------- |
| **Type** | `boolean` (nullable) |
| **Required** | No |
Indicates whether this service is external to the infrastructure.
* **`true`**: The service is external (e.g., a third-party API like `api.openai.com`, a cloud service like `s3.amazonaws.com`). External services are typically accessed over the public internet and use `SIMPLE` TLS in egress rules.
* **`false`** or omitted: The service is internal (e.g., `redis-cart.myapp.svc.cluster.local`). Internal services are within the same infrastructure and typically use `MUTUAL` or `PERMISSIVE` TLS.
## Status
[Section titled “Status”](#status)
Service resources do not expose a status subresource.
## Examples
[Section titled “Examples”](#examples)
### External service (cloud API)
[Section titled “External service (cloud API)”](#external-service-cloud-api)
Define an external API service that workloads connect to with credential injection:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: openai-svc
namespace: riptides-system
spec:
addresses:
- address: api.openai.com
port: 443
external: true
labels:
api: openai
```
### External service (AWS)
[Section titled “External service (AWS)”](#external-service-aws)
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: bedrock-runtime
namespace: riptides-system
spec:
addresses:
- address: bedrock-agent-runtime.us-east-1.amazonaws.com
port: 443
external: true
labels:
app: bedrock-demo
service: bedrock-agent-runtime
```
### Internal service (Kubernetes)
[Section titled “Internal service (Kubernetes)”](#internal-service-kubernetes)
Define an internal service within the cluster:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: my-postgres
namespace: riptides-system
spec:
addresses:
- address: postgres-service.myapp.svc.cluster.local
port: 5432
external: false
labels:
app: postgres
```
### External service with a wildcard address
[Section titled “External service with a wildcard address”](#external-service-with-a-wildcard-address)
`*.s3.amazonaws.com` isn’t one of the automatically recognized provider wildcards, so `networkNames` must be set to tell the daemon which provider’s IP ranges to enforce against:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: aws-s3-buckets
namespace: riptides-system
spec:
addresses:
- address: "*.s3.amazonaws.com"
port: 443
networkNames:
- aws:s3
external: true
labels:
provider: aws
type: storage
```
### Internal service with multiple addresses
[Section titled “Internal service with multiple addresses”](#internal-service-with-multiple-addresses)
A service reachable on multiple ports through different DNS names:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: Service
metadata:
name: my-elasticsearch
namespace: riptides-system
spec:
addresses:
- address: elasticsearch.myapp.svc.cluster.local
port: 9200
- address: elasticsearch.myapp.svc.cluster.local
port: 9300
labels:
app: elasticsearch
```
## How Services Connect to Egress Rules
[Section titled “How Services Connect to Egress Rules”](#how-services-connect-to-egress-rules)
Services are not referenced by name from WorkloadIdentity or CredentialBinding. Instead, egress selectors match against service **labels**. This decouples identity policy from specific service definitions.
For example, given the `openai-svc` Service above with `labels: {api: openai}`, a CredentialBinding can target it via injection selectors as follows:
```yaml
# In a CredentialBinding spec:
propagation:
injection:
selectors:
- api: openai # matches any Service with label api=openai
```
WorkloadIdentity egress rules can also target services by label for connection policy overrides:
```yaml
# In a WorkloadIdentity spec:
egress:
- selectors:
- api: openai # matches any Service with label api=openai
connection:
tls:
mode: SIMPLE
```
This label-based matching allows you to update service addresses or add new endpoints without modifying identity policies.
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [WorkloadIdentity](../workloadidentity): Egress selectors match against service labels.
* [CredentialBinding](../credentialbinding): Injection selectors match against service labels.
* [CredentialSource](../credentialsource): Provides the credentials injected into service connections.
* [API Reference Overview](../overview)
# Verifier
A Verifier defines how daemons prove their identity when connecting to the Riptides control plane. Each Verifier targets a specific authentication mechanism and can filter incoming daemons by required metadata and automatically assign workload identities.
* **API Group:** `auth.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `Verifier`
* **Plural:** `verifiers`
## Spec
[Section titled “Spec”](#spec)
The spec must include exactly **one** of the following authentication method fields. Optionally, `requiredMetadata` and `workloadIDTemplate` can be set alongside any method.
### Authentication Methods
[Section titled “Authentication Methods”](#authentication-methods)
#### `AWSIID`
[Section titled “AWSIID”](#awsiid)
* **Type:** `object`
Verifies daemons using the AWS EC2 Instance Identity Document. The daemon presents a signed document from the EC2 metadata service, and the control plane validates the signature against AWS public certificates. No additional configuration is required on the object itself - use `requiredMetadata` to restrict which AWS accounts, regions, or instance types are accepted.
#### `GCPIIT`
[Section titled “GCPIIT”](#gcpiit)
* **Type:** `object`
Verifies daemons using a Google Cloud Instance Identity Token (a JWT signed by Google).
| Field | Type | Required | Description |
| -------------- | -------- | -------- | ---------------------------------------------------- |
| `audience` | `string` | No | Expected audience claim in the token |
| `jwksURL` | `string` | No | Custom JWKS URL for token verification |
| `jwksCacheTTL` | `string` | No | Cache duration for JWKS keys (e.g., `300s`) |
| `iatLeeway` | `string` | No | Allowed clock skew for the `iat` claim (e.g., `60s`) |
#### `AzureIMDS`
[Section titled “AzureIMDS”](#azureimds)
* **Type:** `object`
Verifies daemons using an Azure Instance Metadata Service (IMDS) managed-identity token (a JWT).
| Field | Type | Required | Description |
| -------------- | -------- | -------- | ---------------------------------------------------------------------------------------- |
| `resource` | `string` | No | Expected resource/audience claim in the token (default: `https://management.azure.com/`) |
| `jwksURL` | `string` | No | Custom JWKS URL for token verification |
| `jwksCacheTTL` | `string` | No | Cache duration for JWKS keys (e.g., `300s`) |
| `iatLeeway` | `string` | No | Allowed clock skew for the `iat` claim (e.g., `60s`) |
Danger
`requiredMetadata` is required for AzureIMDS verifiers. Omitting it causes the Verifier to be rejected at admission time. Without it, any Azure VM or managed identity could authenticate.
#### `joinToken`
[Section titled “joinToken”](#jointoken)
* **Type:** `object`
Verifies daemons using a pre-shared [JoinToken](jointoken.md). Useful for initial setup, development, or environments where platform-native identity is unavailable. No additional fields - the token itself is defined in a separate JoinToken resource.
#### `K8sSAT`
[Section titled “K8sSAT”](#k8ssat)
* **Type:** `object`
Verifies daemons using a Kubernetes Service Account Token.
| Field | Type | Required | Description |
| ------------ | -------- | -------- | ------------------------------------------------------------------------------------------------------- |
| `clusterID` | `string` | Yes | Identifier for the Kubernetes cluster |
| `jwksSource` | `object` | Yes | Source of JWKS for token validation. One of `inline` (string) or `remote` (`{url, minRefreshInterval}`) |
| `audience` | `string` | No | Expected audience claim |
| `iatLeeway` | `string` | No | Allowed clock skew for `iat` (e.g., `60s`) |
#### `X509CertPOP`
[Section titled “X509CertPOP”](#x509certpop)
* **Type:** `object`
Verifies daemons by X.509 certificate proof of possession.
| Field | Type | Required | Description |
| ------------------ | -------- | -------- | -------------------------------------------------------------------- |
| `caCertificatePEM` | `string` | Yes | PEM-encoded CA certificate used to validate the daemon’s certificate |
#### `SSHCertPOP`
[Section titled “SSHCertPOP”](#sshcertpop)
* **Type:** `object`
Verifies daemons by SSH certificate proof of possession.
| Field | Type | Required | Description |
| -------------- | ------------------- | -------- | --------------------------------- |
| `authorizedCA` | `array` of `string` | Yes | List of authorized CA public keys |
#### `GitHubActions`
[Section titled “GitHubActions”](#githubactions)
* **Type:** `object`
Verifies daemons using a GitHub Actions OIDC token. The runner fetches the token from the Actions token endpoint (`ACTIONS_ID_TOKEN_REQUEST_URL`) and the control plane validates it against GitHub’s public JWKS.
| Field | Type | Required | Description |
| -------------- | -------- | -------- | ---------------------------------------------------------------------------------------------------- |
| `audience` | `string` | **Yes** | Expected audience claim in the token (default: `riptides`; must match the action’s `audience` input) |
| `jwksURL` | `string` | No | Custom JWKS URL (default: `https://token.actions.githubusercontent.com/.well-known/jwks`) |
| `jwksCacheTTL` | `string` | No | Cache duration for JWKS keys (e.g. `300s`) |
| `iatLeeway` | `string` | No | Allowed clock skew for the `iat` claim (e.g. `60s`) |
Scoping to specific orgs, repositories, environments, or branches is done with the Verifier’s [`requiredMetadata`](#requiredmetadata) selectors against the `githubactions:*` metadata below - not with fields on the verifier itself, mirroring the AWS/GCP/Azure verifiers.
Danger
`requiredMetadata` is required for GitHub Actions verifiers. Omitting it causes the Verifier to be rejected at admission time. Without it, any GitHub Actions workflow across all of GitHub could authenticate.
#### `JWT`
[Section titled “JWT”](#jwt)
* **Type:** `object`
Verifies daemons using a generic JWT.
| Field | Type | Required | Description |
| ------------- | ------------------- | -------- | ------------------------------------------------------------------------ |
| `issuer` | `string` | Yes | Expected token issuer |
| `audience` | `string` | No | Expected audience claim |
| `jwksSource` | `object` | No | JWKS source: `inline` (string) or `remote` (`{url, minRefreshInterval}`) |
| `metadataMap` | `map[string]string` | No | Mapping of JWT claims to daemon metadata keys |
| `iatLeeway` | `string` | No | Allowed clock skew (e.g., `60s`) |
### Common Fields
[Section titled “Common Fields”](#common-fields)
#### `requiredMetadata`
[Section titled “requiredMetadata”](#requiredmetadata)
* **Type:** `array` of objects (free-form key-value pairs)
* **Required:** No
Restricts which daemons this verifier will accept. Each entry is a key-value group that must all match the daemon’s metadata derived from its authentication proof (AND within a group, OR across groups). For example, an AWSIID verifier can require a specific AWS account ID.
Commonly used keys by verifier type:
| Verifier | Key | Description |
| ------------- | ------------------------------------ | --------------------------- |
| AWSIID | `awsiid:account:id` | AWS account ID |
| AWSIID | `awsiid:region` | AWS region |
| GCPIIT | `gcpiit:project:id` | GCP project ID |
| GCPIIT | `gcpiit:zone` | GCP zone |
| AzureIMDS | `azureimds:subscription:id` | Azure subscription ID |
| AzureIMDS | `azureimds:resource_group` | Azure resource group |
| GitHubActions | `githubactions:repository:owner` | GitHub org or user |
| GitHubActions | `githubactions:repository:full_name` | Full repo name (`org/repo`) |
| GitHubActions | `githubactions:workflow` | Workflow name |
| GitHubActions | `githubactions:environment` | Deployment environment |
| GitHubActions | `githubactions:ref` | Git ref |
| GitHubActions | `githubactions:actor` | User that triggered the run |
| GitHubActions | `githubactions:run:id` | Unique per workflow run |
See [Node Attestation](../../concepts/node-attestation) for the complete metadata label list produced by every verifier type.
#### `workloadIDTemplate`
[Section titled “workloadIDTemplate”](#workloadidtemplate)
* **Type:** `string`
* **Required:** No
A Go template string used to automatically generate the `workloadID` for daemons that match this verifier. Template variables are populated from the daemon’s authentication metadata.
## Status
[Section titled “Status”](#status)
| Field | Type | Description |
| --------- | -------- | ---------------------------------------------- |
| `state` | `string` | One of `Unspecified`, `Available`, `Failed` |
| `message` | `string` | Human-readable status message (set on failure) |
## Examples
[Section titled “Examples”](#examples)
### AWS Instance Identity Document Verifier
[Section titled “AWS Instance Identity Document Verifier”](#aws-instance-identity-document-verifier)
Accepts daemons from a specific AWS account:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: awsiid
namespace: riptides-system
spec:
AWSIID: {}
requiredMetadata:
- awsiid:account:id: "123456789012"
```
### GCP Instance Identity Token Verifier
[Section titled “GCP Instance Identity Token Verifier”](#gcp-instance-identity-token-verifier)
Accepts daemons from a specific GCP project:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: gcpiit
namespace: riptides-system
spec:
GCPIIT:
audience: gcp-iit
requiredMetadata:
- gcpiit:project:id: my-gcp-project-123456
```
### Azure IMDS Verifier
[Section titled “Azure IMDS Verifier”](#azure-imds-verifier)
Accepts daemons from a specific Azure subscription:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: azureimds
namespace: riptides-system
spec:
AzureIMDS: {}
requiredMetadata:
- azureimds:subscription:id: "00000000-0000-0000-0000-000000000000"
```
### GitHub Actions Verifier
[Section titled “GitHub Actions Verifier”](#github-actions-verifier)
Accepts runners from a specific GitHub organisation, restricted to the `main` branch:
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: github-actions
namespace: riptides-system
spec:
GitHubActions:
audience: riptides
requiredMetadata:
- githubactions:repository:owner: your-org
githubactions:ref: refs/heads/main
```
### Join Token Verifier
[Section titled “Join Token Verifier”](#join-token-verifier)
Accepts daemons that present a valid pre-shared token (useful for development):
```yaml
apiVersion: auth.riptides.io/v1alpha1
kind: Verifier
metadata:
name: jointoken
namespace: riptides-system
spec:
joinToken: {}
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [Daemon](../daemon) - daemons authenticate through verifiers
* [JoinToken](jointoken.md) - defines pre-shared tokens used with the `joinToken` verifier type
# WorkloadIdentity
WorkloadIdentity is the core resource in Riptides. It defines a cryptographic identity for a workload, determining its SPIFFE ID, how the workload is matched on a host, what TLS policy applies, and which other identities it is allowed to communicate with.
* **API Group:** `core.riptides.io`
* **Version:** `v1alpha1`
* **Kind:** `WorkloadIdentity`
* **Plural:** `workloadidentitys`
## Spec
[Section titled “Spec”](#spec)
### `workloadID`
[Section titled “workloadID”](#workloadid)
| | |
| ------------ | -------- |
| **Type** | `string` |
| **Required** | Yes |
A hierarchical identifier for this workload. Combined with the trust domain, it forms the workload’s SPIFFE ID:
```plaintext
spiffe:///
```
For example, a `workloadID` of `myapp/backend/api` in the trust domain `example.com` produces the SPIFFE ID `spiffe://example.com/myapp/backend/api`.
### `scope`
[Section titled “scope”](#scope)
| | |
| ------------ | -------- |
| **Type** | `object` |
| **Required** | Yes |
Determines which daemon or daemon group this identity is scoped to. Exactly one of the following must be set:
* **`daemon.id`** (`string`) — Scope to a single daemon by its ID.
* **`daemonGroup.id`** (`string`) — Scope to a daemon group by its ID. All daemons in the group will serve this identity.
### `selectors`
[Section titled “selectors”](#selectors)
| | |
| ------------ | --------------------------- |
| **Type** | `array` of selector objects |
| **Required** | Yes |
Selectors define the criteria a daemon uses to match a running process to this identity. Each selector object contains key-value pairs that must all match for the workload to be identified. Multiple selector objects in the array are evaluated with OR logic (any match is sufficient). A key within an object can also list multiple values; the process matches if it has any one of them.
Commonly used selector keys:
| Key | Description |
| ------------------------ | ----------------------------------------- |
| `process:name` | Name of the running process binary. |
| `process:cmdline` | Full command line of the process. |
| `k8s:pod:name` | Kubernetes pod name. |
| `k8s:pod:namespace` | Kubernetes pod namespace. |
| `k8s:pod:serviceaccount` | Kubernetes pod’s service account name. |
| `k8s:container:name` | Kubernetes container name within the pod. |
| `k8s:label:` | Kubernetes pod label value. |
| `k8s:annotation:` | Kubernetes pod annotation value. |
| `docker:name` | Docker container name. |
| `docker:label:` | Docker container label value. |
| `ec2:instance:id` | AWS EC2 instance ID. |
| `ec2:placement:region` | AWS region. |
| `gcp:instance:id` | GCP Compute Engine instance ID. |
| `gcp:project:id` | GCP project ID. |
| `azure:subscription:id` | Azure subscription ID. |
| `linuxos:name` | Linux distribution name. |
See [Workload Attestation](../../concepts/workload-attestation) for the complete metadata label list produced by every collector, and for host-scoped vs. process-scoped selector behavior.
### `svid`
[Section titled “svid”](#svid)
| | |
| ------------ | -------- |
| **Type** | `object` |
| **Required** | No |
Configures the SVID (SPIFFE Verifiable Identity Document) issued to this workload.
* **`x509`** — X.509 SVID settings.
* `dnsNames` (`array` of `string`) — Additional DNS SANs to include in the certificate.
* `ttl` (`string`, pattern `^\d+s$`) — Time-to-live for the X.509 certificate (e.g., `3600s`).
* **`jwt`** — JWT SVID settings.
* `ttl` (`string`, pattern `^\d+s$`) — Time-to-live for JWT SVIDs (e.g., `300s`).
### `connection`
[Section titled “connection”](#connection)
| | |
| ------------ | -------- |
| **Type** | `object` |
| **Required** | No |
Default connection policy for this workload’s inbound traffic.
* **`protocol`** (`string`) — Application protocol hint. Set to `HTTP1` to enable in-kernel HTTP/1 request inspection, which is required for HTTP-level features such as credential injection and the ingress `httpRequestPath` allowlist. Defaults to unset (no HTTP inspection).
* **`tls.mode`** (`string`) — TLS mode. When unset, inbound traffic defaults to `PERMISSIVE` (so existing plaintext callers keep working during enrollment); outbound (egress) connections are always upgraded to mutual TLS regardless of mode, since Riptides initiates them. Valid options:
* `SIMPLE` — Server-side TLS only (workload presents its certificate; client is not verified).
* `MUTUAL` — Mutual TLS (both sides present and verify certificates).
* `PERMISSIVE` — Accept both plaintext and mTLS connections. Useful during migration.
* **`tls.intercept`** (`boolean`, nullable) — When `true`, the Riptides kernel module transparently intercepts connections to upgrade them to TLS.
* **`tls.skipVerification`** (`boolean`, nullable) — When `true`, skip peer certificate verification (not recommended for production).
### `allowedSPIFFEIDs`
[Section titled “allowedSPIFFEIDs”](#allowedspiffeids)
| | |
| ------------ | -------- |
| **Type** | `object` |
| **Required** | No |
Defines the default set of SPIFFE IDs this workload is authorized to communicate with.
* **`inbound`** (`array` of `string`) — SPIFFE IDs allowed to connect *to* this workload.
* **`outbound`** (`array` of `string`) — SPIFFE IDs this workload is allowed to connect *to*.
### `ingress`
[Section titled “ingress”](#ingress)
| | |
| ------------ | ------------------------------- |
| **Type** | `array` of ingress rule objects |
| **Required** | No |
Per-port inbound connection policies. Each entry overrides the default `connection` and `allowedSPIFFEIDs` for a specific listening port.
* **`port`** (`integer`, required) — The listening port number.
* **`connection`** (`object`) — Connection settings for this port (same schema as top-level `connection`).
* **`allowedSPIFFEIDs`** (`array` of `string`) — SPIFFE IDs permitted on this port.
* **`svid`** (`object`) — Per-port SVID overrides (same schema as top-level `svid`).
* **`workloadID`** (`string`) — Optional workload ID override for this ingress port.
* **`httpRequestPath`** (`array` of `string`) — Restricts which HTTP request paths an **unauthenticated** client (one presenting no valid SPIFFE/mTLS identity — for example a plaintext caller on a `PERMISSIVE` port) may reach on this port. Only the listed paths are forwarded to the application; any other request — or anything that is not a recognizable HTTP/1 request — is reset, the same outcome a `MUTUAL` port gives an unauthenticated caller. Clients that present a valid mTLS identity are not restricted and reach every path. An empty or omitted list imposes no restriction — the `PERMISSIVE` port then behaves as usual; use `MUTUAL` if you want identity required on every path. Requires the connection `protocol` to be `HTTP1` (set on the ingress or inherited from the top-level `connection`); otherwise the resource is rejected at admission. Each entry must be a unique, absolute path with no query string or fragment (also enforced at admission). Matching is exact and ignores the query string — `/healthz` matches `/healthz` and `/healthz?t=1`, but not `/healthz/` or `/healthz/live`. The common use is exposing health and readiness probes without mTLS while keeping every other path identity-gated.
### `egress`
[Section titled “egress”](#egress)
| | |
| ------------ | ------------------------------ |
| **Type** | `array` of egress rule objects |
| **Required** | No |
Egress rules define how this workload connects to downstream services. Each rule targets one or more services (matched by label selectors) and can override the default connection policy, allowed SPIFFE IDs, SVID settings, and workload ID on a per-service basis.
* **`selectors`** (`array` of selector objects, required) — Label selectors that match against [Service](../service) labels to identify the target services.
* **`connection`** (`object`) — TLS/connection settings for outbound connections to matched services.
* **`allowedSPIFFEIDs`** (`array` of `string`) — SPIFFE IDs of the expected remote peers.
* **`svid`** (`object`) — Per-egress SVID overrides.
* **`workloadID`** (`string`) — Optional workload ID override for this egress rule.
## Status
[Section titled “Status”](#status)
WorkloadIdentity resources do not expose a status subresource. The daemon resolves the identity assignment based on scope and selectors and reports operational state through other system resources.
## Examples
[Section titled “Examples”](#examples)
### Basic workload identity with mTLS
[Section titled “Basic workload identity with mTLS”](#basic-workload-identity-with-mtls)
A simple workload identity for a backend service, scoped to a daemon group, with permissive TLS and inbound/outbound access control:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: cartservice
namespace: riptides-system
spec:
workloadID: myapp/app/cartservice
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: cartservice
k8s:pod:namespace: myapp
process:name: cartservice
connection:
tls:
mode: PERMISSIVE
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/myapp/app/frontend
- spiffe://example.com/myapp/app/checkoutservice
outbound:
- spiffe://example.com/myapp/app/redis-cart
```
### Workload with TLS intercept for credential injection
[Section titled “Workload with TLS intercept for credential injection”](#workload-with-tls-intercept-for-credential-injection)
A workload that connects to external APIs with transparent TLS interception. Credential injection is configured in the associated [CredentialBinding](../credentialbinding) resources.
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: support-assistant
namespace: riptides-system
spec:
workloadID: support-assistant/app/assistant-api
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: support-assistant
k8s:pod:namespace: support-assistant
process:name: node
connection:
tls:
mode: PERMISSIVE
intercept: true
```
### Workload with per-port ingress rules
[Section titled “Workload with per-port ingress rules”](#workload-with-per-port-ingress-rules)
A workload that exposes multiple ports with different TLS policies per port:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: control-center
namespace: riptides-system
spec:
workloadID: platform/control-center
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/infra
selectors:
- k8s:container:name: control-center
k8s:label:app.kubernetes.io/component: control-center
process:name: java
connection:
tls:
mode: PERMISSIVE
ingress:
- port: 9021
connection:
tls:
mode: PERMISSIVE
- port: 8080
connection:
tls:
mode: MUTUAL
allowedSPIFFEIDs:
- spiffe://example.com/platform/control-center
egress:
- allowedSPIFFEIDs:
- spiffe://example.com/platform/kafka-broker
connection:
tls:
mode: PERMISSIVE
selectors:
- app: kafka-cluster-encrypted-listeners
- connection:
tls:
mode: SIMPLE
selectors:
- app: external-analytics
allowedSPIFFEIDs:
inbound:
- spiffe://example.com/platform/control-center/health-check
```
### Allowing unauthenticated health probes on specific paths
[Section titled “Allowing unauthenticated health probes on specific paths”](#allowing-unauthenticated-health-probes-on-specific-paths)
A workload that requires mTLS in general but lets unauthenticated health probes reach `/healthz` and `/readyz` over plaintext. Port 8080 runs `PERMISSIVE` (so the identity-less probe is accepted) with `protocol: HTTP1`, and `httpRequestPath` limits unauthenticated callers to the probe endpoints — every other path on the port still requires a verified identity:
```yaml
apiVersion: core.riptides.io/v1alpha1
kind: WorkloadIdentity
metadata:
name: api-server
namespace: riptides-system
spec:
workloadID: myapp/app/api-server
scope:
daemonGroup:
id: daemongroup/prod-us-east-1/workers
selectors:
- k8s:label:app: api-server
k8s:pod:namespace: myapp
connection:
tls:
mode: MUTUAL # omit to default to PERMISSIVE (inbound); egress is always strict
ingress:
- port: 8080
connection:
protocol: HTTP1
tls:
mode: PERMISSIVE # accept plaintext probes on this port
httpRequestPath:
- /healthz
- /readyz
allowedSPIFFEIDs:
- spiffe://example.com/myapp/app/frontend
```
## Related Resources
[Section titled “Related Resources”](#related-resources)
* [CredentialBinding](../credentialbinding) — Bind credentials to this workload for injection using `CredentialBinding.propagation.injection` selectors.
* [CredentialSource](../credentialsource) — Define where credentials come from.
* [Service](../service) — Define the services that egress selectors match against.
* [API Reference Overview](../overview)